Large clusters for small models — Daniel Svonava, Superlinked
Daniel Svonava argues that small open-source models, when specialized and properly served, can achieve frontier performance for specific tasks, offering significant cost savings and latency improvements over large, generalized models or managed endpoints. He highlights challenges with existing serving infrastructure for a fleet of diverse small models and introduces Superlinked's open-source solution, which leverages a pull-based, centralized queuing system, a Rust sidecar for runtime abstraction, and an autoresearch loop for automated model tuning, enabling high throughput (e.g., half a million embedding tokens/sec on one GPU) and efficient deployment of specialized models and LoRAs.
Daniel Svonava from Superlinked advocates for small open-source models, highlighting their current ability to achieve frontier or even superior performance for specific tasks. These models are defined by their ability to run on 2-3 generations old Nvidia hardware, fitting on a single GPU, making them accessible and cost-effective. He notes a “convergence saturation” where large frontier models show diminishing returns, while smaller models rapidly advance; for example, a model like Qwen 3627b can match the performance of GPT 3.5 for certain workflows.
The core strategy involves specializing workloads: breaking down generalized problems into specific tasks and selecting the most appropriate open-source model for each. This approach leads to agents composed of multiple specialized models—a contract review agent, for instance, might leverage nine distinct models. The speaker emphasizes that highly specialized models, such as one trained specifically for Vietnamese receipt OCR, will vastly outperform general-purpose models on their particular niche, given the vast datasets they’ve seen. Hundreds of thousands of such models are freely available, but the primary bottleneck is not their existence, but efficiently serving a diverse fleet of them.
Svonava identifies three significant challenges with current inference serving infrastructure when dealing with numerous small, diverse models:
- Untuned Open Source Serving Tools: Existing tools like vLLM and SGLang are not pre-tuned for specific model-hardware combinations. Adopting them transforms into an extensive “research project” demanding manual tuning, parameter sweeps, and traffic tailoring, which impedes rapid deployment.
- Top-Down Routers Choke on Small Requests: Traditional inference clusters, designed for serving a single large model across GPUs with a router managing worker state, struggle with the high volume of small, fast requests from specialized models. The router’s view of worker state quickly becomes obsolete, preventing optimal GPU saturation and often leading to utilization rates of only 20-30%.
- LoRAs and Fine-Tunes Kill Organizational Velocity: The ease and effectiveness of adapting small models via LoRAs and fine-tuning lead to constant communication and requests from AI engineers to infrastructure teams. This perpetual “conversation” introduces friction, slowing down deployments and hindering overall agility.
Superlinked’s answer is an open-source (Apache 2.0) serving architecture that covers the entire stack. Key components include:
- A Gateway: This component performs minimal parsing of incoming requests, annotates them with metadata, and places them into a shared queue. To avoid becoming a bottleneck, it offloads large multimodal data to cloud storage while requests are queued, passing only references.
- A Shared Queue: Utilizing NATS JetStream, this centralized queue is designed to handle millions of requests per second.
- Pull-Based Workers: Instead of a router pushing requests, workers actively pull tasks from the shared queue, allowing them to self-saturate more effectively and form their own optimal batches. This architectural inversion has been shown to double cluster throughput. For multi-GPU machines, a local queueing element further optimizes re-batching without network latency.
The Superlinked stack is predominantly built in Rust, featuring a Rust sidecar that abstracts complexity by supporting approximately 50 different model adapters across various runtimes, including PyTorch, Kendall (explored for its smaller footprint), and SGLang. Their optimized batching logic, even when wrapping SGLang, can surpass the performance of a bare SGLang setup.
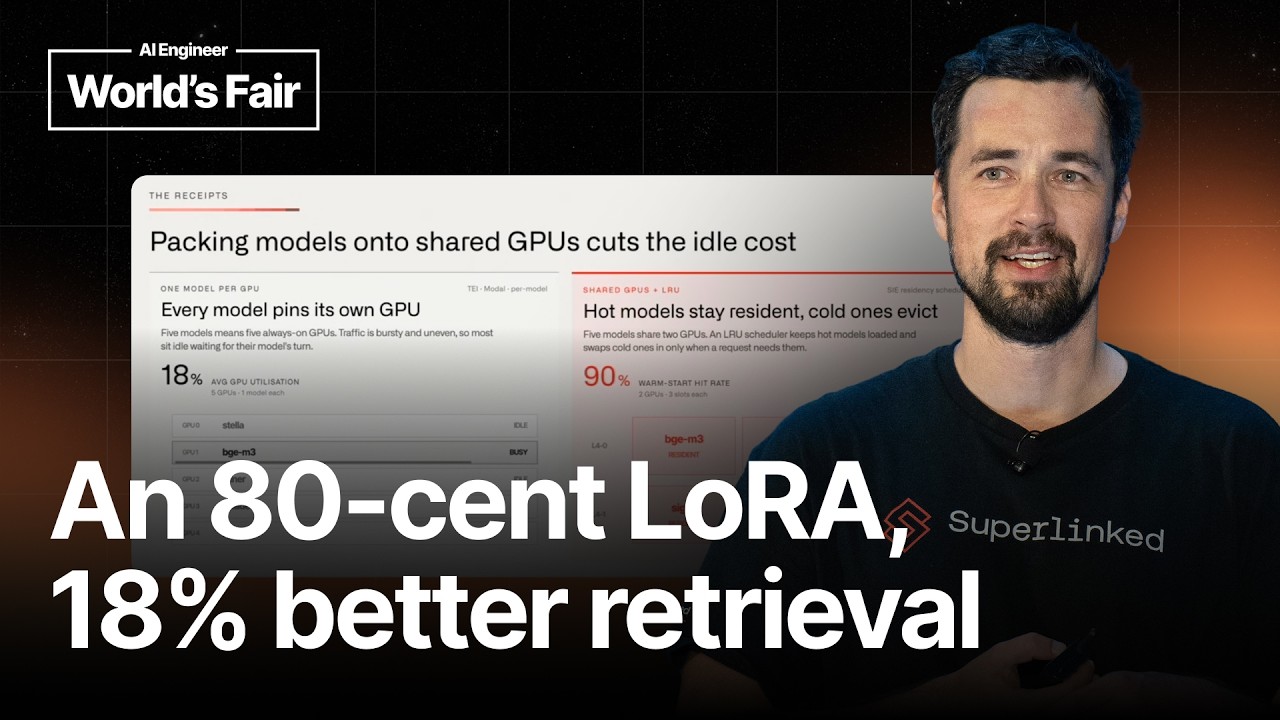
In terms of performance and automation: The system efficiently runs on readily available mid-range GPUs (e.g., RTX Pro 6000, Nvidia L4s). For embedding models, a single RTX Pro 6000 can process half a million tokens per second, generating embeddings in tens of milliseconds, offering massive cost savings and latency improvements over managed services. Task-specific generative models also achieve thousands of tokens per second. The architecture supports packing multiple small models onto a single GPU through a combination of pinning frequently used models and lazy loading with memory-based eviction.
Superlinked also employs autoresearch loops—internal systems that automatically add support for new models and optimize their performance. These loops measure, evaluate, and tune configurations, ensuring that every deployed model comes with a fully optimized, end-to-end cluster configuration, eliminating the need for manual parameter sweeps. A notable outcome of this autoresearch was an 80-cent LoRA that boosted retrieval quality on German legal texts by 18%.
Svonava concludes by affirming that small open-source models are