Distributed systems

Why AI Can Write Code But Can’t Keep It Running (Yet)

Why AI Can Write Code But Can’t Keep It Running (Yet)

Grepr CEO Jad Naous talks with a16z's Martin Casado about how coding agents have changed a 10-person engineering team, with projects that once took six months now finishing in about ten days. They examine whether AI can reason about and troubleshoot production distributed systems, why operations is a harder problem than code generation, and where AI adoption is likely to go next.
The Index is never done

The Index is never done

Exa's Jon details how their company maintains a massive, continuously updated semantic index of 100 billion pages to serve AI agents. The talk covers Exa's unique incremental indexing system, a custom data processing framework called "Skeleton" that handles 100,000 pages per second, and "Pythia," an elastic, cost-aware GPU orchestration system for managing both real-time ingestion and large-scale index re-embeddings.

We Mapped 115 Microservices for Our Coding Agents — Kamalakannan Nandagopal, Postman

We Mapped 115 Microservices for Our Coding Agents — Kamalakannan Nandagopal, Postman

Kamalakannan Nandagopal from Postman explains why coding agents struggle beyond a single repo and how an API context graph, grounded in code and production telemetry, gives agents system-wide awareness. The talk covers evals built from real PRs, wins on API discovery, redesign and impact assessment, a stale-graph failure, and a 21-page architecture review generated by the agent.

Your Agents Are in Solitary Confinement: Why MCP & A2A Aren't Enough — Vlad Luzin, Band

Your Agents Are in Solitary Confinement: Why MCP & A2A Aren't Enough — Vlad Luzin, Band

Vlad Luzin, co-founder and CTO of Band, argues that connecting AI agents is a distributed systems problem that current tools such as MCP, A2A and messaging platforms do not solve. He lays out what is required for real agent collaboration, including ordered real-time transport, persistence, runtime binding, agent-first abstractions and governance, then demonstrates Codex, LangGraph and Claude Code agents finding and working with each other under full human-in-the-loop visibility.

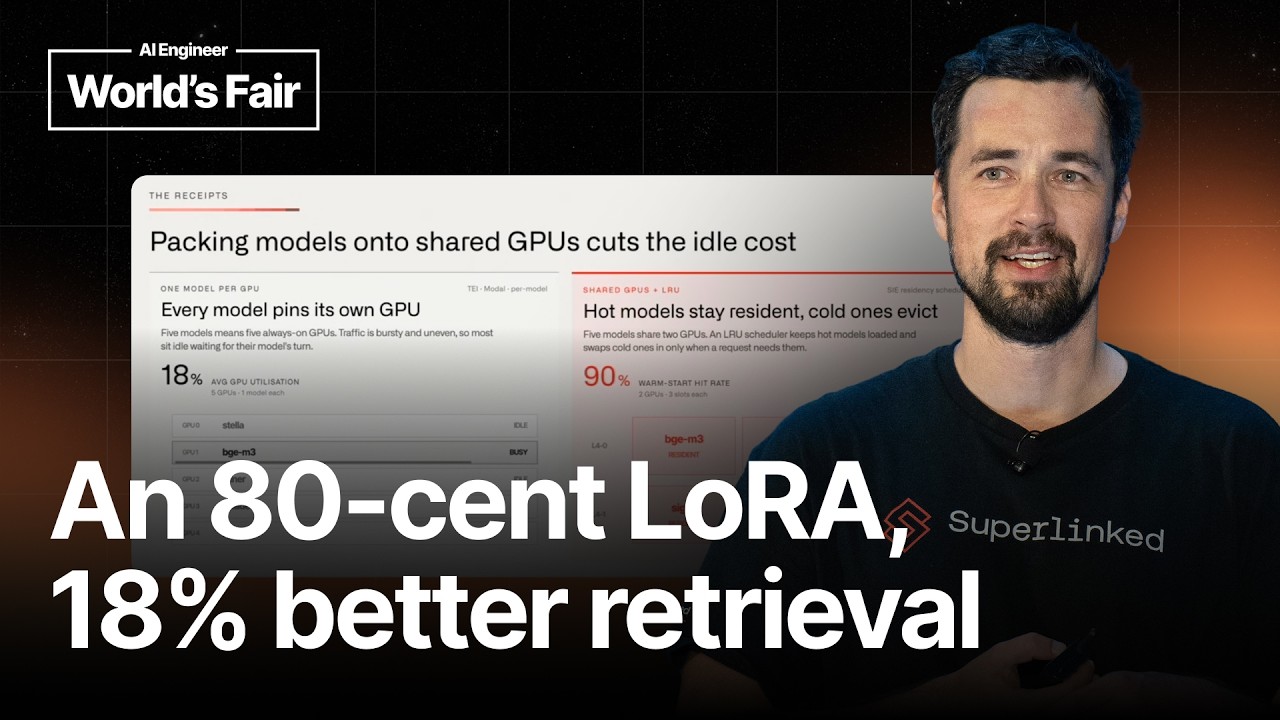
Large clusters for small models — Daniel Svonava, Superlinked

Large clusters for small models — Daniel Svonava, Superlinked

Daniel Svonava argues that small open-source models, when specialized and properly served, can achieve frontier performance for specific tasks, offering significant cost savings and latency improvements over large, generalized models or managed endpoints. He highlights challenges with existing serving infrastructure for a fleet of diverse small models and introduces Superlinked's open-source solution, which leverages a pull-based, centralized queuing system, a Rust sidecar for runtime abstraction, and an autoresearch loop for automated model tuning, enabling high throughput (e.g., half a million embedding tokens/sec on one GPU) and efficient deployment of specialized models and LoRAs.

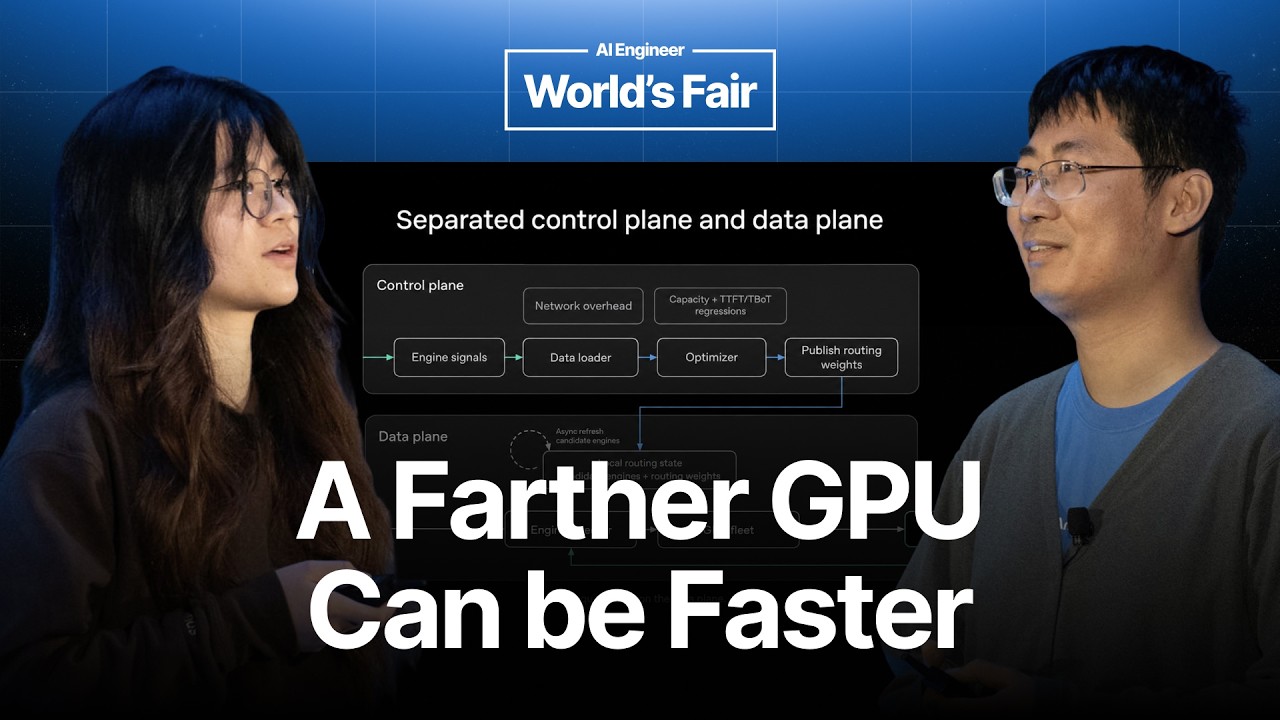
Routing LLM Inference in Production: From Engine Signals to Policy — Qianru Lao & Lu Zhang, OpenAI

Routing LLM Inference in Production: From Engine Signals to Policy — Qianru Lao & Lu Zhang, OpenAI

This talk outlines OpenAI's journey in building a robust inference load balancer. It details the transition from an initial feedback-loop-driven system, which suffered from explainability issues and disruptive oscillations, to a sophisticated control plane/data plane architecture. The new system leverages a global view to optimize end-to-end latency across all traffic, balancing network distance with engine-side queuing, and includes critical protection mechanisms like outlier penalties, dynamic retry budgets, and load shedding to ensure stability in production.