How to Write Your First AI Eval - SallyAnn DeLucia, Arize AI
A hands-on workshop from Arize AI on moving from vibe checks to real LLM evals. It covers what an eval is and how it differs from a unit test, the main eval types, how to read agent traces, how to write concrete pass/fail criteria, and how to build and iterate on an LLM-as-a-judge in Arize's prompt playground.
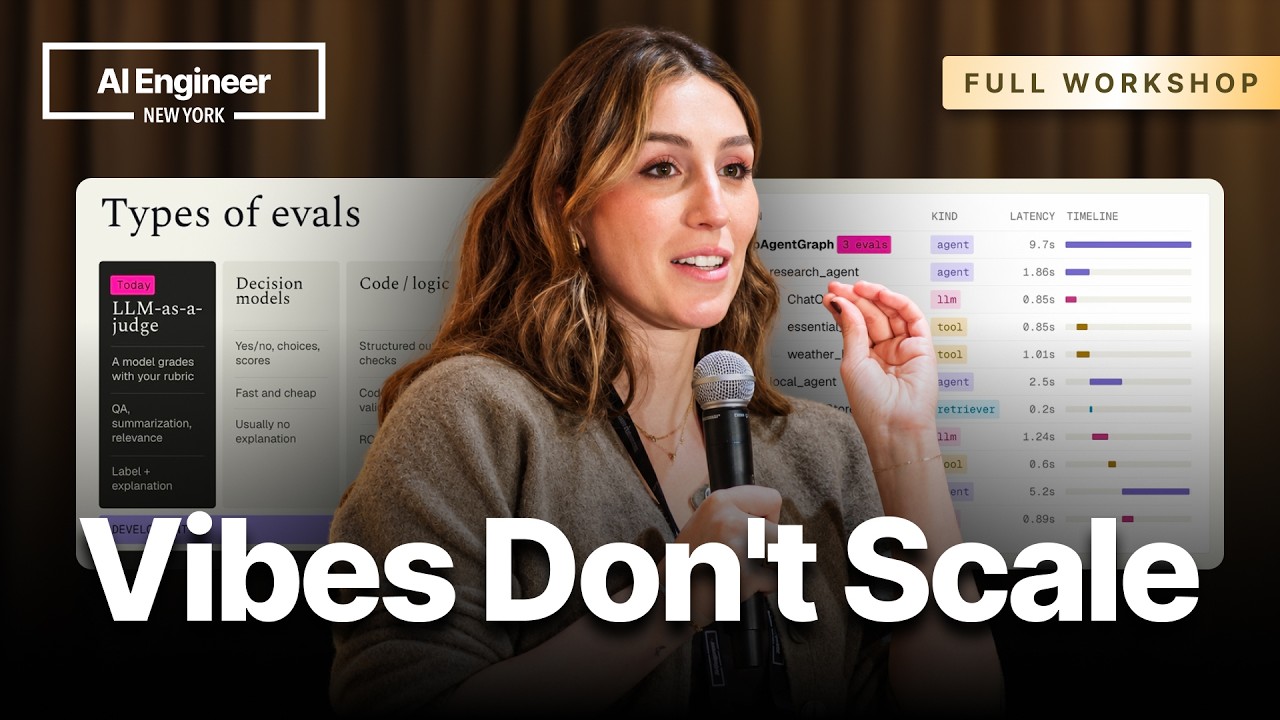
Evals are the primary signal for AI agents, and without them teams are stuck relying on vibe checks. A prompt change that feels better on Monday can break a use case by Wednesday, and nobody can prove whether a fix held or a regression crept in. Evals make it possible to detect regressions when a prompt changes, compare prompts or model versions objectively, and place real quality gates in CI before an agent ships.
What an eval is, and what it isn’t
Evals differ from traditional unit tests in a fundamental way. A unit test has one input and one correct output, and its logic can be read directly from the code. An agent’s logic cannot be read from the code. It emerges at runtime and only becomes visible in traces. A travel planner can return many valid itineraries that differ in their day-by-day structure and budget breakdown, so evaluation has to judge multiple criteria rather than match a single expected string. Traces are the logs for AI systems and evals are the tests, which makes observability a prerequisite for evaluation.
A trace is the full set of steps an agent took to produce a response. The root span (parent ID null) holds the top-level input and final output. Each child span is a unit of work: agent spans, tool spans that fetch external data such as weather or site information, and LLM spans that either choose a tool or summarize a tool’s output. Multi-agent systems, where a supervisor or sub-agents divide work, produce deeper trees, and reading them means following parent-child links step by step. Tracing is framework-agnostic through OpenInference auto-instrumentation, and custom spans can be added with manual or hybrid instrumentation.
Types of evals
- LLM as a judge: a secondary LLM grades one aspect of the agent’s output (QA correctness, summarization, relevance) and returns a label plus an explanation. The explanation exposes the reasoning behind the label, so the label doesn’t have to be taken at face value.
- Decision models: a newer approach that answers a question and returns a probability along with a true/false or categorical label. They are cheap and fast, but they don’t produce the explanation an LLM judge does.
- Code evals: deterministic checks, such as whether a word appears in the output or whether the output is valid JSON, along with metrics like ROUGE and BLEU.
- Annotations: human-labeled golden truths on golden datasets, sometimes synthetic.
- Agent as a judge: a full agent evaluates another agent’s output, which suits complex success criteria.
- User feedback and business metrics: production signals.
The first four are meant to span both development and production, so evals can grow with the use case rather than being discarded after development.
Defining good and writing criteria
Vague standards like ‘helpful, accurate, good response’ don’t produce useful evals. Concrete criteria do: the answer follows the user’s follow-up questions, matches the requested number of days, and keeps totals within the stated budget. Two rules guide this. First, judge one quality per eval. LLM judges handle a single criterion well and multiple criteria poorly, while decision models and agent judges tolerate multiple criteria better. Second, treat evals as iterative. Start with a small set and add more as production data reveals new failure modes. Arize’s own agent, Alex, began with QA correctness, user frustration, and jailbreak and toxicity safety checks, and has since grown to 32 evals grounded in production data.
A generic, reusable eval is better than none, and out-of-the-box templates such as QA correctness, hallucination, and session coherence are good starting points. Use-case-specific evals become more valuable as the application matures.
A useful criteria write-up includes the task being judged, what success looks like, what failure looks like, and three bullets each for pass and fail. For example, the task might be a user follow-up about the trip, success is answering the follow-up directly using the trip’s details, and failure is falling back to a generic budget. The bullets matter because they become the substance of the LLM judge prompt, so criteria should be written as if describing success to a coworker or stakeholder.
Reading traces and building a dataset
The travel planning agent takes a trip request (destination, duration, budget, travel style) and returns an itinerary. Reviewing its traces means asking what users request, what each tool does, what the answers look like, and whether a given answer would be shared with a real user. In the example trace, a three-day Prague trip on an $800 budget asked for something more local and less touristy, and the agent produced a detailed day-by-day plan. Those kinds of observations are what turn into measurable criteria.
To build an eval dataset, filter spans by what is being judged. Root spans (parent ID equals null) are the right choice for checking whether an itinerary reflects the original input, while specific tool-call spans, filtered by name, are the right choice for checking whether a tool returned the information it was supposed to. The selected spans are saved into a dataset that the judge will run against.
Building and iterating on an LLM judge in the playground
In Arize AX’s prompt playground, the judge prompt is assembled in stages. It opens with an introduction that centers the LLM as an evaluator of whether the output accurately captures the requested details. It then references the data to evaluate through variable mapping, so the prompt doesn’t hard-code trace attribute names and can be pointed at different datasets or traces without rewriting every eval. Next come the pass and fail criteria, then the labels. Labels can be binary (correct or incorrect) or multi-label, such as partially correct or not applicable. An optimization direction states whether a higher or lower score is better, and the judge must provide an explanation for its label.
Once the dataset is loaded and the judge runs against a chosen model (GPT-4.1 mini in the demo), results appear inline. The iteration loop is to read the outputs, decide whether you agree with each label, adjust the prompt, and rerun. When the template is stable, it can be saved as an evaluator and reused across the platform. Alex can also run this loop: it can execute the playground, read the results, update the prompt, and repeat.
The eval lifecycle beyond the first judge
- Alignment: annotate the dataset examples by hand and check whether the judge agrees with human feedback.
- Online evals: attach the evaluator to a task so every incoming trace is scored continuously, which enables monitoring in production.
- Signal: Arize’s managed agent, which reviews traces, surfaces issues, and can propose fixes that feed back into the application.
- Decision judges: convert an existing LLM judge into a decision-model question and compare performance between the two.
Metrics indicate that something may be broken, while evals identify the actual failure mode, so both are needed. Evaluation shouldn’t belong to one role. Product, engineering, support, domain experts, and security each have a stake in what success means, and each should define it in terms of their own outcomes. The recommended way to begin is small: around 20 traces, one dimension, one judge. Read the explanations, iterate on the prompt, and expand from there.