Routing LLM Inference in Production: From Engine Signals to Policy — Qianru Lao & Lu Zhang, OpenAI
This talk outlines OpenAI's journey in building a robust inference load balancer. It details the transition from an initial feedback-loop-driven system, which suffered from explainability issues and disruptive oscillations, to a sophisticated control plane/data plane architecture. The new system leverages a global view to optimize end-to-end latency across all traffic, balancing network distance with engine-side queuing, and includes critical protection mechanisms like outlier penalties, dynamic retry budgets, and load shedding to ensure stability in production.
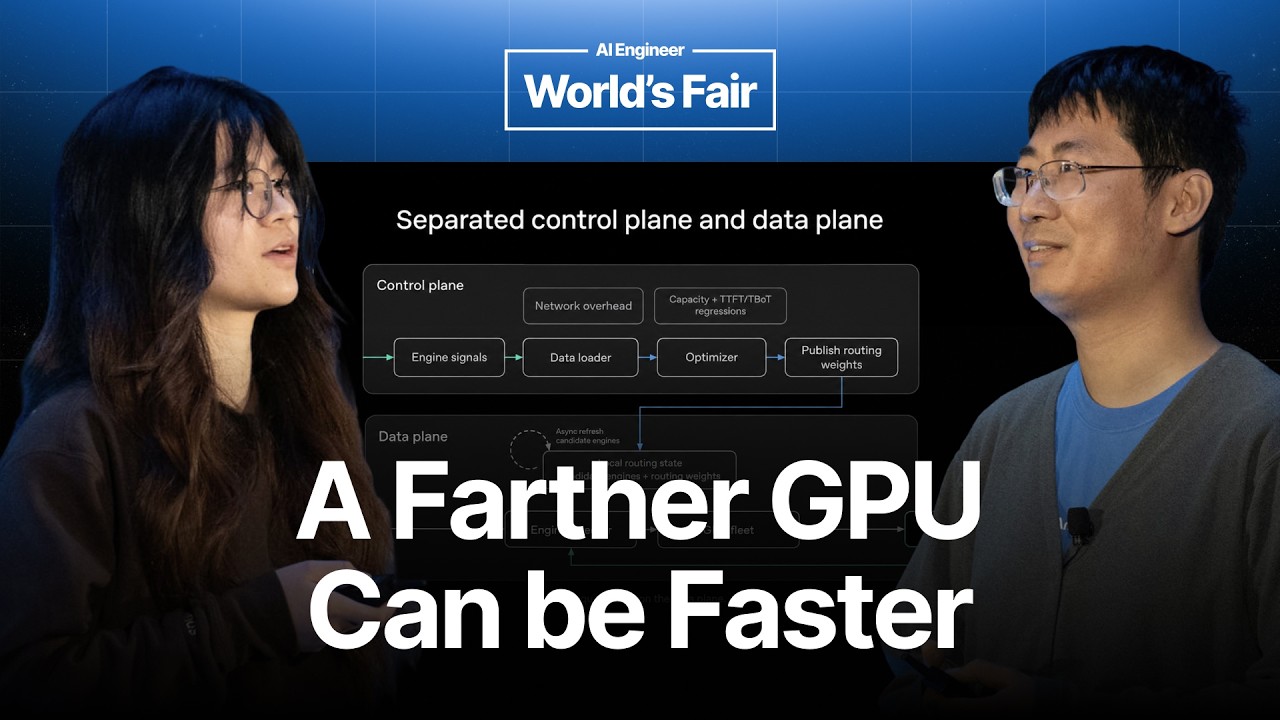
OpenAI’s inference load balancing system has undergone significant evolution, moving from a feedback-loop-driven approach to a more explicit and predictable policy, though still informed by engine signals. The primary goal is to efficiently route user requests (from CPU clusters acting as gateways) to GPU-based inference engines, considering factors like performance, reliability, and most crucially, KV cache locality.
Evolution of Routing: From Feedback Loops to Explicit Policy
Early Approach: Weighted Consistent Hashing with Feedback Loop
Initially, the Inference Load Balancer (ILB) used weighted consistent hashing to select the best destination engine. The weights were dynamically generated by a periodic feedback loop:
- Inference engines reported various signals (e.g., Time to First Token - TTFT, Time Between Output Tokens - TBOT, health, utilization).
- A controller smoothed these signals to compute a performance score.
- This score was compared against the fleet average, and the engine’s weight was adjusted proportionally: up if performance was better, down if worse.
- This system conceptually resembled a proportional (P) controller from classic control theory.
Advantages of the Feedback Loop:
- Signal Integration: Combined multiple useful signals into a single routing decision.
- Adaptability: Adapted to observed performance, allowing busy engines (e.g., serving more complex requests) to self-balance traffic.
- Low Maintenance: Required minimal manual intervention.
Limitations and Challenges:
- Lack of Explainability: Difficult to reason about specific routing decisions or why an engine received a particular weight.
- Interdependence: Tuning one property often inadvertently impacted others.
- Uneven Distribution: Problems arose with heterogeneous engine characteristics (e.g., different GPU skills).
- Oscillation: The most critical issue. Shifting traffic off a busy engine would cause it to “cool down.” The controller, perceiving spare capacity, would then route traffic back, leading to disruptive oscillations that wreaked havoc on KV cache utilization. This constant bouncing negated the very locality routing was designed to protect.
The New Architecture: Control Plane and Data Plane
Motivated by these limitations, OpenAI adopted a new architecture comprising a global Control Plane and local Data Planes.
Limitations of Simpler Approaches:
- Round-robin: Inefficient due to heterogeneous engines (hardware, capacity, health, distance) and breaks KV cache locality.
- Local View Only: Each CPU cluster selecting the best engine from its own local view could lead to global sub-optimality, such as overloading a single engine while others remain underutilized.
Core Principles of the New Architecture: The new system addresses this by requiring a globally optimized solution.
- Control Plane: Possesses a global view of all CPU clusters and GPU engines, continuously computing globally optimized routing answers.
- Data Plane: Resides within each CPU cluster, making rapid, synchronous routing decisions based on a cached snapshot of routing weights provided by the Control Plane.
Components and Workflow:
- Data Plane Responsibilities:
- Engine Selector: Selects an engine for each request.
- Local Routing State: Reads candidate engines and routing weights, refreshed asynchronously in the background.
- Local Guard Rails: Collects real-time engine signals (e.g., ready replicas, health) to apply fast, local protective measures.
- Control Plane Responsibilities:
- Data Loader: Combines live engine signals, network overheads, and offline regressions (capacity, TTFT, TBOT profiles).
- Optimizer: Processes the data loader’s output to compute new routing weights.
- Publication: Publishes updated routing weights for Data Planes to pull.
Three Important Paths through the System:
- Inference Request Path: Synchronous. Requests arrive at the CPU cluster, the Data Plane selects an engine based on its local, cached state, and forwards the request. This path is fast and local.
- Engine Signal Path: Asynchronous. Real-time engine signals (TTFT, TBOT, health) are continuously collected. Both the Control Plane (for global optimization) and Data Plane (for local guard rails) utilize these signals.
- Routing Weight Path: Asynchronous. The Control Plane computes and publishes routing weights, which Data Planes asynchronously pull and cache.
Why “Nearest Engine” is Not Sufficient: The optimizer accounts for end-to-end latency, which includes both network distance and engine-side queuing/processing time. A “nearest” engine might be faster in terms of network latency but significantly slower overall if it’s overloaded. Conversely, a geographically “further” engine might offer lower end-to-end latency if it has significant spare capacity, avoiding long queues at the closer, busy engine. This trade-off between network distance and engine-side waiting time is central to the optimization.
Inside the Optimizer: The optimizer acts as the “brain” of the Control Plane, taking various inputs and producing routing weights:
- Inputs:
- Request load from each CPU cluster.
- Network latency to every engine.
- Available engine capacity and health.
- TTFT/TBOT latency profiles: how engine-side latency changes with increasing load.
- Optimization Goal: Minimize the expected end-to-end latency across all routed traffic. This explicitly considers both network distance and engine-side latency.
- Hard Constraints:
- All traffic demand must be routed.
- All engines must operate within their effective capacity.
- Routing weights must be non-negative. The Control Plane then publishes these optimized routing weights, which are pulled by the Data Planes to make globally optimal routing decisions.
Protection Mechanisms for Production Stability
To ensure system stability under non-ideal production conditions (e.g., cluster failures, hardware degradation, network issues), several protection mechanisms are in place:
- Outlier Penalties: When an engine is detected as an outlier (e.g., degraded performance), its routing weight is reduced. This gives the engine a chance to recover or allows for human intervention (e.g., swapping out faulty hardware).
- Retry Budgets: To prevent “retry storms” (where retries exacerbate an already overloaded system), caps or budgets are implemented. These budgets are dynamic, allowing more retries during normal operation but tightening significantly when the system is heavily utilized.
- Load Shedding: As a last resort, if production capacity cannot meet demand, a portion of traffic is proactively shed. This prevents a complete system collapse, allowing for a graceful degradation of service.