Routing LLM Inference in Production: From Engine Signals to Policy — Qianru Lao & Lu Zhang, OpenAI
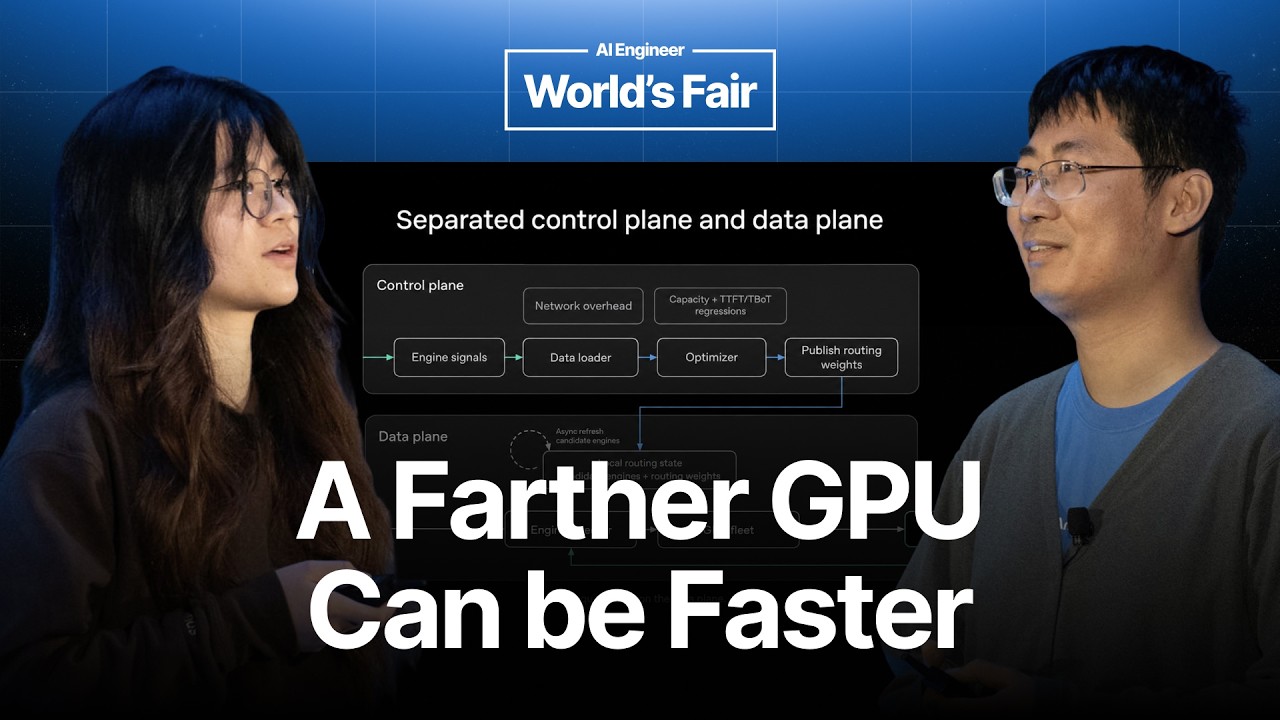
This talk outlines OpenAI's journey in building a robust inference load balancer. It details the transition from an initial feedback-loop-driven system, which suffered from explainability issues and disruptive oscillations, to a sophisticated control plane/data plane architecture. The new system leverages a global view to optimize end-to-end latency across all traffic, balancing network distance with engine-side queuing, and includes critical protection mechanisms like outlier penalties, dynamic retry budgets, and load shedding to ensure stability in production.