Kv cache

CoreWeave Fully Connected 2026 Keynote: Introducing CoreWeave Forge | Built for Adoption

CoreWeave Fully Connected 2026 Keynote: Introducing CoreWeave Forge | Built for Adoption

CoreWeave's Fully Connected 2026 Day 1 keynote centers on the AI loop of run, observe, curate, improve and evaluate, and the launch of CoreWeave Forge. It covers production agent operations, agent observability and RL rollouts, Vera Rubin NVL72 and the Vera CPU, and enterprise evaluation practices from Capital One, Caterpillar and Cognition.
How Cline Embraces an Open-Weights Model Ecosystem for AI Agents

How Cline Embraces an Open-Weights Model Ecosystem for AI Agents

Cline's CEO explains why open-weight models are rapidly taking over coding-agent workloads, and why the agent harness, not raw model capability, determines reliability. The talk covers model-specific tuning and failure handling, context and token optimization, self-improving harness loops, an SDK-first and UI-agnostic architecture, interactive evaluation built from real-world usage data, and production inference challenges such as KV cache hit rates.

Data Architecture for AI: From Training Pipelines to Agent Memory

Data Architecture for AI: From Training Pipelines to Agent Memory

Alan Kourev, co-founder and CTO of VAST Data, explains how AI workloads (training, inference with KV cache offload, RAG, and agents) access data in fundamentally different ways, and presents a disaggregated, shared-everything architecture, shaped in part by work with CoreWeave, that serves all of them from one unified platform.

AI Tokenomics Explained

AI Tokenomics Explained

A product and go-to-market lead at NVIDIA examines the economics of AI inference as agentic AI multiplies token demand. The talk covers matching premium versus efficient models to use cases, model routing, open models, sizing token demand, and extreme co-design across mixture-of-experts models, NVLink systems, KV caching, software stacks, and CPUs to maximize tokens per watt and minimize cost per token.

Is Speculative Decoding Worth It? Profiling vLLM on NVIDIA Blackwell — Akamai

Is Speculative Decoding Worth It? Profiling vLLM on NVIDIA Blackwell — Akamai

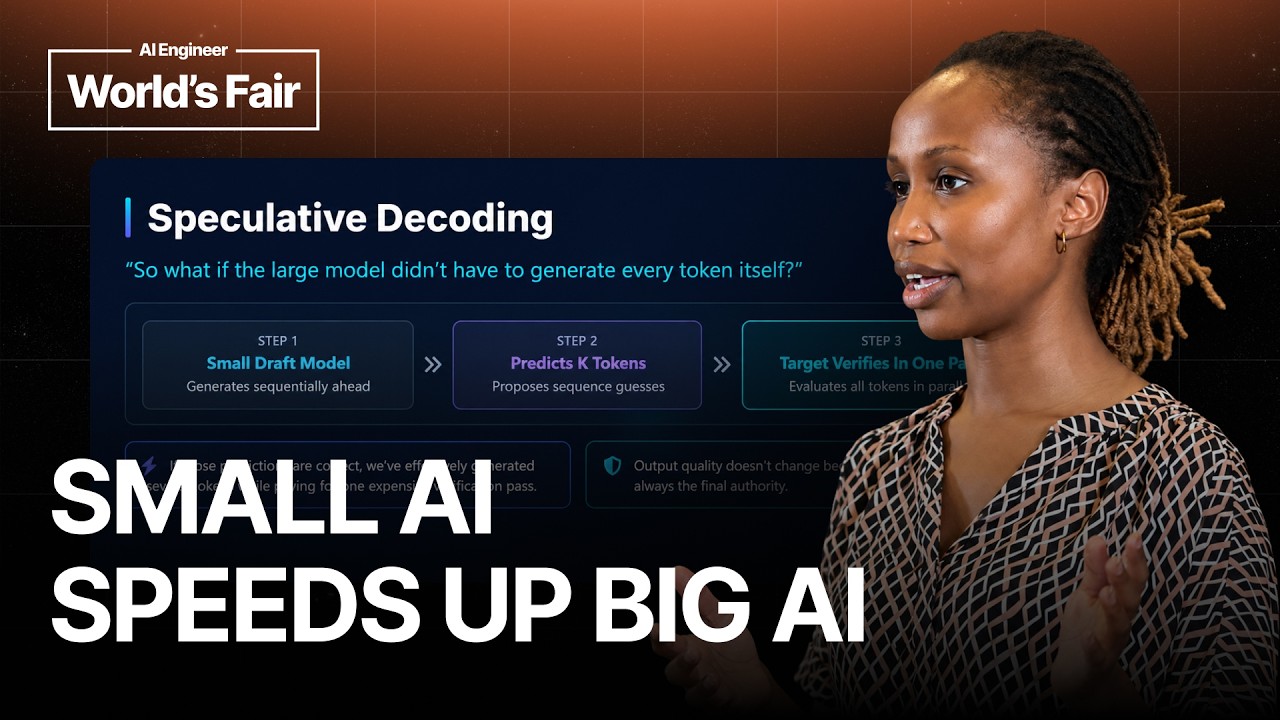
Sheilah Kirui explains speculative decoding for LLMs, detailing how a small draft model proposes tokens for a larger target model to verify in a single pass, accelerating the decoding phase. She covers the memory costs of hosting two models, criteria for choosing an effective draft model, and demonstrates its benefits for structured output (1.6x faster with high acceptance) versus its limited gains for creative tasks. The talk concludes by outlining when speculative decoding is most advantageous, considering VRAM availability, batch size, workload type, and context length.

The Frontier AI Inference Cloud for Agents — Byung-Gon (Gon) Chun, FriendliAI

The Frontier AI Inference Cloud for Agents — Byung-Gon (Gon) Chun, FriendliAI

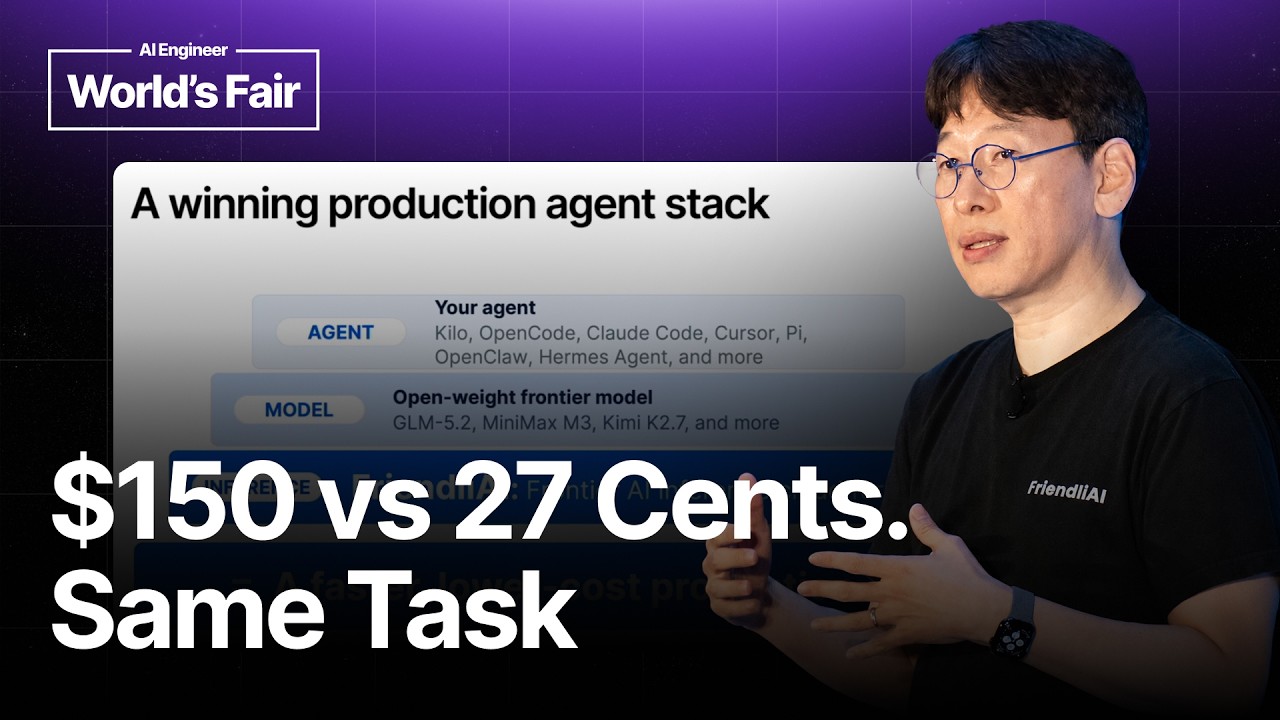
Byung-Gon Chun from FriendliAI details how agentic inference fundamentally differs from traditional chat-based LLM usage, requiring a specialized infrastructure to optimize for end-to-end task completion rather than single request latency. He highlights the economic advantage of open-weight models for agentic workflows and explains FriendliAI's innovative inference stack, featuring prefix caching, advanced KV cache management, cache-aware routing, and agent-aware optimization, which together deliver significant speedups and cost savings for production AI agents.