Is Speculative Decoding Worth It? Profiling vLLM on NVIDIA Blackwell — Akamai
Sheilah Kirui explains speculative decoding for LLMs, detailing how a small draft model proposes tokens for a larger target model to verify in a single pass, accelerating the decoding phase. She covers the memory costs of hosting two models, criteria for choosing an effective draft model, and demonstrates its benefits for structured output (1.6x faster with high acceptance) versus its limited gains for creative tasks. The talk concludes by outlining when speculative decoding is most advantageous, considering VRAM availability, batch size, workload type, and context length.
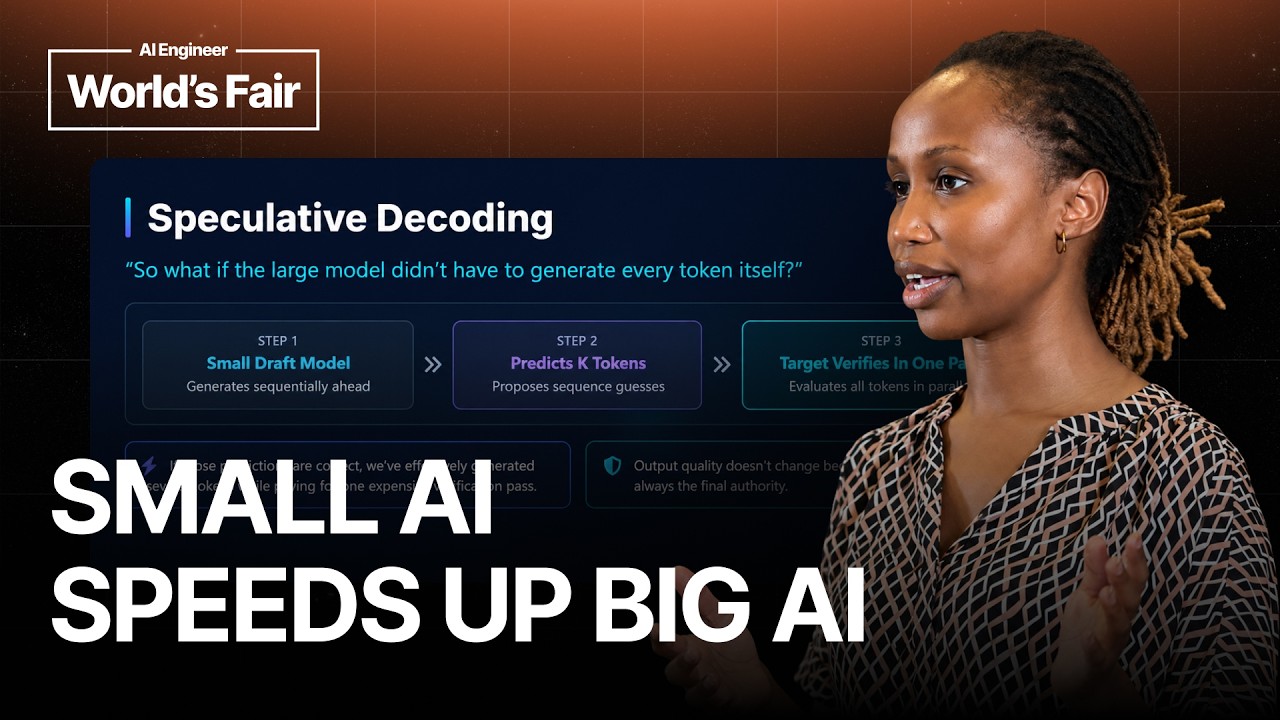
The speaker, Sheilah Kirui from Akamai, introduces speculative decoding as an optimization technique to accelerate Large Language Model (LLM) inference, specifically targeting the token generation phase.
LLM Inference Phases
She begins by outlining the two primary phases of LLM inference:
- Prefill: The model processes the input prompt, building a Key-Value (KV) cache which serves as its working memory. This occurs once per request.
- Decoding: The model generates output tokens one at a time, with each new token dependent on the preceding ones. This auto-regressive nature makes it a computationally expensive and time-consuming process, especially for large models, potentially requiring hundreds of forward passes.
The Core Idea Behind Speculative Decoding
Speculative decoding addresses the slow decoding phase by introducing a smaller, “draft” model alongside the primary, “target” model.
- The draft model quickly generates a few speculative tokens (typically 3-5 per cycle). Due to its smaller size, this generation is much faster.
- The target model then verifies these proposed tokens in a single forward pass. If tokens are accepted, they are appended to the output. If rejected, the target model recomputes the correct token from the point of rejection. The crucial advantage is that the expensive target model performs fewer forward passes for the same number of output tokens, as it validates multiple tokens simultaneously.
Costs and Considerations
While beneficial for latency, speculative decoding is not “free.”
- Memory Overhead: It requires hosting two models (the target and the draft) and maintaining separate KV caches for each, increasing VRAM consumption.
- GPU Utilization: It’s most beneficial when there’s spare GPU VRAM. In high-concurrency workloads where GPUs are already heavily utilized, implementing speculative decoding might not yield significant gains or even degrade performance due to resource contention. It is generally more effective for smaller batch sizes.
Choosing an Effective Draft Model
The selection of the draft model is critical for performance:
- Size: It should be significantly smaller than the target model, typically 10 to 50 times smaller, to ensure faster generation.
- Tokenizer: It must share the same tokenizer as the target model. Ideally, both models belong to the same family to avoid manual translation.
- Accuracy vs. Cost: A balance must be struck where the draft model is fast but also accurate enough to frequently predict correct tokens, leading to a high “acceptance rate.”
Empirical Demonstration with vLLM
Sheilah demonstrated speculative decoding using vLLM on a single NVIDIA Blackwell GPU, running both baseline and speculative setups concurrently.
Structured Output Tasks
- Example: Generating structured data like JSON, SQL, or code.
- Observation: Speculative decoding achieved a 1.6x speedup compared to the baseline.
- Key Metric: The acceptance rate (tokens accepted by the target model out of those generated by the draft model) was very high, indicating the draft model’s predictions were largely accurate for structured outputs. This also led to a higher tokens-per-second throughput.
Creative Writing Tasks
- Example: Generating poetry or brainstorming ideas with a high temperature setting.
- Observation: While still faster than baseline, the performance gains were significantly less pronounced.
- Key Metric: The acceptance rate was much lower. This is because creative tasks, especially with higher temperatures, introduce more variety and unpredictability in token generation, making it harder for the smaller draft model to accurately guess the next sequence of tokens.
When Speculative Decoding is Worth It
Based on these insights, speculative decoding is most advantageous under specific conditions:
- Spare VRAM: Sufficient GPU memory to host both models and their KV caches.
- Small Batch Sizes: Benefits are more pronounced with fewer concurrent requests.
- Structured Output: Workloads involving code generation, JSON parsing, or SQL queries where the next tokens are more predictable.
- Short Generation Lengths (relative to context): Its gains are primarily in the decoding phase. If the prompt (prefill phase) is very long, as in RAG applications or long-context tasks, the time spent on prefill will overshadow the decoding speedup, diminishing overall benefits.
Tools and Resources
Sheilah recommends vLLM for implementing speculative decoding due to its good documentation and ease of use for a simpler version of the technique. She also mentions more advanced architectures like n-gram, Medusa, and Eagle, and refers to blog posts (e.g., General Compute) and research papers by Google for deeper understanding. Further resources, including replication guides, are available on the Akamai Developers GitHub page.