Speculative decoding

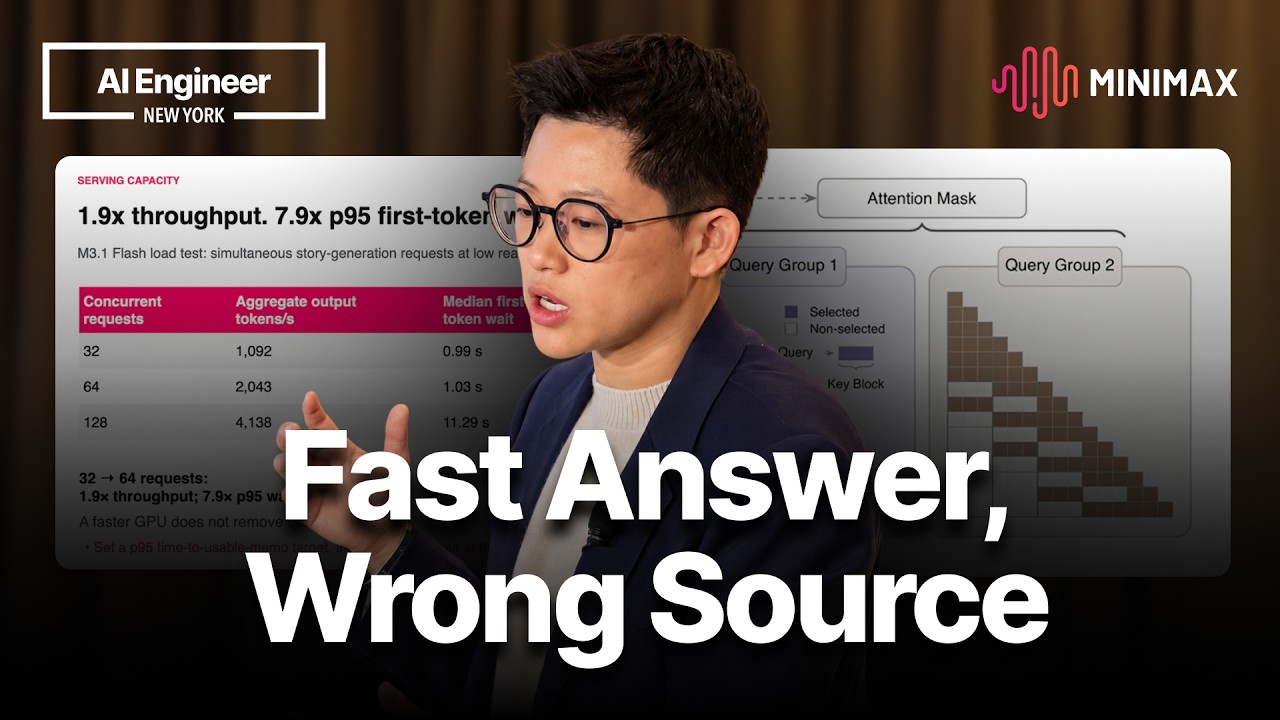
Is a Faster Model Actually Faster? Test the Whole Job — Morgan Suo, MiniMax

Is a Faster Model Actually Faster? Test the Whole Job — Morgan Suo, MiniMax

Morgan Suo of MiniMax tests the changes inside M3.1 Flash on a realistic analyst research task about circuit-board suppliers and AI-driven cash flow. She examines sparse attention, 4-bit KV caches, low-precision MoE experts, speculative decoding, serving concurrency, and reasoning budgets, showing how each saves compute while potentially costing accuracy or latency. She closes with a framework for judging a model switch by verifiable output, the full cost of a usable report, and repeatable results.
CoreWeave Fully Connected 2026 Keynote: Introducing CoreWeave Forge | Built for Adoption

CoreWeave Fully Connected 2026 Keynote: Introducing CoreWeave Forge | Built for Adoption

CoreWeave's Fully Connected 2026 Day 1 keynote centers on the AI loop of run, observe, curate, improve and evaluate, and the launch of CoreWeave Forge. It covers production agent operations, agent observability and RL rollouts, Vera Rubin NVL72 and the Vera CPU, and enterprise evaluation practices from Capital One, Caterpillar and Cognition.

Is Speculative Decoding Worth It? Profiling vLLM on NVIDIA Blackwell — Akamai

Is Speculative Decoding Worth It? Profiling vLLM on NVIDIA Blackwell — Akamai

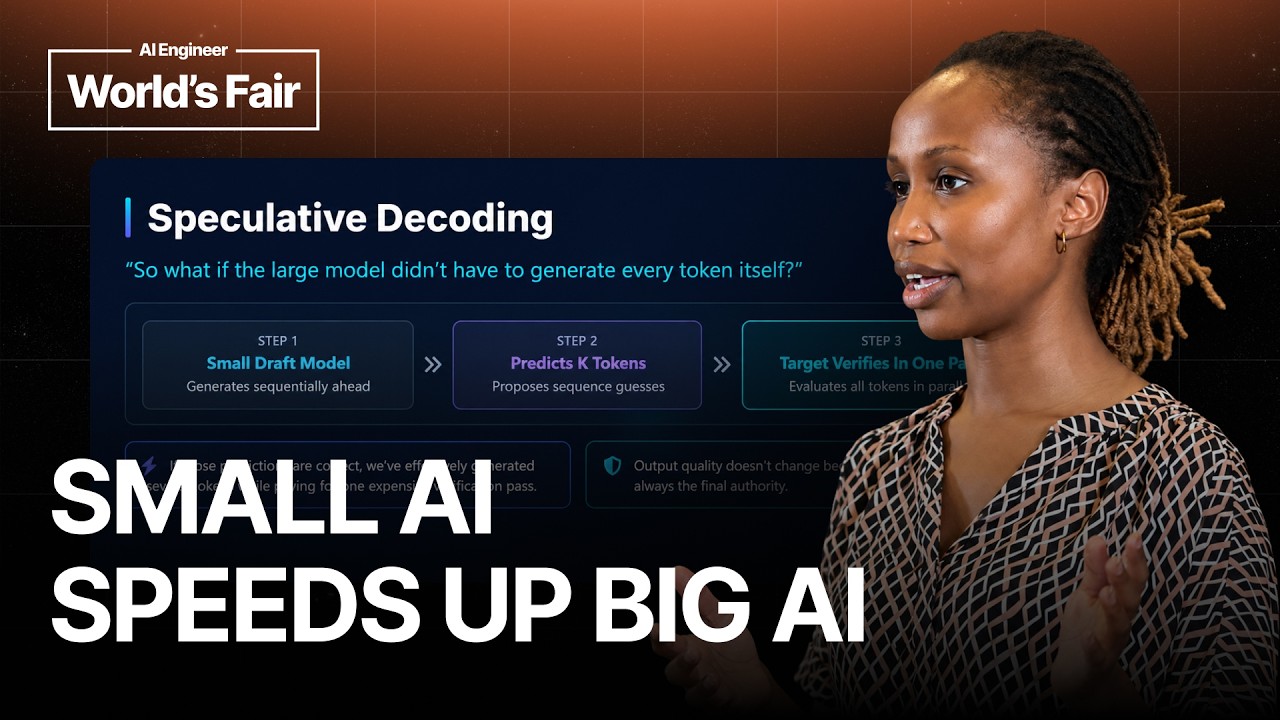
Sheilah Kirui explains speculative decoding for LLMs, detailing how a small draft model proposes tokens for a larger target model to verify in a single pass, accelerating the decoding phase. She covers the memory costs of hosting two models, criteria for choosing an effective draft model, and demonstrates its benefits for structured output (1.6x faster with high acceptance) versus its limited gains for creative tasks. The talk concludes by outlining when speculative decoding is most advantageous, considering VRAM availability, batch size, workload type, and context length.

What Is an Inference Engine, Anyway? — Charles Frye, Modal

What Is an Inference Engine, Anyway? — Charles Frye, Modal

Charles Frye explains the architecture, performance engineering, and operational challenges of LLM inference engines. He dissects workload types, core components like schedulers and kernel backends, and advanced techniques such as KV caching, CUDA graphs, and speculative decoding, concluding with essential strategies for observability and debugging in production environments.

What's New in Inference Engineering — Philip Kiely, Baseten

What's New in Inference Engineering — Philip Kiely, Baseten

Philip Kiely provides an update on recent advancements in inference engineering, covering new techniques in quantization (TurboQuant's specific application), KV cache compaction (introducing 'Still' for learned, compressed memory), and speculative decoding (from Eagle 3 to Dlash and DSpark, including continuous retraining). He emphasizes the blurring lines between training and inference and differentiates between local and data center optimization strategies.

The Next Breakthroughs in AI with Yossi Matias | The Google Research Podcast

The Next Breakthroughs in AI with Yossi Matias | The Google Research Podcast

Yossi Matias, VP and GM of Google Research, discusses how Google prototypes the future by inventing it, emphasizing the current "Golden Age of Research." Key themes include the seamless integration of AI through ambient intelligence and adaptive Generative UI, architectural advancements that push beyond scaling laws with techniques like Speculative Decoding, and multi-agent AI systems such as AI Co-Scientist and Empirical Research Assistance for accelerating scientific discovery. He also details Google Earth AI for crisis resilience and planetary intelligence, breakthroughs in healthcare diagnostics with MedGemma and the Google Health app, and milestones in quantum computing with the Willow chip, ultimately envisioning a future where AI amplifies human ingenuity and solves humanity's biggest challenges.