Is a Faster Model Actually Faster? Test the Whole Job — Morgan Suo, MiniMax
Morgan Suo of MiniMax tests the changes inside M3.1 Flash on a realistic analyst research task about circuit-board suppliers and AI-driven cash flow. She examines sparse attention, 4-bit KV caches, low-precision MoE experts, speculative decoding, serving concurrency, and reasoning budgets, showing how each saves compute while potentially costing accuracy or latency. She closes with a framework for judging a model switch by verifiable output, the full cost of a usable report, and repeatable results.
Why a faster model is not automatically a faster job
Morgan Suo, who works at MiniMax, opens with a problem most teams using AI in production will recognize. A new model arrives, the research report comes back quicker, and then someone has to find the source the model missed and fix the report by hand. Her argument is that speed only matters if the finished job gets faster. To test this, she uses one realistic task and walks through the internal changes in MiniMax’s latest language model, M3.1 Flash, which she says was about to be released.
The research task and what ‘finished’ means
The test job is an analyst question: as AI server demand grows, are the companies that supply printed circuit boards (PCBs) turning that growth into cash? The internal review covers 14 company reports. The model has to find the right reports, align the same reporting periods, keep different businesses separate, and explain what the numbers mean.
Suo describes the analyst who will receive the output. That person needs to open the source behind an important claim, recalculate a number, and see which piece of evidence could change the conclusion. In her framing, a finished research job is one the analyst can check. That standard drives the rest of the talk.
She uses profit versus cash flow as an example of why checking matters. Reported profit can rise while customers have not paid yet or while materials sit in inventory. A useful model should point the analyst to the cash flow statement and the relevant disclosures, not just headline earnings.
What changed inside M3.1 Flash
Suo organizes the model changes around four questions: where attention work can be reduced, where data can be stored and moved more cheaply, how the serving setup affects user wait time, and how much reasoning the model is allowed to do. Each change is paired with a check against the finished result.
Sparse attention on long inputs
MiniMax markets a context window of around one million tokens, but Suo’s point is that a large window is only useful if the model can locate the right passage quickly. Sparse attention first runs a small selection step that scores blocks of the input, then runs full attention only over the selected blocks, while keeping nearby tokens in view. The selection changes with each query, so different questions can attend to different parts of the same document.
The risk is obvious in her example. In a cash flow question, a very short footnote may matter more than several pages of industry outlook. To test retrieval, the team placed the same key passage at different positions across inputs and asked the same question each time. Across 39 requests, with the longest inputs around 830k tokens, the model passed in that test. Suo is careful to say this covers only the cases tested, and that the real check is whether it finds a cash flow footnote, uses the right reporting period, and spots conflicts between documents.
The 4-bit KV cache
The model stores its key-value memory from earlier text, the KV cache. In M3.1 Flash, keys and values drop from eight bits to four, while queries stay at eight. This reduces storage and data movement. The problem is that aggregate scores can conceal important failures. Suo notes that the average score barely moved, yet one category fell by about 6.6 points while others rose. The full-setup comparison also did not show which individual change caused each drop. Her conclusion is to re-check the output directly: are the sources right, are the calculations right, and does the explanation match the evidence.
Low-precision experts
M3.1 Flash uses a mixture-of-experts (MoE) architecture, and only some experts are activated per token. The selected experts run at four-bit weights and activations, while the shared expert is left unchanged. Lower precision reduces data movement and can speed up computation, but the arithmetic involves several steps: scaling numbers, running the calculation, and restoring the scale. Suo argues the order of these steps matters, and that a fast kernel still needs to be verified end to end. For the research job, the team reruns the same questions and examines why answers still miss the evidence checks.
Speculative decoding
Speculative decoding uses a faster draft process to propose a short run of tokens, which the target model then verifies. Accepted tokens are kept, a correction is made where needed, and the process continues. The gain is that several tokens can come from one target pass, but drafting, verifying, and rejecting all take time. Suo’s point is to count the full pipeline. For a research report, that also includes source retrieval, tool calls, and retries, because financial claims still need their own checks.
Throughput versus wait time
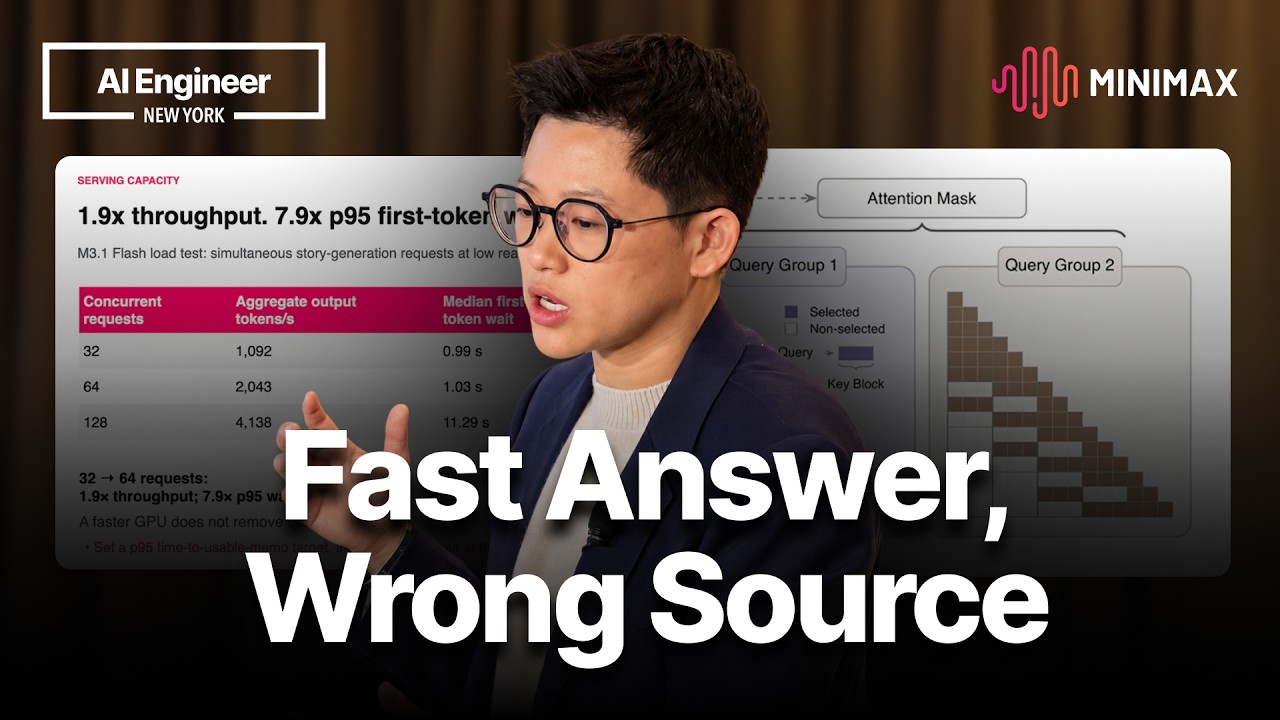
The serving test is the most practical part of the talk. Raising concurrency from 32 to 64 requests increased total output throughput by roughly 1.9 times, and throughput numbers above 300 tokens per second look impressive. However, the P95 wait for the first token rose from about 1.5 seconds to roughly 11 seconds, which is about eight times longer. The median looked fine, but the tail is what users feel. Suo argues that first-token latency can hide reasoning delay, so the metric that matters is when a usable report actually arrives. She recommends setting a deadline for that report and treating any configuration that misses it as a failure, regardless of throughput.
Reasoning budgets
The reasoning effort setting controls how many tokens the model spends thinking. The default is max, and leaving the effort field blank applies it. In a coding test, high reasoning produced fewer output tokens than max, but accuracy fell from 80% to 68%. Fewer tokens meant less accuracy on those tasks. Suo’s recommendation is to give each task the budget it truly needs. For the research workflow, the team should compare settings on the same reports, check whether each one finds evidence and supports calculations, and record the chosen setting so it can be reproduced later. A quick first-pass draft may legitimately need a smaller budget than a final review.
How to evaluate a model switch
Suo’s evaluation plan has three parts. First, fix the source reports, use the same information cutoff, and agree on what makes a report acceptable before running any comparison. Then check three things.
The first is trust. Can the analyst open the sources behind important claims, check reporting periods, recalculate financial numbers, and find evidence that could change the conclusion?
The second is cost. How long does a finished job take, and what does it cost once retrieval, tool calls, retries, and human repair are included? Suo insists that every failed attempt be counted in the cost of an acceptable report. The measure is the cost and time of a report people can actually use, arriving within the promised window.
The third is repeatability. Can the result be reproduced? That means saving model and runtime versions, prompt settings, and sources, keeping examples of failures, starting with a small rollout, and keeping a clear path to roll back.
Recap
Suo returns to her opening question. Should the team switch to a faster model? For this analyst, the answer depends on whether the model produces a report with sources they can open, numbers they can verify, and delivery on time. The architectural changes reduce computation, but the finished job reveals what those savings actually cost. Her closing point is that faster models matter, but the outcome that counts is what people can do with them.
The talk ends with a short promotion for MiniMax’s Hailuo video model, which was used to produce the recap, and an invitation to the AIE CODE summit in San Francisco.