Financial analysis

Why Frontier Models Fail as Buy-Side Analysts - Janie Gu, Google DeepMind & Suyeol Yun, LinqAlpha

Why Frontier Models Fail as Buy-Side Analysts - Janie Gu, Google DeepMind & Suyeol Yun, LinqAlpha

Janie Gu of Google DeepMind and Kaggle explains why most AI benchmarks are unreliable: they don't reflect real work, they are costly to keep current, and their scores are hard to verify. Drawing on a reproduction of 65 industry benchmarks, she details the failure modes and how Kaggle is building auditable, containerized evaluation infrastructure. Suyeol Yun of LinqAlpha then presents MandateBench, which tests whether models can carry out buy-side equity analyst work from a fund mandate to a full investment memo.
Is a Faster Model Actually Faster? Test the Whole Job — Morgan Suo, MiniMax

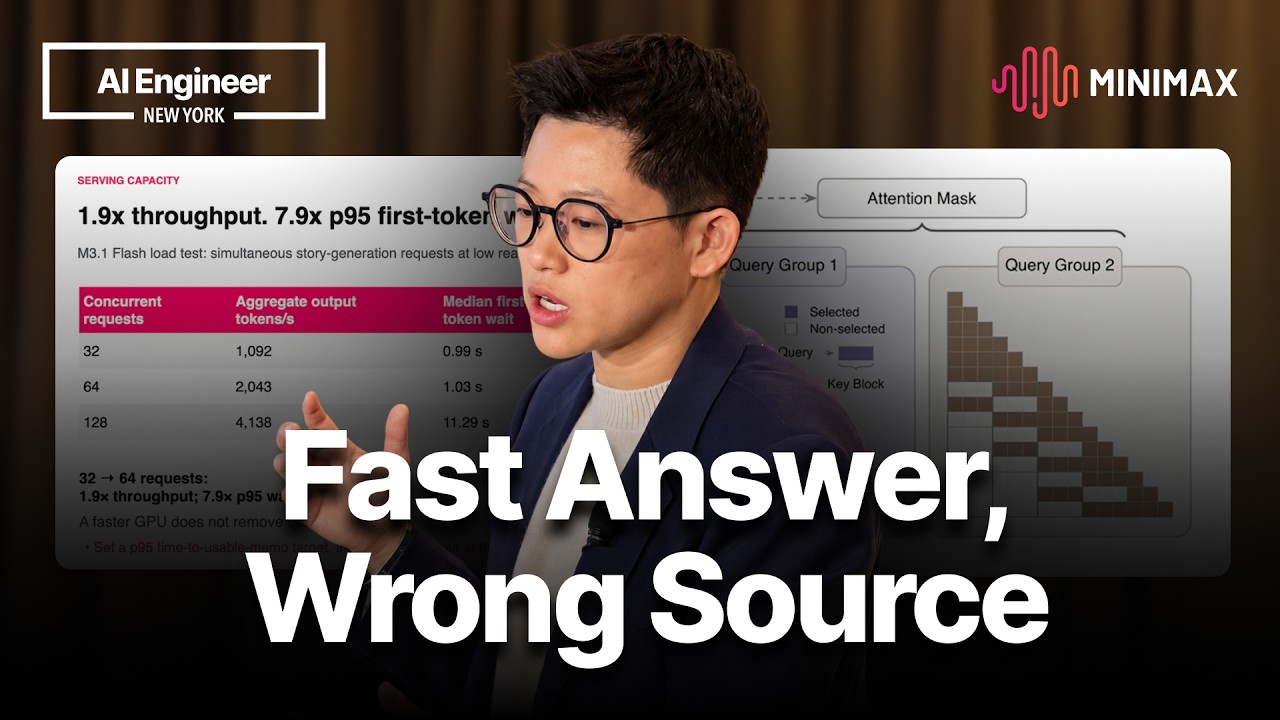
Is a Faster Model Actually Faster? Test the Whole Job — Morgan Suo, MiniMax

Morgan Suo of MiniMax tests the changes inside M3.1 Flash on a realistic analyst research task about circuit-board suppliers and AI-driven cash flow. She examines sparse attention, 4-bit KV caches, low-precision MoE experts, speculative decoding, serving concurrency, and reasoning budgets, showing how each saves compute while potentially costing accuracy or latency. She closes with a framework for judging a model switch by verifiable output, the full cost of a usable report, and repeatable results.

Stop Making Models Bigger, Make Them Behave — Kobie Crawdord, Snorkel

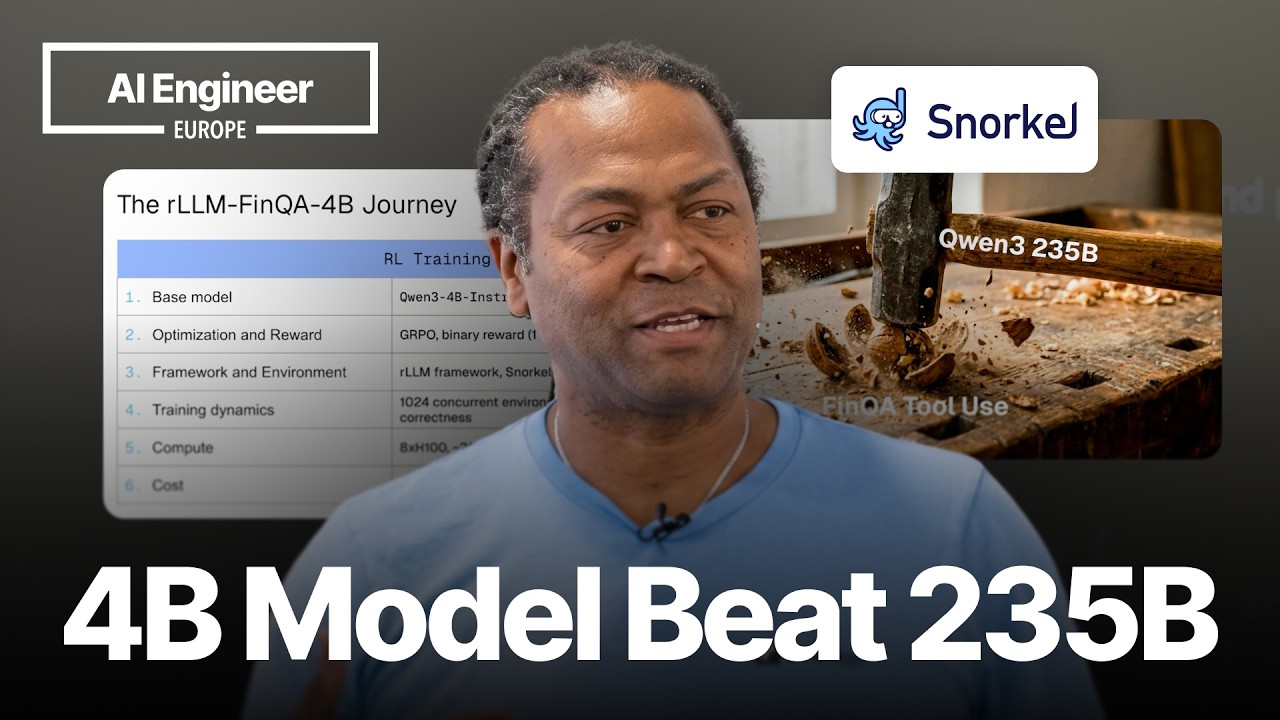
Stop Making Models Bigger, Make Them Behave — Kobie Crawdord, Snorkel

Snorkel.ai's research demonstrates how a 4-billion-parameter model, fine-tuned with Reinforcement Learning for under $500, significantly outperformed a 235-billion-parameter model on financial analysis tool-use tasks. The key was cultivating 'tool discipline' and error correction capabilities, rather than relying on sheer model size or deeper reasoning. Single-table training generalized effectively to harder multi-table problems, emphasizing the importance of targeted behavioral fixes identified through detailed evaluation rubrics.