Is Speculative Decoding Worth It? Profiling vLLM on NVIDIA Blackwell — Akamai
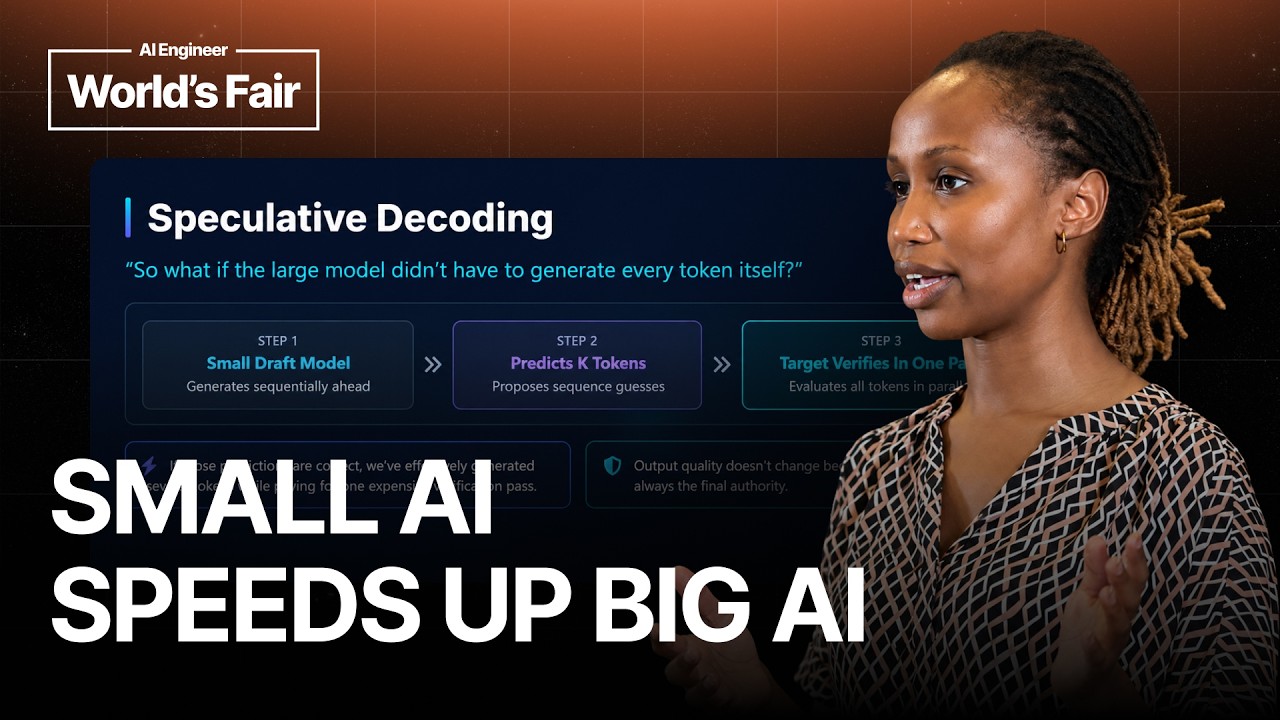
Sheilah Kirui explains speculative decoding for LLMs, detailing how a small draft model proposes tokens for a larger target model to verify in a single pass, accelerating the decoding phase. She covers the memory costs of hosting two models, criteria for choosing an effective draft model, and demonstrates its benefits for structured output (1.6x faster with high acceptance) versus its limited gains for creative tasks. The talk concludes by outlining when speculative decoding is most advantageous, considering VRAM availability, batch size, workload type, and context length.