Building Closed-Loop Evals for a Multimodal Agent at Scale — Soumya Gupta & Jai Chopra, Uber
This talk details how Uber Eats designed and implemented a multimodal AI agent to enhance food photography for independent merchants, addressing challenges like maintaining authenticity, merchant brand, and marketplace diversity while operating at scale. It covers the intricate evaluation strategies for routing and image editing agents, including continuous learning loops, managing drift, countering reward hacking, and balancing creative freedom with rigid safety guardrails. The speakers explain how they built a closed feedback loop combining offline human labeling, internal dogfooding, and online production signals to ensure robust and adaptive performance.
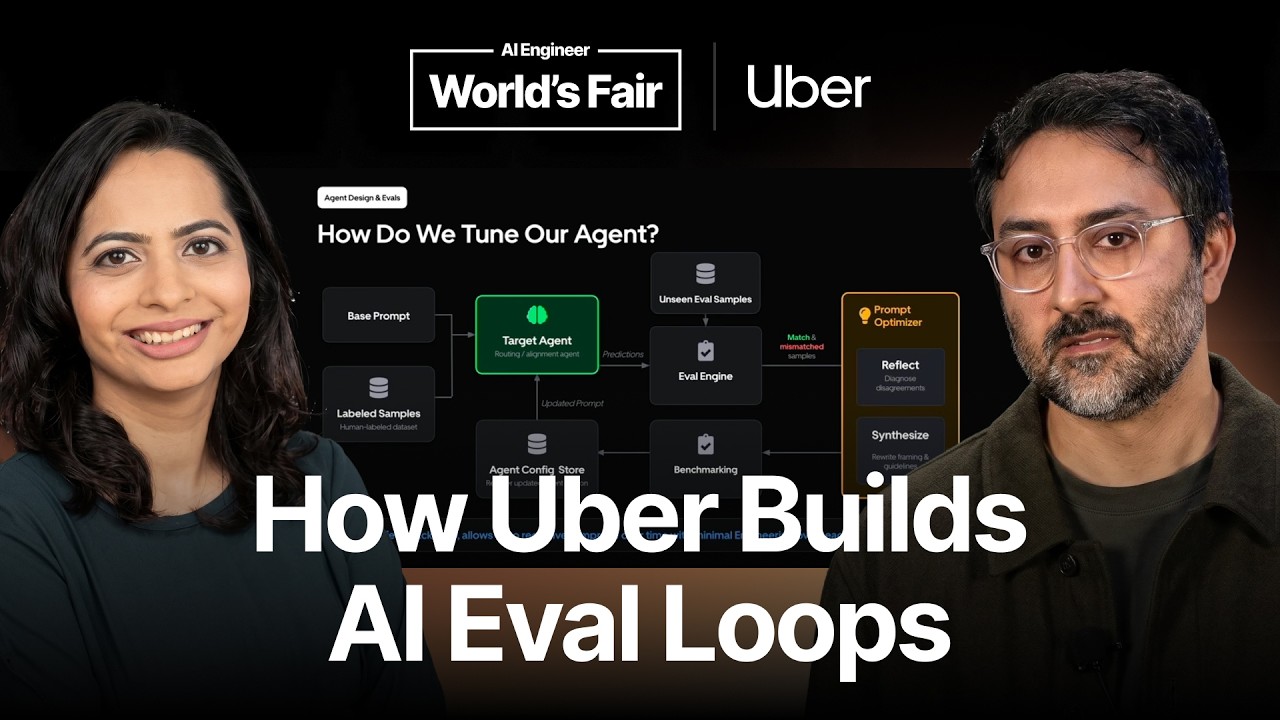
Uber Eats faces a significant challenge with the quality of food photography from smaller, independent merchants. These merchants often lack the time, know-how, and resources for professional photo shoots, leading to suboptimal visual content on the platform. Despite Uber Eats’ massive scale (90 billion run rate, millions of items added monthly, 10,000 cities), poor photos deter customers, as visual content is often the first impression.
The core problem is multifaceted: consumers want authentic, real-looking photos, yet a significant fraction distrusts AI-generated content. Therefore, any AI-driven enhancement must thread a needle: stay faithful to the original image, preserve the merchant’s brand, avoid homogenizing the marketplace (preventing an “AI look”), and manage a long-tail distribution of image quality globally (e.g., poor sharpness, composition, color, user-generated content).
To address this, Uber Eats developed an AI agent system with several key goals:
- Preserving authenticity and trust: Ensuring AI enhancements don’t look artificial.
- Selectively improving quality: Only enhancing where needed.
- Optimizing globally: Enhancing the entire marketplace without cannibalizing merchants.
- Shipping safely: Implementing robust guardrails and safety mechanisms.
- Continuous learning: Adapting to new data and feedback.
- Operating at scale: Cost-efficient and performant for millions of images.
Agentic systems are well-suited for this, offering a balance between deterministic, brittle rules-based systems and unconstrained creative AI. The approach involves carefully designed evaluations and continuous learning loops.
Agent Architecture and Evaluation Strategy
The system is a multi-stage pipeline, with each stage having its own evaluation process:
1. Image Understanding and Routing Agent
This is a multimodal agent where an LLM describes what it sees in a photo, generating structured output. A router then decides whether to enhance the image or skip it (keeping the original). This stage is critical for efficiency and relevance.
Evaluation:
- Traditional Classifier Metrics: Evaluated like a classifier using a confusion matrix to measure precision and recall. For simple binary routing, it’s a 2x2 matrix.
- Sophisticated Routing: For more complex scenarios (e.g., routing to different models based on latency/cost), an N-by-N confusion matrix can track correct routing to specific branches.
- Guardrail Metric: Recall is paramount for routing. The goal is to prevent any “bad image” from slipping through the system without enhancement, even at the cost of higher precision.
Failure Examples for Routing:
- False Positive (Routing a good image for enhancement): A high-quality cheeseburger image was routed for enhancement because the agent incorrectly flagged it as low quality. This incurs unnecessary compute cost and risks degrading an already good image.
- False Negative (Missing a bad image): An image of six chicken wings was approved despite the dish name indicating “eight pieces chicken wings.” Sending this for enhancement risks the model hallucinating extra wings, failing the crucial “faithfulness” metric.
2. Continuous Learning and Drift Management for Routing
Recognizing that a static model won’t suffice, the system incorporates continuous self-tuning to combat drift and align with human perception.
Initial Model Alignment:
- Golden Source of Truth: Human labels are considered the gold standard.
- Representative Dataset: A diverse dataset (geographies, dish types, quality) is collected and sent to human labelers with objective guidelines to minimize bias.
- Offline Tuning: The agent’s output is compared to this golden dataset, and the model is tuned until guardrail metrics (e.g., recall for routing) are met.
Online Drift Management (Auto-Tuning Pipeline):
- Production Sampling: Production data is regularly sampled and sent for human labeling using the same objective guidelines.
- Mismatch Detection: Agent output is compared with human labels to identify mismatches.
- Umbrella Diagnosis Agent: This agent takes feedback, localizes the issue within the system, and triggers an auto-tuning pipeline.
- Prompt Optimizer Agent: This is composed of two sub-agents:
- Reflect Agent: Analyzes mismatches, identifies systemic issues, and filters noise.
- Synthesize Agent: Uses feedback from the Reflect Agent to update the target agent’s configuration (e.g., prompts).
- Benchmarking and Deployment: The updated agent is benchmarked against the golden dataset. If it passes, the new agent version is registered and deployed. This is a closed-loop, config-driven system with built-in guardrail observability and quick rollback mechanisms.
3. Image Editing (Enhancement) Agent
This agent takes a routed image and iteratively enhances it.
Process:
- Prompt Generation: Based on image description and routing agent directives, a specific prompt is generated (e.g., “What needs improvement in this image?”).
- Enhancement: The image is enhanced based on the prompt.
- QA Gate: A multi-dimensional QA agent evaluates the enhanced image for aspects like plating, faithfulness, and colors.
- Iterative Loop: If the QA gate rejects the image, feedback is sent back, and the image is re-enhanced (up to K iterations). If it passes, it proceeds; otherwise, it’s not published (a coverage hit).
Evaluation:
- Pass at K: The primary metric, measuring the pass rate at the Kth iteration. This reflects the system’s ability to self-correct.
- Pairwise Comparison: For defining “better,” human evaluators compare the input and output images. This incorporates product, design, policy, and legal definitions of a good image:
- Faithfulness: Does it accurately represent the original dish?
- Completeness: Are all expected elements present?
- Naturalness: Does it look realistic and not artificial?
- Realism: Is the image plausible?
Failure Examples for Enhancement:
- Faithfulness Violation: Adding elements (e.g., shrimp to a dish where none were present) or removing elements (e.g., sauce from sushi).
- Reward Hacking: The agent attempting a creative edit in the first iteration, being rejected by QA, and then oversteering to an overly conservative, generic edit (e.g., using a plain ceramic bowl). This is a nugatory change with no meaningful quality improvement.
- Object Coherence/Physics Plausibility: Issues like a plate covering sauce, indicating fundamental problems with frontier models that can leak into applied use cases. Uber works with frontier model teams to address these.
- Multimodality Importance: Inability to confirm numerical counts (e.g., eight wontons) visually means the image is rejected, highlighting the need for combined visual and textual understanding.
4. Post-Processing and Publish-Ready QA
This is the final gate before an image goes live.
Functionality:
- Policy Checks: Ensures compliance with Uber Eats policies.
- Holistic Quality Checks: A broader assessment of image quality.
- Swiss Cheese Model: This final QA step acts as a redundant layer of protection, catching any failures that might have slipped past upstream gates. While seemingly redundant, it’s crucial for minimizing production failures.
Comprehensive Feedback Loops
The system is underpinned by multiple feedback loops to ensure continuous improvement and alignment:
- Model Loop: Accounts for drift and aligns with offline human-labeled data, as detailed above for routing and enhancement.
- Internal Dogfooding: Incorporates feedback from internal users (e.g., design teams, product teams, merchants) via thumbs-up/down, free-form comments in a pre-production environment. Flagged examples are replayed, benchmarked, and used to update configs.
- Production Metrics: Once live, the system tracks marketplace quality and health metrics, primarily conversion (e.g., add-to-cart rates, order completion). This data can be sliced by geography, device type, dish type, allowing for segment-specific tuning.
Diagnoser Abstraction: To manage these diverse feedback streams, a higher-level Diagnoser abstraction takes input from any feedback loop, reflects on which specific agent(s) need optimization, and routes the configuration fixes accordingly. This allows for a robust and adaptive agent ecosystem. The emphasis on logging everything from the start (It's basically a flat structure in this JSON) is critical for diagnosis and optimization.