Agentic systems

1,368 AI Failures and What They Teach About Evals — Vishal Srivastava & Tanmay Sah, New York Life

1,368 AI Failures and What They Teach About Evals — Vishal Srivastava & Tanmay Sah, New York Life

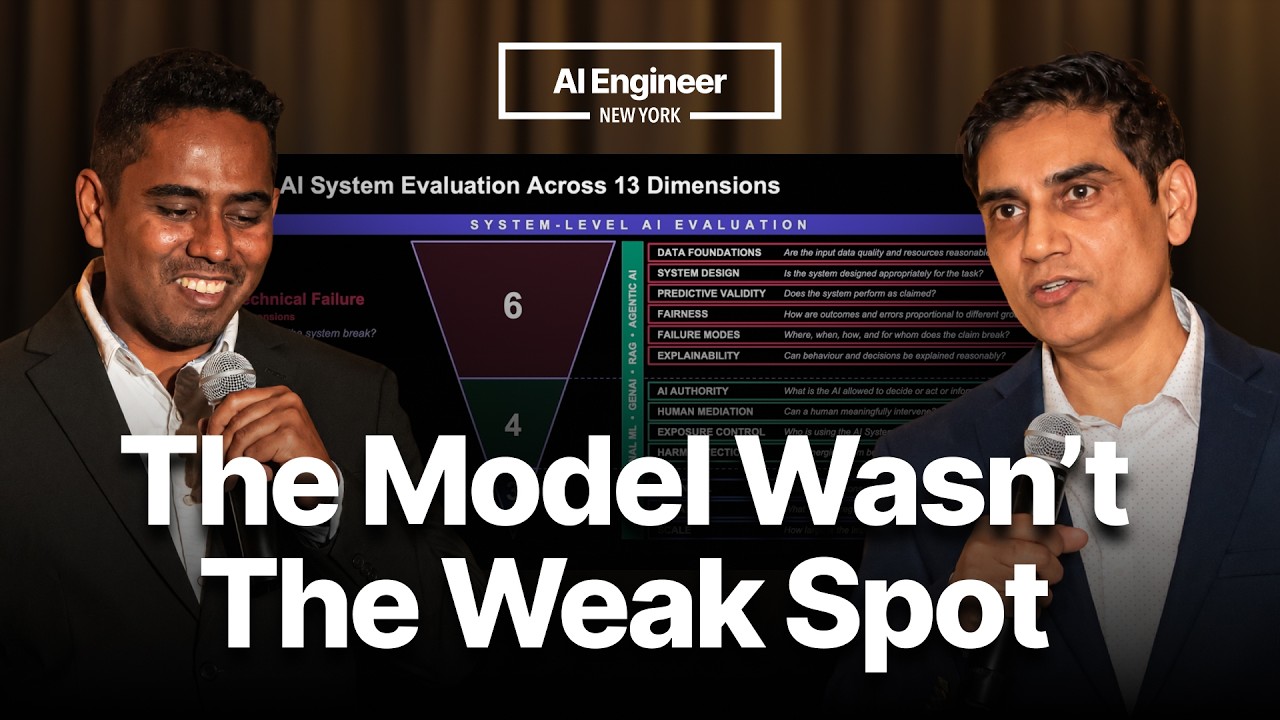
Vishal Srivastava and Tanmay Sah of New York Life analyze 1,368 public AI incidents to show what real failures reveal about how AI systems should be tested. They organize failures into three dimensions (technical strength, deployment controls, business impact) and 13 sub-dimensions covering about 98% of cases, find that weak deployment controls are most closely tied to harm, and present a materiality-based ranking of use cases, a failure-driven build-break-fix evaluation loop, and an airline chatbot refund case as an example.
AI Can Automate 60% of Tasks... But There's a Catch

AI Can Automate 60% of Tasks... But There's a Catch

MIT FutureTech director Neil Thompson revisits his group's 2020 computational limits paper and discusses his newer research on how AI automates tasks across the economy, covering the crashing-waves versus rising-tides survey, adoption bottlenecks, fixed-cost economics, apprenticeship risks, AI safety, and the open versus closed model debate.

Higgsfield - Building Agents That Provision Their Own Compute | DevDay 2026

Higgsfield - Building Agents That Provision Their Own Compute | DevDay 2026

Alex Mashrabov, CEO of Higgsfield, explains how agentic systems choose among models and provision their own GPU infrastructure to deliver consistent, multi-step creative media. He covers the trade-offs between speed, controllability, and dedicated deployment, and shares the 10-hour AI-generated live stream as an example of what becomes possible for small teams.

Databricks CEO: Stop Scaring People About AI

Databricks CEO: Stop Scaring People About AI

Databricks CEO Ali Ghodsi discusses the current state of AI, arguing against existential risk alarmism and advocating for a focus on immediate threats like AI-powered cyberattacks. He provides a rigorous definition for recursive self-improvement and explains how building an organizational 'ontology' can unlock massive productivity gains in enterprises. Ghodsi also covers the shift to multi-model AI strategies and cost management, highlighting how infrastructure is evolving to support agentic systems.

Inside the Race to Measure Frontier Intelligence

Inside the Race to Measure Frontier Intelligence

Independent model evaluation is crucial for AI progress, as public benchmarks are saturated and models optimize for them. Rayan Krishnan discusses VALS's role in providing continuously evolving, third-party evaluations, highlighting the Llama 4 'disaster' and the need to measure increasingly agentic systems. The conversation covers the complexities of evaluation beyond capability to include cost and latency, the looming financial impact of token spend on enterprises, and the critical role of evaluations in informing AI policy and international coordination for aligning AI with human intent and managing geopolitical risks, especially concerning recursive self-improvement.

500 Skills, Zero Fine-Tuning: LinkedIn's Playbook for AI Agents — Ajay Prakash, LinkedIn

500 Skills, Zero Fine-Tuning: LinkedIn's Playbook for AI Agents — Ajay Prakash, LinkedIn

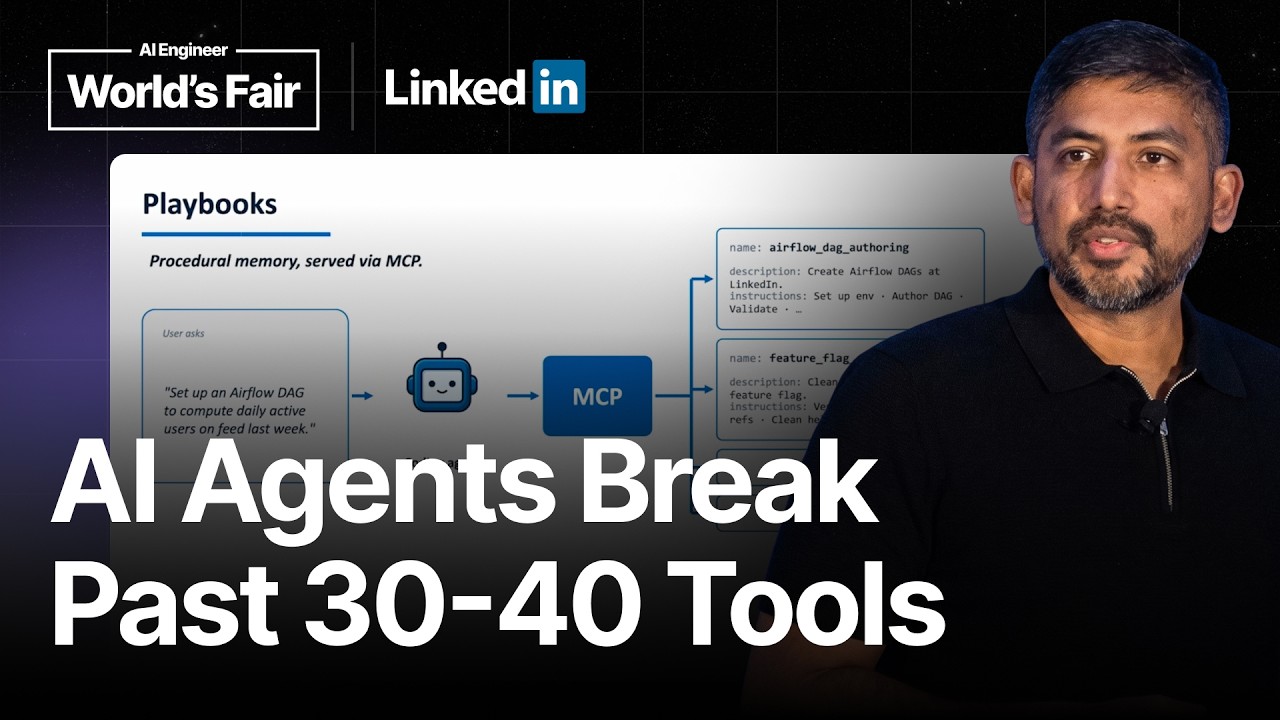
LinkedIn revolutionized its approach to AI agents by addressing the inherent limitations of LLMs in complex enterprise environments. Facing issues like hallucinations due to a lack of internal context, they developed a system of "playbooks" — structured, self-contained instructions published as tools. To scale beyond typical MCP limitations, they introduced three meta-tools (search, get schema, execute), enabling agents to dynamically discover and utilize thousands of internal tools and playbooks. This self-improving, context-aware infrastructure empowers agents to handle tasks from incident response to code generation, significantly boosting developer productivity and ensuring reliability.