We Cut 94% of AI Coding Tokens With a Local Code Index - Rajkumar Sakthivel, Tesco
Rajkumar Sakthivel details how an unexpected surge in AI coding tool costs led to the discovery that sending excessive, irrelevant context was the primary culprit. He introduces the Code Context Engine (CCE), a local retrieval layer that intelligently prunes context using AST-aware chunks, hybrid search, and relevance scoring, resulting in up to 94% token reduction and significant cost savings. The talk emphasizes that optimizing input context, not just the AI model, is paramount for efficient and accurate AI-assisted coding.
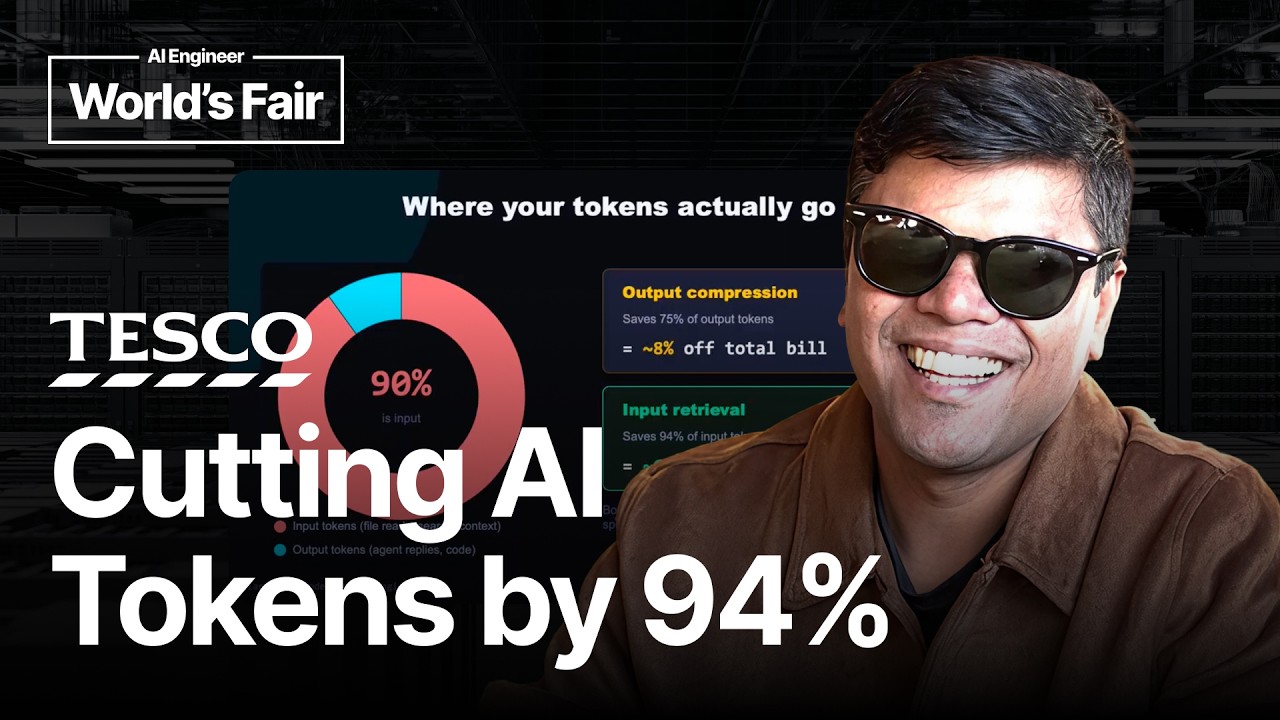
Rajkumar Sakthivel and his colleague Foss encountered a significant issue with AI coding tools: a sudden, massive increase in their AI bill. This wasn’t due to increased usage of different tools or projects, but rather the inherent inefficiency of how these tools handled context. They discovered that most AI coding tools operate under the assumption that sending more context is always better, leading to substantial waste.
The Problem: Excessive Context and Hidden Costs
Their typical query, for instance, involved sending 45,000 tokens to the model, despite only about 5,000 tokens being truly relevant. The remaining 40,000 tokens were irrelevant but still incurred costs, akin to paying for nine extra pizzas you don’t eat. This issue highlighted that approximately 90% of AI cost comes from the input (context), while only 10% comes from the output (generated code). Consequently, optimizing output (e.g., 75% compression) yields minimal savings (around 8% total), whereas significant input optimization (e.g., 94% reduction) can lead to massive savings (around 61% total).
Initial Misguided Attempts
Before finding a workable solution, they tried several approaches:
- Prompt Engineering: Attempting to shorten prompts or ask for only relevant code was ineffective because the 45,000 tokens were already sent before the model processed the prompt, meaning the cost was already incurred.
- Model Settings: Adjusting parameters like
max_tokenortemperatureonly affected the output, not the costly input. - Output Compression: While successfully reducing output by 75%, this only affected about 10% of the total cost, making the overall savings negligible.
These attempts underscored a critical realization: the optimization efforts were focused on the model or output, not the fundamental problem of inefficient context management.
The Solution: A Local Retrieval Layer (Code Context Engine - CCE)
To address this, Rajkumar and Foss developed a local retrieval layer, which they named the Code Context Engine (CCE). This layer sits between the codebase and the AI, intelligently fetching only the necessary code snippets instead of entire files. The CCE operates through a five-step process:
- Code Structuring: Code is broken down into semantic, AST-aware chunks (functions, classes, methods) rather than arbitrary pieces.
- Hybrid Search: Two concurrent searches are performed:
- Meaning-based search: Good for related ideas, but can miss exact names.
- Keyword matching: Excellent for exact terms, but struggles with related concepts. Combining these significantly improves recall and precision, fixing each other’s weaknesses.
- Context Compression: Search results are further compressed, sometimes reducing a 50-line function to a 5-line description (e.g., function name and description).
- Relationship Tracking: The system tracks connections between code elements, such as function call graphs, allowing it to retrieve an entire execution path if one piece of code is identified.
- Relevance Scoring: Each retrieved result is assigned a score, and low-scoring, irrelevant context is filtered out to prevent “bad context” from being sent.
Crucially, CCE runs entirely locally, ensuring no data leaves the machine, addressing privacy concerns.
The Hardest Problem: Validating Retrieval Results
The most challenging aspect wasn’t the retrieval itself, but determining if the retrieved results were actually relevant. They found that providing wrong but confidently presented information was worse than no answer.
- Failed Attempts: Asking the AI to judge its own results added 2-3 seconds per query, making it too slow. Simple score limits were also inadequate, often discarding perfect matches for short questions.
- Effective Solution: A simple heuristic formula proved most effective: 50% meaning score, 30% keyword score, and 20% recency of the code. This formula, combined with a dynamic limit adjusted based on the current result set, runs in just 0.4 milliseconds without needing extra AI calls, demonstrating that simple solutions often outperform complex models.
Benchmarks and Trade-offs
Real-world testing on an open-source FastAPI project (53 files, 20 developer questions) showed impressive results:
- Token Reduction: 83,000 tokens per query without CCE vs. 4,900 tokens with CCE, a 94% reduction. With additional compression, this dropped to 523 tokens per query.
- Accuracy: Maintained 90% accuracy in finding the right code.
- Real Savings: On a project with 247 queries, CCE saved 12.4 million tokens, equivalent to £186 not spent, with 84% of savings coming from the search layer.
They acknowledge limitations, such as real-world savings being slightly lower than the 94% best-case scenario (which assumes full file reads every time). Large, highly mixed codebases (e.g., 396 files where files do many things) also pose challenges, as the recall significantly drops. CCE prioritizes speed and simplicity, using a small, fast model for search (re-indexing in under a second) over a larger, potentially more accurate but slower model.
Beyond Retrieval: Shared Context and Memory
A key innovation of CCE is its ability to create a shared index that multiple AI tools (Cloud Code, Cursor, Copilot) can connect to. This means that instead of re-explaining the same codebase to different tools every time, the context is learned once and persistent. If one tool learns something about the project, that knowledge is retained for subsequent sessions or other tools, leading to further efficiencies.
Conclusion: Fix the Input
The overarching takeaway is that the most significant optimization in AI coding isn’t about choosing the “best” model (e.g., Opus vs. Sonnet), which might account for 30% of costs. Instead, it’s about intelligently managing the input context, which constitutes 70% of the cost. By fixing the input, the choice of model becomes less critical, leading to substantial cost savings and faster, more accurate outputs. CCE is available as a free, open-source tool for developers to try and measure their own savings.