Hybrid search

Do Not Let Models Invent Numbers - Vinoo Ganesh, Kepler

Do Not Let Models Invent Numbers - Vinoo Ganesh, Kepler

Vinoo Ganesh, CEO of Kepler, explains how the company builds a verifiable financial research platform. Models cite numbers but never write them. Deterministic code performs the math, a citation registry built from more than 30 million SEC documents anchors every figure, and a post-processing filter strips anything untraceable. The talk covers hybrid search and re-ranking on Turbopuffer, tenant isolation, and why plain RAG produced thousands of wrong numbers in evaluations.
Memory-Aware Agent Harnesses for Anti-Money Laundering — Nacho Martinez, Oracle

Memory-Aware Agent Harnesses for Anti-Money Laundering — Nacho Martinez, Oracle

Nacho Martinez argues that the model is fixed while the harness (agent loop, memory, context engineering, tools and skills, continual learning) is where engineers can make real gains. He walks through the agent stack and applies it to an autonomous AML agent that flags suspicious bank transactions, then demonstrates the workshop environment and answers questions on memory design, skill retrieval, caching, and hybrid search.

Grep or Embeddings? Agentic Search Over Company Documents — George He, LlamaIndex

Grep or Embeddings? Agentic Search Over Company Documents — George He, LlamaIndex

George He, head of engineering at LlamaIndex, explores when agents need pre-indexed vector search and when plain file traversal with grep is enough. He contrasts Claude Code's embedding-free approach on code with the harder reality of large, messy, multimodal, permissioned company documents, and proposes a harness of hybrid retrieval, metadata filtering, grep, and reading tools backed by LlamaParse and LiteParse. The talk closes with a live demo of an agent building a cash-flow table from 135 Alphabet filings, grounded in source files.

Context Engineering in 2026 — Louis-François Bouchard, Omar Solano & Samridhi Vaid, Towards AI

Context Engineering in 2026 — Louis-François Bouchard, Omar Solano & Samridhi Vaid, Towards AI

Experiments with an AI tutor reveal that not compacting context often outperforms summarization, leading to better recall, lower cost, and faster responses, primarily due to LLM API prompt caching. Compaction invalidates the cache, making it unexpectedly expensive. While cloud environments benefit from full history, local hardware limits necessitate compaction, highlighting the need to prioritize actual constraints over default compaction strategies.

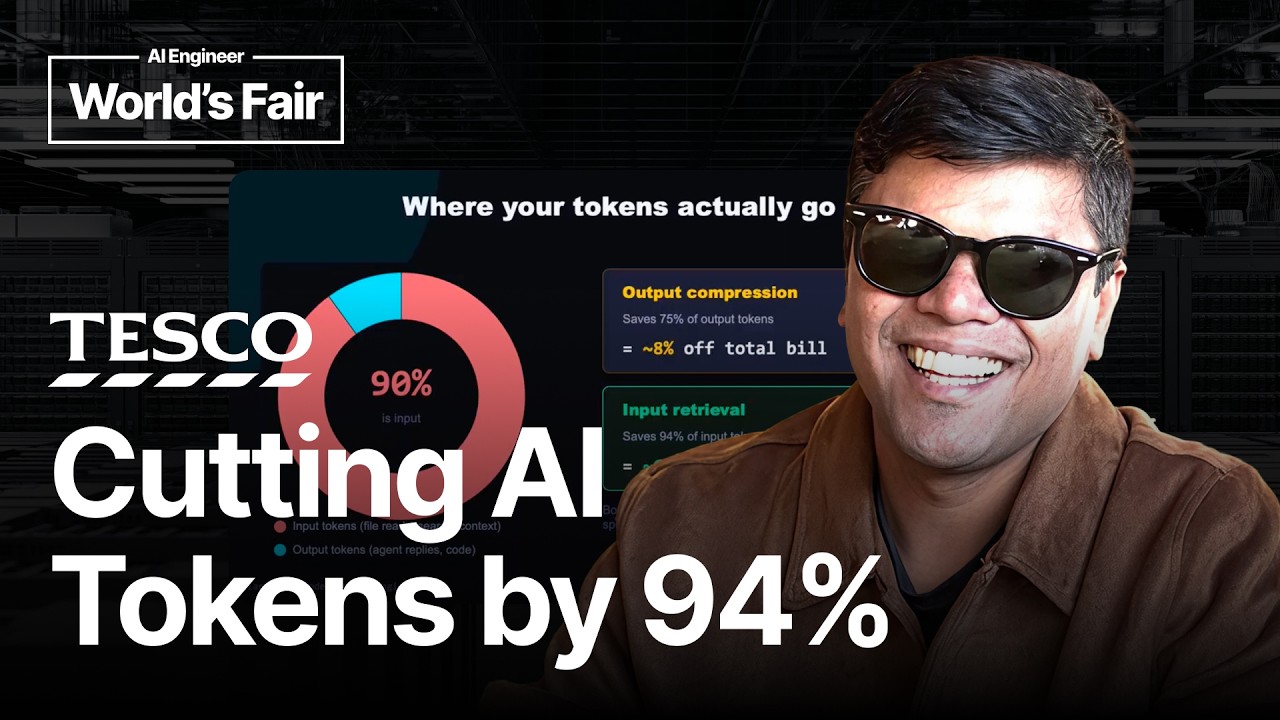
We Cut 94% of AI Coding Tokens With a Local Code Index - Rajkumar Sakthivel, Tesco

We Cut 94% of AI Coding Tokens With a Local Code Index - Rajkumar Sakthivel, Tesco

Rajkumar Sakthivel details how an unexpected surge in AI coding tool costs led to the discovery that sending excessive, irrelevant context was the primary culprit. He introduces the Code Context Engine (CCE), a local retrieval layer that intelligently prunes context using AST-aware chunks, hybrid search, and relevance scoring, resulting in up to 94% token reduction and significant cost savings. The talk emphasizes that optimizing input context, not just the AI model, is paramount for efficient and accurate AI-assisted coding.

Information Retrieval from the Ground Up - Philipp Krenn, Elastic

Information Retrieval from the Ground Up - Philipp Krenn, Elastic

Philipp Krenn from Elastic demystifies the 'R' in RAG, arguing that modern retrieval is a sophisticated blend of classic keyword search (like BM25) and modern vector search. This workshop explores the fundamentals of lexical analysis, scoring, dense/sparse vectors, and advanced hybrid search techniques like Reciprocal Rank Fusion (RRF).