Feature

When Should AI Systems Use Super Agents?

When Should AI Systems Use Super Agents?

Grant Miller explains the paradox of "super agents" in AI systems – their immense power comes with significant risks. He details concerns like privilege abuse and expanded attack surfaces, contrasting them with the benefits of unified organizational intelligence and workflow coordination. The solution proposed is an architecture of "agent swarms," guided by principles of least agency, isolation, observability, and human oversight, to build secure and scalable agentic systems.
Weight Folding, CUDA Streams, and the Bug That Made My Model Speak Backwards — Filip Makraduli

Weight Folding, CUDA Streams, and the Bug That Made My Model Speak Backwards — Filip Makraduli

This talk introduces FlashNorm, an optimization for transformer RMS norm layers. It details how algebraic tricks like weight folding, deferred division, and dropped pre-normalization can significantly speed up inference by mitigating GPU inefficiencies. The speaker also shares critical insights from implementing parallel CUDA streams, including debugging a subtle race condition caused by implicit stream joins, and advocates for open inference engines for deploying kernel-level research.

Large clusters for small models — Daniel Svonava, Superlinked

Large clusters for small models — Daniel Svonava, Superlinked

Daniel Svonava argues that small open-source models, when specialized and properly served, can achieve frontier performance for specific tasks, offering significant cost savings and latency improvements over large, generalized models or managed endpoints. He highlights challenges with existing serving infrastructure for a fleet of diverse small models and introduces Superlinked's open-source solution, which leverages a pull-based, centralized queuing system, a Rust sidecar for runtime abstraction, and an autoresearch loop for automated model tuning, enabling high throughput (e.g., half a million embedding tokens/sec on one GPU) and efficient deployment of specialized models and LoRAs.

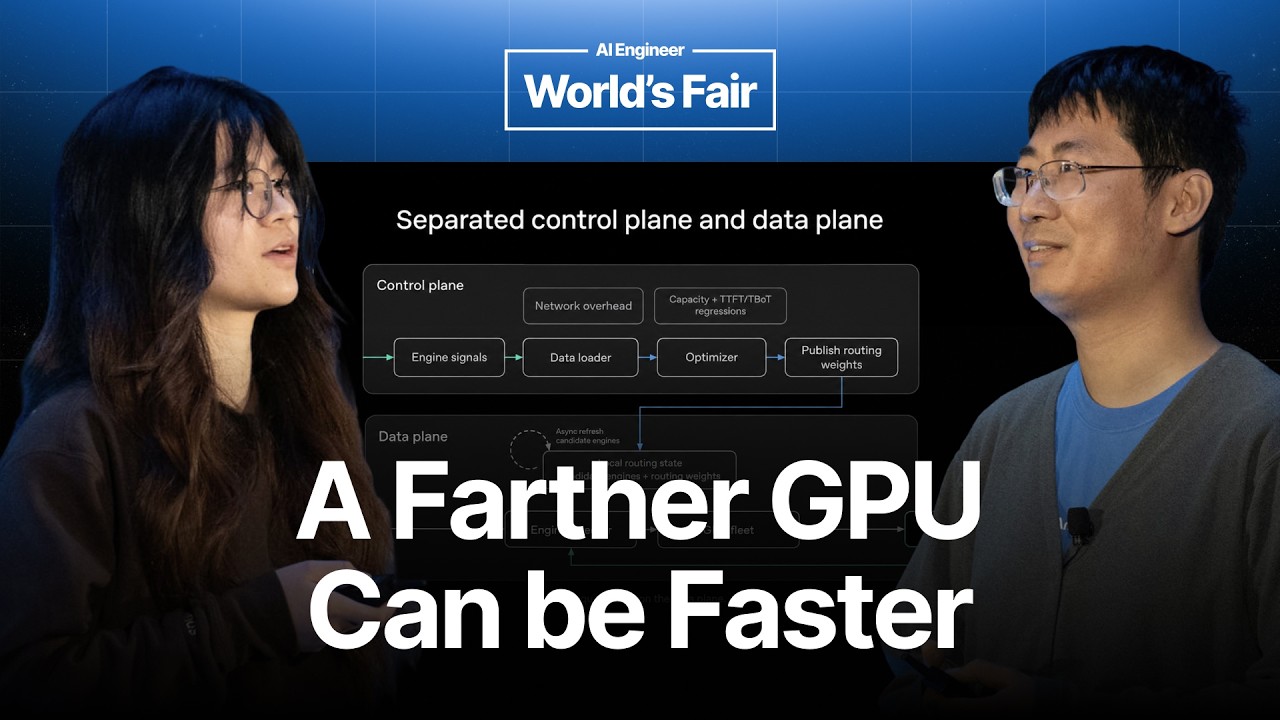
Routing LLM Inference in Production: From Engine Signals to Policy — Qianru Lao & Lu Zhang, OpenAI

Routing LLM Inference in Production: From Engine Signals to Policy — Qianru Lao & Lu Zhang, OpenAI

This talk outlines OpenAI's journey in building a robust inference load balancer. It details the transition from an initial feedback-loop-driven system, which suffered from explainability issues and disruptive oscillations, to a sophisticated control plane/data plane architecture. The new system leverages a global view to optimize end-to-end latency across all traffic, balancing network distance with engine-side queuing, and includes critical protection mechanisms like outlier penalties, dynamic retry budgets, and load shedding to ensure stability in production.

A Worm With 302 Neurons Inspired Their Architecture — Ramin Hasani, Liquid AI

A Worm With 302 Neurons Inspired Their Architecture — Ramin Hasani, Liquid AI

Liquid AI began by drawing inspiration from the C. elegans worm to develop Liquid Neural Networks, focusing on continuous-time, differentiable systems for efficient intelligence. Facing scaling challenges, they developed STAR, a meta-AI system for architectural search, optimizing hybrid models for quality, memory, latency, and speed, leading to their Liquid Foundation Models (LFMs). Their core focus is on bringing AI to the edge (on-device, in-car) for cost reduction, privacy, and offline capabilities, with successful deployments at Mercedes-Benz and Shopify. Liquid is also building a platform for 'sovereign AI,' enabling enterprises to customize and own their intelligence end-to-end, and researching massively multimodal systems, efficiency across the AI stack, and novel data types like DNA.

Total Recall: Agent Memory and Harness Engineering — Ignacio Martinez, Oracle

Total Recall: Agent Memory and Harness Engineering — Ignacio Martinez, Oracle

Ignacio Martinez's workshop delves into agent harness engineering, emphasizing that while LLMs are a 'frozen' reasoning core, the surrounding harness is where control and reliability are established. He outlines a seven-layer architecture for building robust agent harnesses, covering critical aspects like hybrid storage solutions, advanced memory engineering (including in-database embeddings and context card management), the semantic layer (Umwelt), agent loops, and context engineering. The session also explores continual learning through 'skill promotion' and addresses practical challenges like managing vast tool sets and optimizing model interactions.