Weight Folding, CUDA Streams, and the Bug That Made My Model Speak Backwards — Filip Makraduli
This talk introduces FlashNorm, an optimization for transformer RMS norm layers. It details how algebraic tricks like weight folding, deferred division, and dropped pre-normalization can significantly speed up inference by mitigating GPU inefficiencies. The speaker also shares critical insights from implementing parallel CUDA streams, including debugging a subtle race condition caused by implicit stream joins, and advocates for open inference engines for deploying kernel-level research.
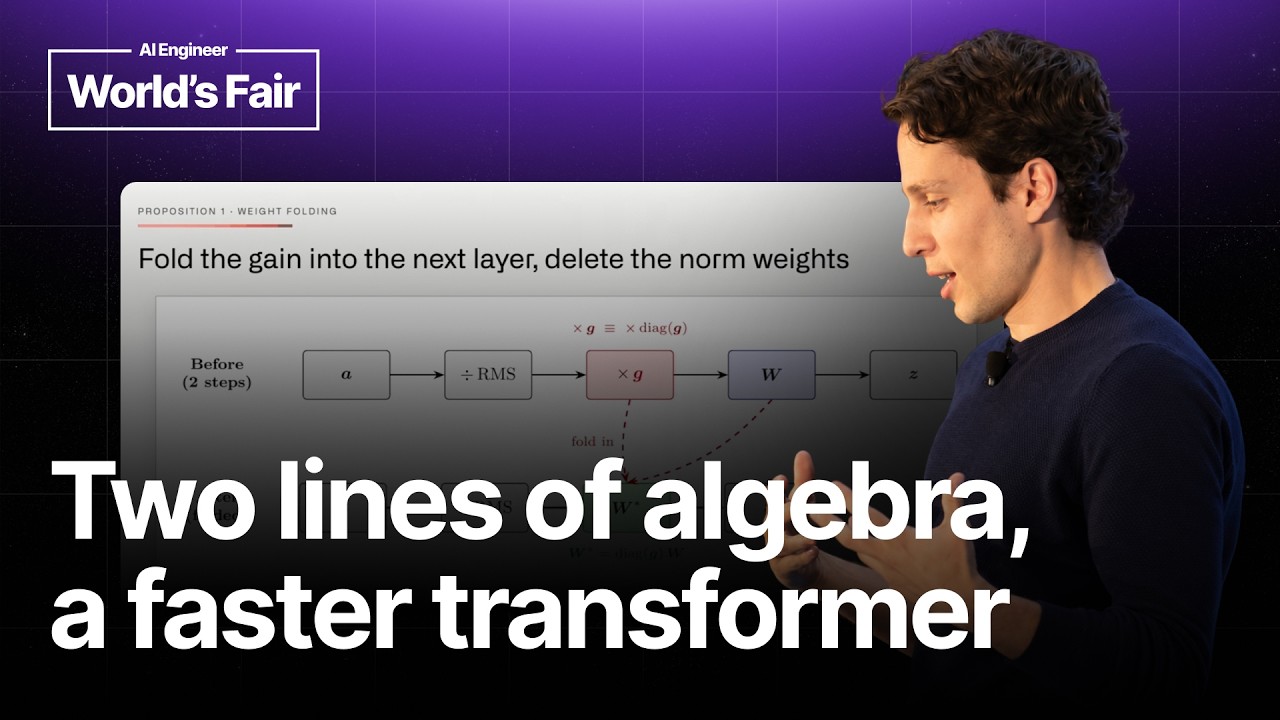
The presentation by Filip Makraduli introduces FlashNorm, a technique to significantly optimize the Root Mean Square (RMS) normalization layer in transformer architectures. While RMS norm performs minimal arithmetic, it contributes disproportionately to inference latency due to GPU inefficiencies related to work initiation, data movement, and waiting. In a single decode step, RMS norm can be invoked around 33 times, making its overhead substantial.
Makraduli outlines three algebraic tricks that form the core of FlashNorm:
- Weight Folding (“Weightless Normalization”): This involves folding the norm’s gain into the projection weights offline. The gain parameter, typically applied after the normalization, is absorbed into the subsequent linear layer’s weights (
W*). This pre-computation eliminates runtime overhead associated with this step, similar to how FlashAttention pre-computes certain elements to reduce memory communication. - Deferred Division: The scalar division within the RMS norm calculation is deferred to run in parallel with the subsequent matrix multiplication. Traditionally, these operations are sequential: normalize, then multiply. By running the matrix unit (for
matmul) and the vector unit (forRMS reduction) concurrently, FlashNorm eliminates idle waiting time. - Dropped Pre-Normalization: In newer architectures, like Gemma 4, RMS norm layers can appear twice consecutively. Since RMS normalization is a scale-invariant operation, applying it twice doesn’t add value and one instance can be algebraically removed without affecting the model’s output.
Implementing the deferred division technique in practice presented a significant challenge. While weight folding is relatively straightforward to apply, parallelizing the matrix multiplication and RMS reduction requires low-level CUDA programming. Makraduli describes his experience attempting to run matmul on Tensor Cores and RMS reduction on CUDA Cores in parallel. Initial unit tests and perplexity metrics looked promising. However, during long-generation tasks, the model began exhibiting “one-step lag” repetitions, effectively outputting stale data or “outputs from the past.”
This debugging effort revealed a race condition stemming from an implicit join between the parallel CUDA streams. One stream (e.g., the matmul) had not finished its work, causing the subsequent post-scale operation to read a stale buffer from an incomplete multiply. The fix involved explicitly marking the end of each stream and making the post-scale operation wait on both streams, ensuring data consistency before proceeding.
FlashNorm offers a 33-35% speedup on the norm-plus-projection operation. The techniques are compatible with existing ML tooling, including torch compile and quantized models, meaning they can be applied without significant rework of established workflows.
Makraduli concludes by emphasizing the importance of open inference engines, like Superlinked, for deploying and experimenting with such kernel-level modifications. He argues that performing “kernel surgery” and testing novel research ideas on rented endpoints (where users don’t own the inference stack) is often infeasible. Open-source inference platforms provide the portability and flexibility needed to deploy modified checkpoints, enabling researchers to validate and iterate on their innovations in a production-ready environment, even for smaller models or complex agentic tasks. This allows for fine-grained control over model configurations, efficient GPU resource utilization (e.g., running multiple smaller models on a single GPU), and full ownership of the cloud infrastructure for open-weight models.