Feature

Your LLM Judge Is a Confident Liar: Building Better Verifiers — Browserbase

Your LLM Judge Is a Confident Liar: Building Better Verifiers — Browserbase

Browserbase and Microsoft Research unveil their Universal Verifier for computer-use and web agents, addressing the critical flaw of inaccurate LLM-as-judge benchmarks that yield "confident liars." They detail its four guiding principles, demonstrating how it drastically cuts false positives and provides high agreement with human evaluations, leading to better training data. An auto-research experiment highlights the synergy between AI and human expertise in developing robust evaluation systems.
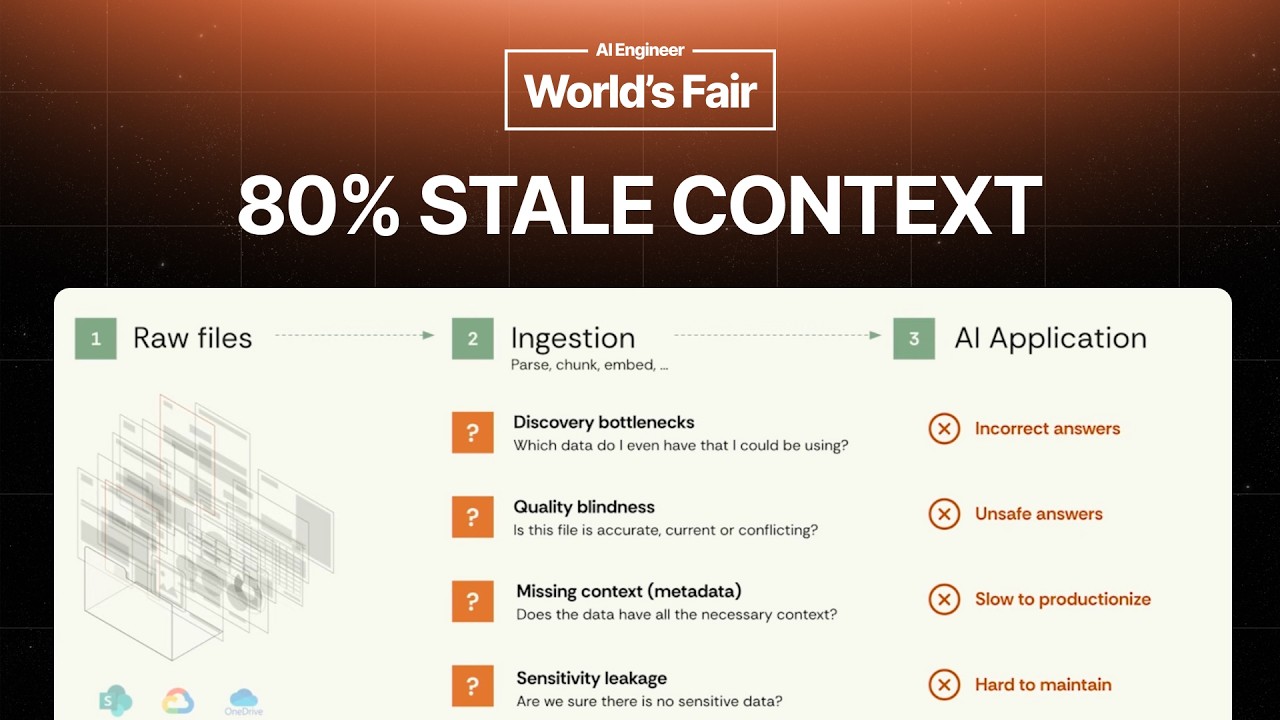
From Raw Documents to AI-Ready Data — Leo Platzer & Jeff Koss

From Raw Documents to AI-Ready Data — Leo Platzer & Jeff Koss

This presentation by Jeff Koss and Leo Platzer from Deasy Labs (now Collibra) tackles the critical challenge of scaling AI chatbots from pilot projects to production with large, messy unstructured datasets. They demonstrate a solution for curating and cleaning 80,000+ SharePoint documents, highlighting the importance of data quality—specifically identifying duplicates, conflicts, sensitive information, and ensuring data freshness—to significantly improve RAG chatbot performance and reduce development time.

The Transcript Looked Fine. The Call Wasn't. — Debugging Voice Agents, Arize

The Transcript Looked Fine. The Call Wasn't. — Debugging Voice Agents, Arize

Fuad Ali from Arize AI explains why voice agents are uniquely challenging to debug, as critical issues like latency, interruptions, and tone are invisible in text logs. He presents a solution combining unified audio, transcript, and trace views with OpenInference semantic conventions and audio-native evaluations. The talk culminates in a vision for self-healing voice agents through automated observation, evaluation, and improvement cycles, demonstrating how to achieve robust, continuously improving AI voice systems.

Agentic Search vs Vector Search for Coding Agents: We Ran the Eval — Braintrust

Agentic Search vs Vector Search for Coding Agents: We Ran the Eval — Braintrust

This talk by Jess Wang from Braintrust delves into the critical importance of evaluations (evals) in AI development, moving beyond subjective "vibes" to data-driven decision-making. She breaks down the four core components of an eval—dataset, task, scoring, and experiments—and illustrates the continuous improvement "eval flywheel" integrating observability. The central experiment compares agentic search against vector search for a coding agent tasked with finding buggy code in Microsoft's TypeScript Go repo. While both methods achieved identical accuracy, vector search proved four times more expensive due to its inability to capture surrounding context within code chunks, leading to excessive, inefficient searches. Wang concludes with practical caveats and best practices for conducting effective LLM evals.

How a Logistics Giant Keeps AI Data Locked Down

How a Logistics Giant Keeps AI Data Locked Down

Jason Ward, FinOps for AI lead at C.H. Robinson, shares insights on managing AI costs for enterprises and startups. He details a FinOps strategy centered on comprehensive tagging, leveraging AI for observability (e.g., detecting prompt bloat and context starvation), and pioneering advanced metrics like "cost per thought" and "reasoning ratio" to optimize complex AI workloads beyond simple discrete tasks.

Your Coding Agent Is 6 Months Out of Date — Jakub Hojsan, Exa

Your Coding Agent Is 6 Months Out of Date — Jakub Hojsan, Exa

Jakub Hojsan, a forward deployed engineer at Exa, explains how search built for coding and code-review agents closes the gap left by model knowledge cutoffs. He covers why agents need explicit rules for when to search, how query-dependent highlights cut a 100,000-character page to about 500 characters without added latency, and how Exa compares with native web search on transparency, cost, and model-provider independence, with a preview of Exa Agent.