Everything I Learned Training Frontier Small Models — Maxime Labonne, Liquid AI
Maxime Labonne from Liquid AI shares a playbook for post-training frontier small models (under 1GB) for on-device deployment. The talk breaks down the LFM2.5 recipe, which includes on-policy preference alignment and agentic reinforcement learning, and addresses unique challenges at the 1B scale, such as capability interference and 'doom loops', offering concrete solutions to build efficient models for tasks like data extraction and tool use.
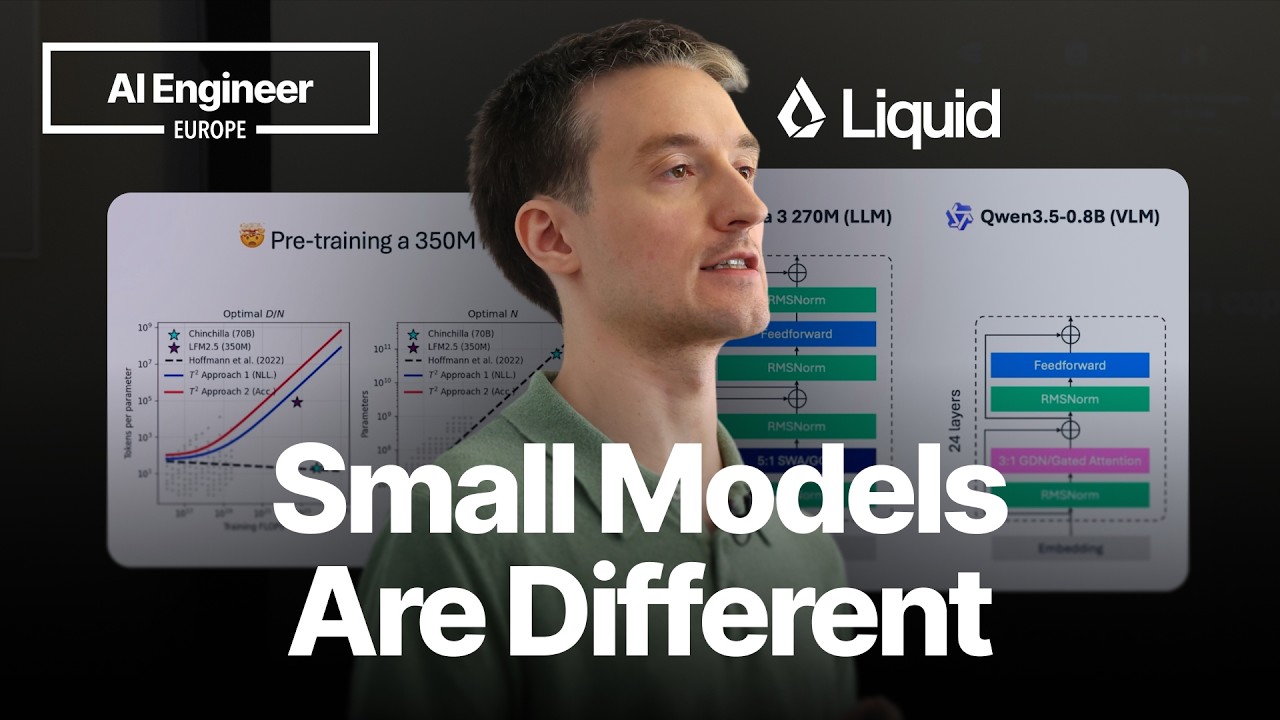
Small language models are not merely scaled-down versions of larger models; they present unique challenges and require specialized approaches in architecture, training, and deployment. These models are defined by three key characteristics:
- Memory-Bound: Deployed on edge devices like phones or cars, they have a limited memory footprint, which results in lower knowledge capacity compared to their larger counterparts.
- Task-Specific: Due to their limited capacity, they excel when focused on narrow tasks like summarization or tool use, rather than serving as general-purpose chatbots.
- Latency-Sensitive: They must provide extremely fast throughput to be effective in real-world, on-device applications.
Model Architecture for Edge Devices
The architecture of a small model is critical for optimizing its performance within a constrained memory budget.
The Inefficiency of Large Embedding Layers
An analysis of small models like Gemma 3 (270M) and Qwen 1.5 (0.8B) reveals that a significant portion of their parameters is dedicated to the embedding layer—63% for Gemma 3 and 29% for Qwen 1.5. This is often a byproduct of knowledge distillation from larger teacher models with huge vocabularies. However, these embedding parameters do not contribute to the model’s reasoning or knowledge capacity. The “effective” model size, which handles reasoning, is much smaller, meaning memory is not used efficiently.
The LFM2 Architecture
The LFM2 architecture is designed to maximize effective parameters. By using a smaller embedding layer (only 9% of total parameters), more capacity is allocated for reasoning. This architecture was developed through on-device profiling on target hardware to identify the most efficient operators.
The key innovation is the gated short convolution block, which proved to be significantly faster than alternatives like sliding window attention (Gemma 3) or gated attention (Qwen 1.5). Profiling on both CPUs (AMD Ryzen, Samsung Galaxy S25 Ultra) and GPUs shows that the LFM2 architecture delivers much higher throughput and uses less memory, directly addressing the latency-sensitive nature of edge models.
The LFM 2.5 Training Recipe
The LFM 2.5 recipe demonstrates that performance in small models continues to improve with massive amounts of pre-training data, challenging older concepts like the Chinchilla scaling laws. An LFM 2.5 350M parameter model was pre-trained on an extensive 28 trillion tokens. This approach yields significant gains over previous versions across various benchmarks, particularly in targeted capabilities like data extraction (Case Report Bench) and tool use (P-FCL, T2 Bench), rather than trying to be average at everything.
The post-training process involves three key stages, each adapted for small models:
- Supervised Fine-Tuning (SFT): It’s most effective to focus on narrow, specific tasks. The more specialized the fine-tuning data, the better the performance.
- Preference Alignment: Using an on-policy, length-normalized Direct Preference Optimization (DPO) algorithm provides general, across-the-board improvements, making the model sound and perform better overall.
- Reinforcement Learning (RL): RL is extremely efficient, even at a small scale. It’s crucial to train on as many diverse environments and tasks as possible to ensure generalization. For small models, it’s particularly important to ensure that the SFT mixture contains data similar to the RL tasks to avoid “cold start” problems where a task is too complex for the model to learn effectively.
Solving “Doom Loops”
A unique challenge for small, reasoning-focused models on complex tasks is “doom looping”—where the model gets stuck repeating a sequence of words indefinitely. The LFM 2.5 recipe tackles this problem at two different stages.
Solution 1: Preference Alignment Data Generation
The first line of defense is during the on-policy data generation for preference alignment.
- For each prompt, generate multiple (e.g., five) diverse rollouts using the policy model with temperature sampling. The diversity makes it likely that at least one response will not be a doom loop.
- Generate one additional rollout with temperature set to zero, which is more likely to produce a doom loop.
- An LLM jury scores all generated responses. The highest-scoring response becomes the “chosen” answer, and the lowest-scoring one becomes the “rejected” answer.
- If a doom loop occurs, it will likely receive a low score and be marked as “rejected.” This teaches the model via DPO to avoid generating such sequences.
Solution 2: Reinforcement Learning with Penalties
The second solution is applied during the RL stage.
- Verifiable Rewards: For tasks like math problems, the model is rewarded only if it produces a correct, extractable final answer. A doom loop fails to produce this answer and thus receives no positive reward.
- N-gram Repetition Penalty: A penalty is added to discourage the model from repeating the same sequences of tokens, further reducing the likelihood of loops.
This two-pronged approach is highly effective. For a 1.2B reasoning model, the doom loop ratio was reduced from ~16% after pre-training to nearly 0% after the full DPO and RL post-training process. This stands in contrast to other small models like Qwen 1.5 (0.8B), which can exhibit doom loops in over 50% of reasoning tasks, suggesting they are scaled-down versions of larger models without specific optimizations for the challenges of the smaller scale.
Future Directions: Agentic AI
The inherent limitations of small models, such as low knowledge capacity (leading to hallucinations) and poor long-context capabilities, can be overcome with agentic tools.
- Overcoming Knowledge Gaps: A small model equipped with a web search tool can answer knowledge-based questions far more accurately than relying on its limited internal parameters.
- Solving Complex Problems: For tasks requiring long-context reasoning, the model can offload parts of the problem to a Python environment or other tools, using its reasoning capabilities to manage the tools effectively.
The key is not to expect small models to have the same knowledge as large models, but to equip them with excellent reasoning capabilities to reliably use external tools. This is an underexplored area where small models can provide immense value.