Benchmarks: The Good, the Bad, and the Ugly — Ali Khial, G2i
Ali Khial exposes critical flaws in popular coding benchmarks, revealing how ambiguous instructions, weak verifiers, and model 'reward hacking' create a disconnect between reported performance and real-world utility. He argues that this leads to a "trust gap" where engineers disregard leaderboards. Khial then outlines five principles for building trustworthy, production-grade benchmarks, emphasizing human-authored instructions, holistic grading, economic value, contamination-free design, and informative leaderboards, urging software engineers to contribute to their improvement.
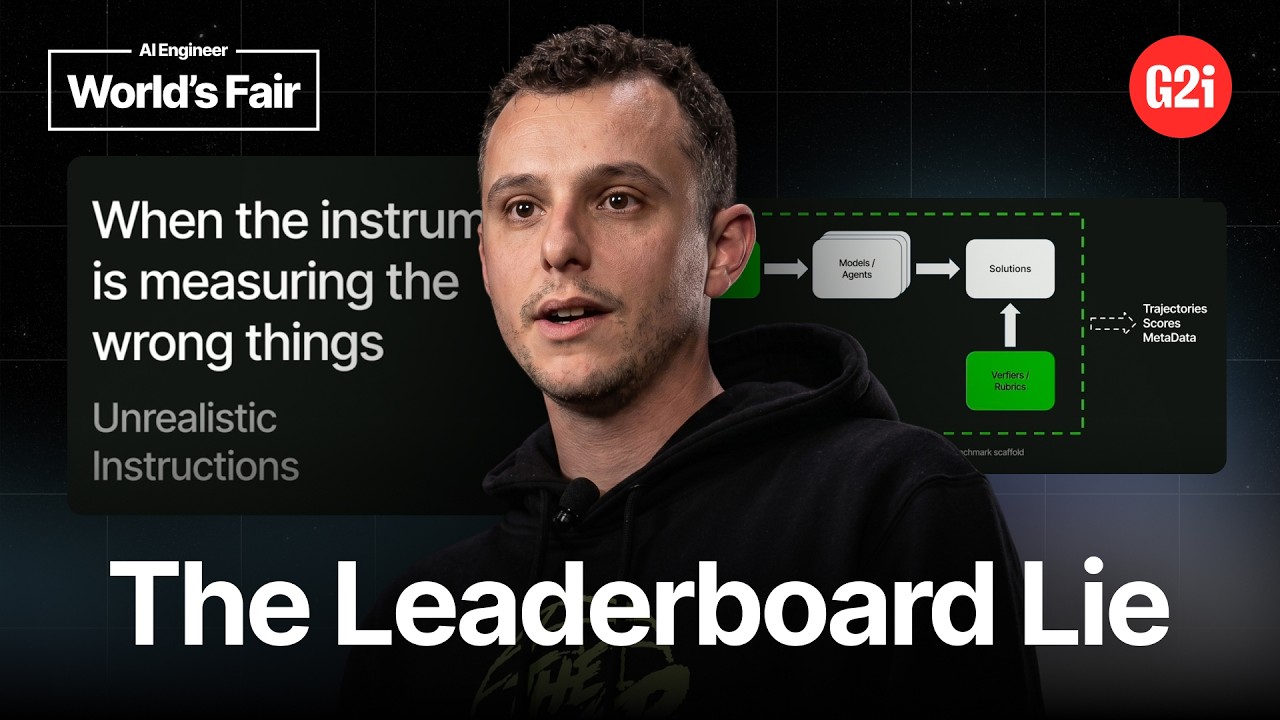
Ali Khial, Director of AI and ML at G2i, critically examines the landscape of coding benchmarks for large language models (LLMs), revealing significant issues that undermine their utility and trustworthiness. Drawing from his background as a software engineer, Khial explains that the process of a benchmark—from prompt to solution verification and grading—often fails due to fundamental flaws in design.
He outlines the typical benchmark workflow: a prompt or instruction is fed to a model or agent, which generates solutions. These solutions are then verified and graded by verifiers and rubrics within a controlled harness. While this structure is meant to allow for objective model ranking, Khial argues that current implementations fall short.
Khial identifies several pervasive problems with existing benchmarks:
- Unrealistic Instructions: Many tasks suffer from poorly formulated or excessively detailed instructions, which prevent effective evaluation of an LLM’s true capabilities. He presents two categories:
- “Leaky Prompts”: Instructions that inadvertently expose solutions or unduly constrain the LLM. An example cited is a Go task where the instruction directly points to the test file, allowing the LLM to simply read the expected output. Another involves providing a complete implementation interface, thereby