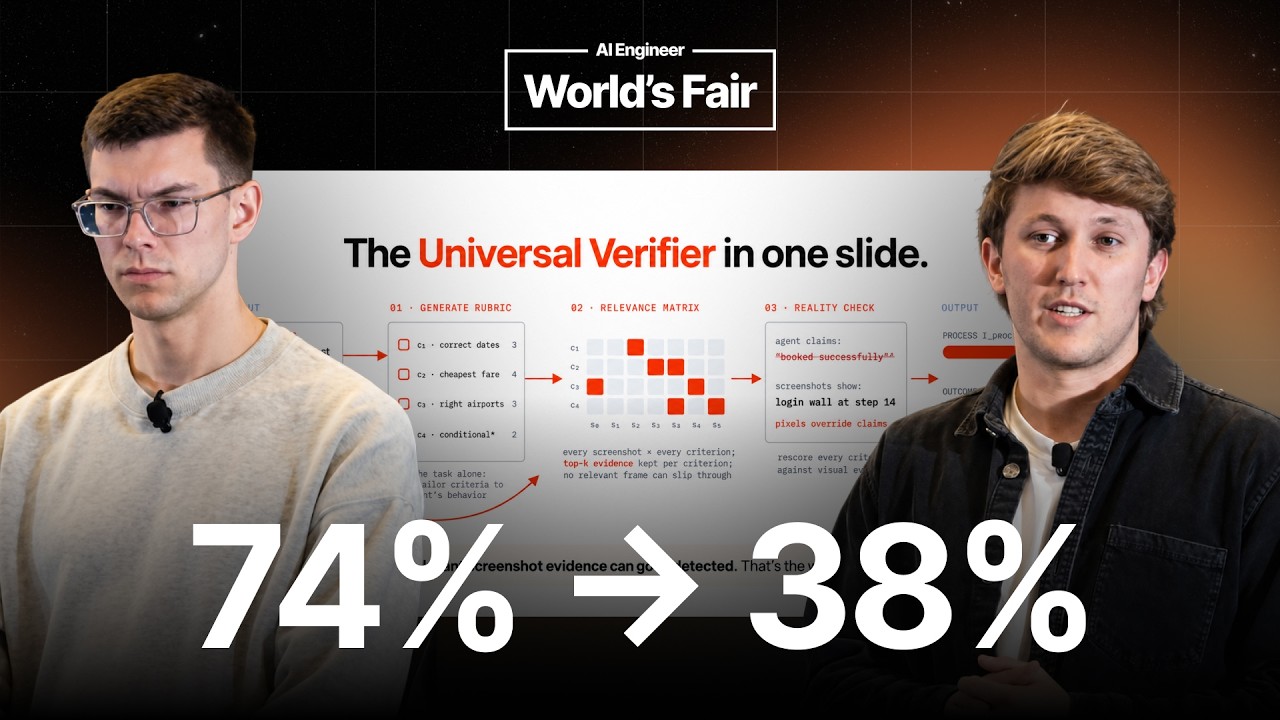
Verifier

Your LLM Judge Is a Confident Liar: Building Better Verifiers — Browserbase

Your LLM Judge Is a Confident Liar: Building Better Verifiers — Browserbase

Browserbase and Microsoft Research unveil their Universal Verifier for computer-use and web agents, addressing the critical flaw of inaccurate LLM-as-judge benchmarks that yield "confident liars." They detail its four guiding principles, demonstrating how it drastically cuts false positives and provides high agreement with human evaluations, leading to better training data. An auto-research experiment highlights the synergy between AI and human expertise in developing robust evaluation systems.
Benchmarks: The Good, the Bad, and the Ugly — Ali Khial, G2i

Benchmarks: The Good, the Bad, and the Ugly — Ali Khial, G2i

Ali Khial exposes critical flaws in popular coding benchmarks, revealing how ambiguous instructions, weak verifiers, and model 'reward hacking' create a disconnect between reported performance and real-world utility. He argues that this leads to a "trust gap" where engineers disregard leaderboards. Khial then outlines five principles for building trustworthy, production-grade benchmarks, emphasizing human-authored instructions, holistic grading, economic value, contamination-free design, and informative leaderboards, urging software engineers to contribute to their improvement.