Ai

What AI gets wrong and what failure teaches us

What AI gets wrong and what failure teaches us

Jennifer Neville discusses her research into "surprising failures" in AI systems, where models, particularly LLMs, struggle with complexity in realistic user workflows. Her team focuses on practical evaluation for multi-turn conversations and agentic knowledge work, emphasizing the need for robust AI that understands context and user intent over time. She offers insights into bridging the gap between user expectations and AI capabilities, advocating for detailed user feedback and outlining the future of human-AI collaboration.
Harness Engineering: How to Build a Software Factory — Dru Knox, Tessl

Harness Engineering: How to Build a Software Factory — Dru Knox, Tessl

Dru Knox of Tessl discusses harness engineering, the discipline for building software factories with AI agents. He outlines a factory's three pillars—autonomy, automation, quality—and introduces inner, outer, and meta loops. Knox explains why this field is challenging and proposes a three-layer architecture: control plane, agent-ready stack, and improvement loops, concluding with key metrics to track progress towards an agent-driven software development future.

Building Cyber Defense for the Agentic Era

Building Cyber Defense for the Agentic Era

Kevin Mandia, founder of Mandiant and CEO of Armadin, discusses how AI is revolutionizing cybersecurity. He explains that machine-speed attacks necessitate autonomous defenses, detailing Armadin's approach of continuous AI-driven red teaming to find zero-days and build real-time defense mechanisms. The conversation also explores the transformation of the SOC, the demise of traditional pentesting, and the challenges of building a company at AI speed.

How AI Agents Pay: Checkout in ChatGPT and Google AI Mode — Sam Parsons, PayPal

How AI Agents Pay: Checkout in ChatGPT and Google AI Mode — Sam Parsons, PayPal

Sam Parsons from PayPal Enterprise Payments explores three distinct ways merchants can accept payments initiated by AI agents: Instant Checkout in ChatGPT (Agentic Commerce Protocol), Google AI Mode (Universal Commerce Protocol), and a custom MCP app with an external checkout page. He details the technical flows, emphasizing tokenization for secure transactions and outlining the trade-offs between in-agent experiences and full merchant control.

Advanced Workshop: Mastering AI Observability — Doug Guthrie, Braintrust

Advanced Workshop: Mastering AI Observability — Doug Guthrie, Braintrust

Doug Guthrie showcases how Braintrust connects observability with AI agent improvement. Using a support agent, he demonstrates setting up tracing, establishing evaluation baselines, and publishing custom scorers. The workshop delves into Braintrust's Topics feature for discovering unknown failure modes, configuring online automations, and importing real-world traces. A key focus is on automating the improvement cycle: using the Loop assistant for SQL-based trace analysis, integrating coding agents with Braintrust CLI skills to propose code changes, add regressions, run evals, and generate pull requests, thereby closing the feedback loop from production to development.

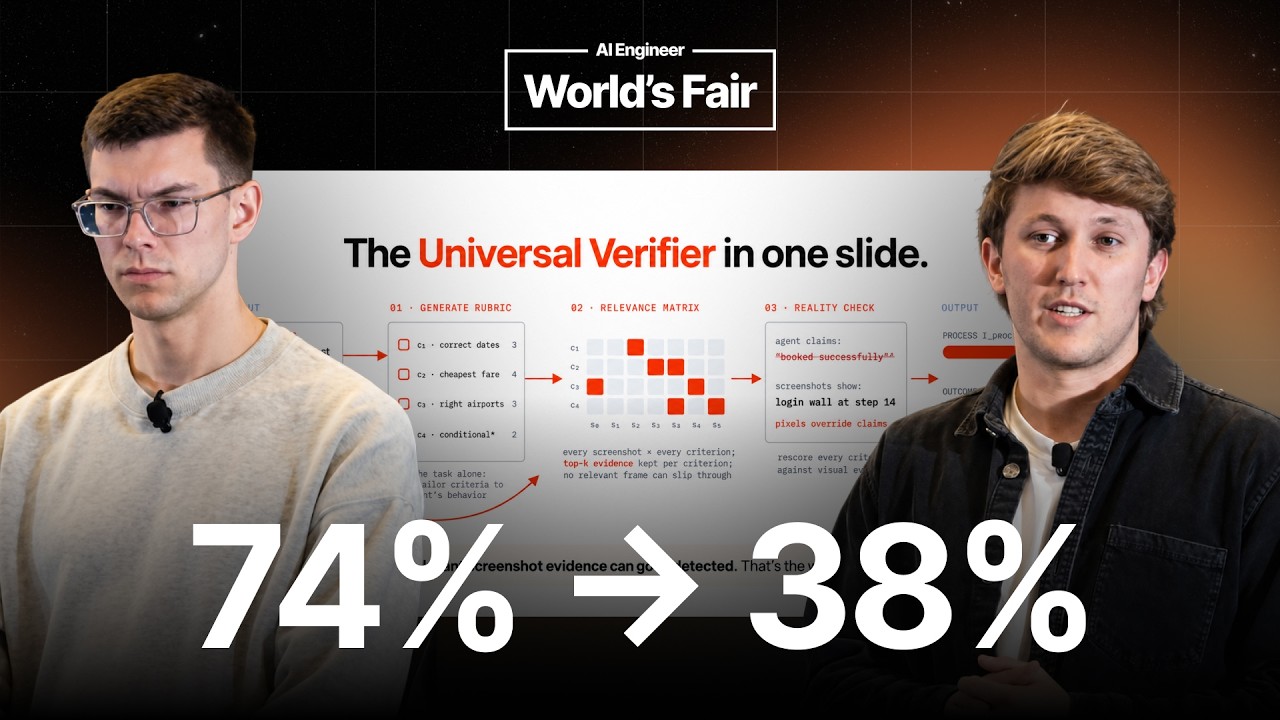
Your LLM Judge Is a Confident Liar: Building Better Verifiers — Browserbase

Your LLM Judge Is a Confident Liar: Building Better Verifiers — Browserbase

Browserbase and Microsoft Research unveil their Universal Verifier for computer-use and web agents, addressing the critical flaw of inaccurate LLM-as-judge benchmarks that yield "confident liars." They detail its four guiding principles, demonstrating how it drastically cuts false positives and provides high agreement with human evaluations, leading to better training data. An auto-research experiment highlights the synergy between AI and human expertise in developing robust evaluation systems.