Post training

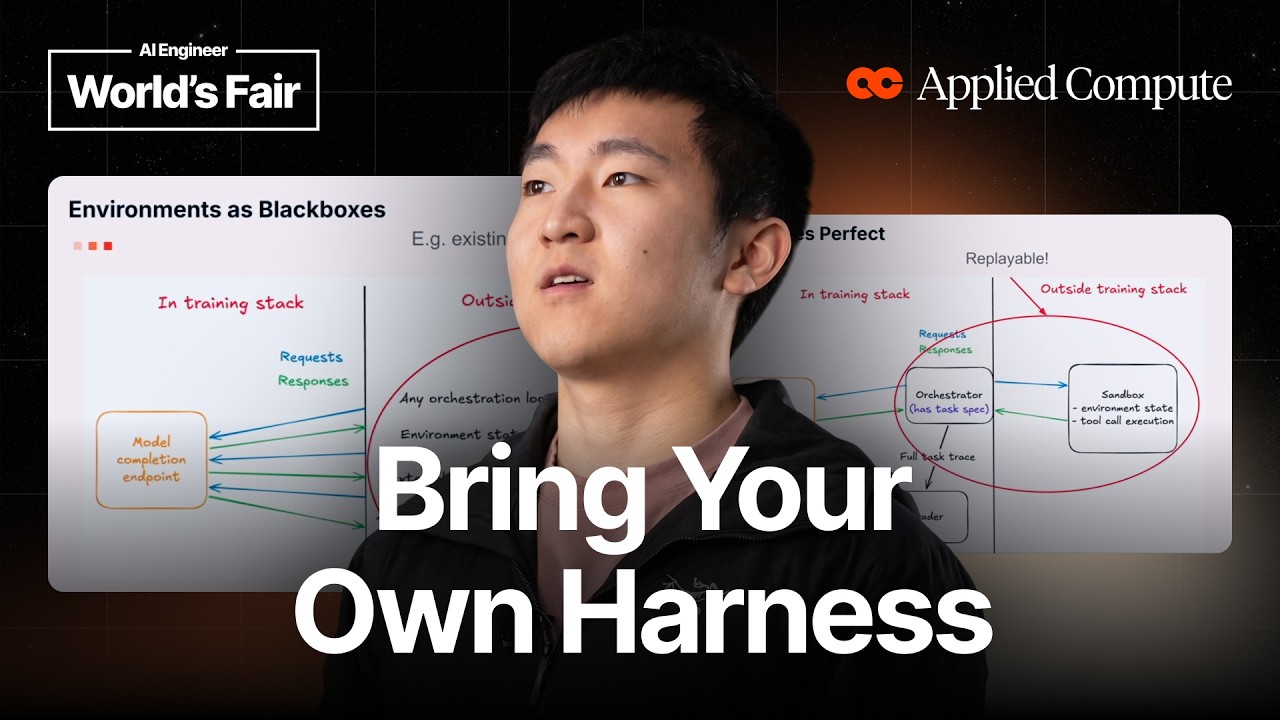
Learning on the Job: The Future of Post-Training — Raymond Feng, Applied Compute

Learning on the Job: The Future of Post-Training — Raymond Feng, Applied Compute

Raymond Feng presents Applied Compute's approach to training custom AI models that learn "on the job" using reinforcement learning. He details the evolution from controlled Q&A to synthetic environments, highlighting the core GRPO-style loop. A major focus is tackling the challenges of environment fidelity and "reward hacking" in simulated settings. The discussion then moves to the complexities of training directly within real-world enterprise harnesses, addressing issues like non-replayability and off-policy data. Feng concludes by outlining frontier research in self-distillation, automated data pipelines, and qualitative feedback, envisioning a future where models continuously learn and self-evaluate from every interaction, making "experience the dominant medium of improvement."
The Prime Intellect Stack — Will Brown, Prime Intellect

The Prime Intellect Stack — Will Brown, Prime Intellect

Deep dive into Prime Intellect's open-source ecosystem for post-training LLMs, covering the modular Verifiers V1 environment design, the asynchronous and scalable Primer RL training framework, and the Lab platform for hosted training and fine-tuning. Learn about advanced reward systems, the interception server pattern, and tokenization control with the Renderers library, all designed to enable frontier agentic model development.

Reinforce Adjoint Matching: Scaling Diffusion RL

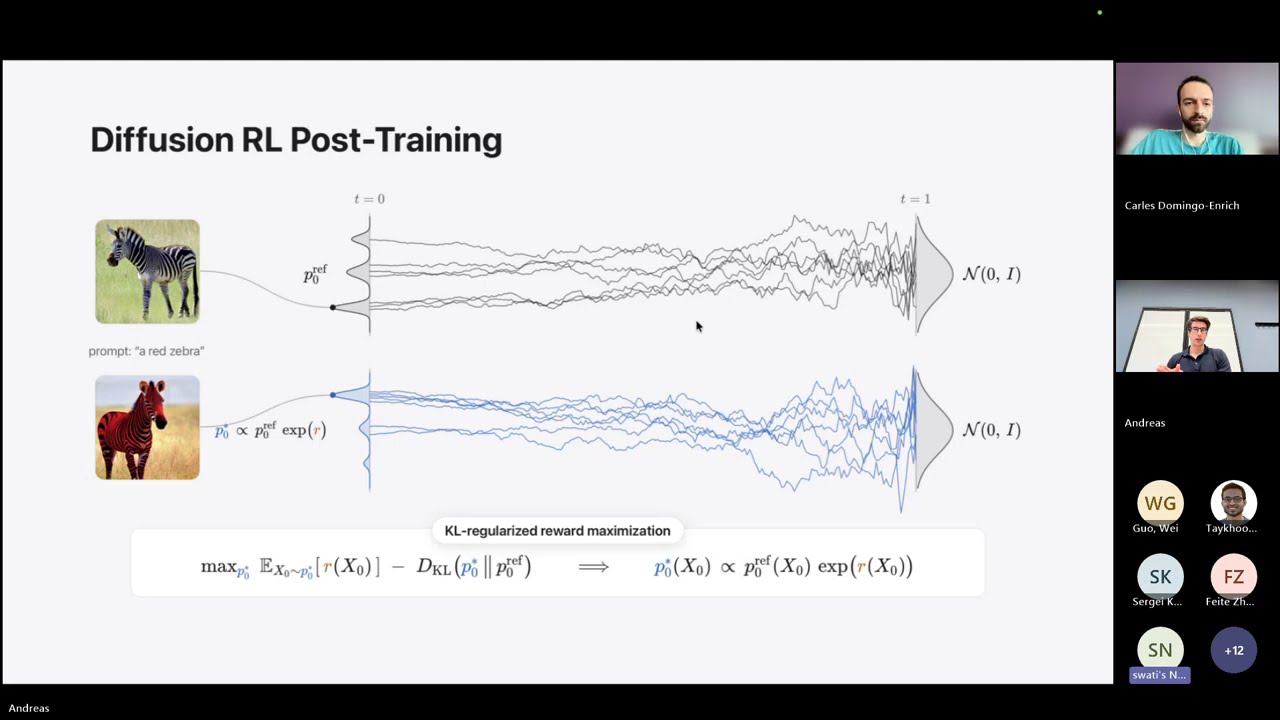
Reinforce Adjoint Matching: Scaling Diffusion RL

Andreas Bergmeister presents Reinforce Adjoint Matching (RAM), a novel method for scalable reinforcement learning post-training of diffusion models. RAM sidesteps the complexity of existing RL approaches by deriving a consistency loss that directly corrects the pre-training target with a reward signal, eliminating the need for costly SDE rollouts or reward gradients. This approach achieves superior performance and up to 50x faster convergence on challenging image generation tasks like complex composability, text rendering, and human preference alignment.

The State of Frontier Post-Training Recipes | Conversation with Finbarr Timbers

The State of Frontier Post-Training Recipes | Conversation with Finbarr Timbers

This discussion with Finbarr Timbers reviews the evolution of frontier post-training recipes, highlighting the shift from simpler SFT-DPO-RL to complex multi-teacher on-policy distillation (MOPD). It covers the organizational challenges of building models like Olmo, the rise of synthetic data and reasoning-focused RL in DeepSeek, and the complexities of integrating expert teachers, while also exploring open questions on environments, specialized APIs, and career strategies in the rapidly changing AI landscape.

Building the GitHub for RL Environments: Prime Intellect's Will Brown & Johannes Hagemann

Building the GitHub for RL Environments: Prime Intellect's Will Brown & Johannes Hagemann

Prime Intellect's Will Brown and Johannes Hagemann discuss the paradigm shift from static prompting to dynamic, environment-based AI development. They introduce their Environments Hub, a platform aimed at democratizing frontier-level training and enabling companies to build specialized models by compounding institutional knowledge.

Post-training best-in-class models in 2025

Post-training best-in-class models in 2025

An expert overview of post-training techniques for language models, covering the entire workflow from data generation and curation to advanced algorithms like Supervised Fine-Tuning (SFT), Direct Preference Optimization (DPO), and Reinforcement Learning (RL), along with practical advice on evaluation and iteration.