Llm

How to build an AI-Native Health Company — Dan Feng, Maven Clinic

How to build an AI-Native Health Company — Dan Feng, Maven Clinic

Dan Feng outlines Maven Clinic's transformation into an AI-native company, driven by the realization that "building is cheap and arguing is expensive" in the AI era. This shift has reshaped planning to short, iterative sprints, revolutionized software development with AI coding tools, forced adaptive changes in code review processes, and necessitated a nuanced, multi-layered approach to ensuring reliability in generative AI systems.
Benchmarking Coding Agents on New vs Legacy Codebases — Denys Linkov, Wisedocs

Benchmarking Coding Agents on New vs Legacy Codebases — Denys Linkov, Wisedocs

Denys Linkov details Wisedocs' journey of refactoring a complex, distributed ML pipeline into a monorepo, benchmarking the process against evolving AI coding tools. He honestly audits whether the six-month effort was justified, or if waiting for more advanced AI would have been better, ultimately concluding that the significant social and technical benefits made the refactor a successful strategic move despite current LLM limitations.

Anthropic's CCA Exam as a Field-Guide for Agentic Engineering — Frank Coyle, UC Berkeley

Anthropic's CCA Exam as a Field-Guide for Agentic Engineering — Frank Coyle, UC Berkeley

Frank Coyle demystifies the Claude Certified Architect exam by dissecting key scenarios and highlighting common anti-patterns in Agentic AI design. He provides actionable best practices, emphasizing effective tool use, context management, specialized agent architectures, and cost-saving techniques, all centered on understanding what to avoid to build robust LLM applications.

Compression at the Edge — Chris Alexiuk, NVIDIA

Compression at the Edge — Chris Alexiuk, NVIDIA

This panel discussion explores the critical role of model compression, particularly quantization, in democratizing AI. It delves into how massive models like GLM 5.2 can be shrunk by over 80% without equivalent performance loss, thanks to techniques like mixed-precision quantization and understanding uneven layer importance. The discussion covers NVIDIA's NVFP4 format, challenges posed by new model architectures, the preference for KL divergence over accuracy benchmarks, and the vision of future AI running efficiently on all local devices.

The Messy Reality of Scale: Synthetic Data and Pre-Training — Marah Abdin & Robert McHardy, poolside

The Messy Reality of Scale: Synthetic Data and Pre-Training — Marah Abdin & Robert McHardy, poolside

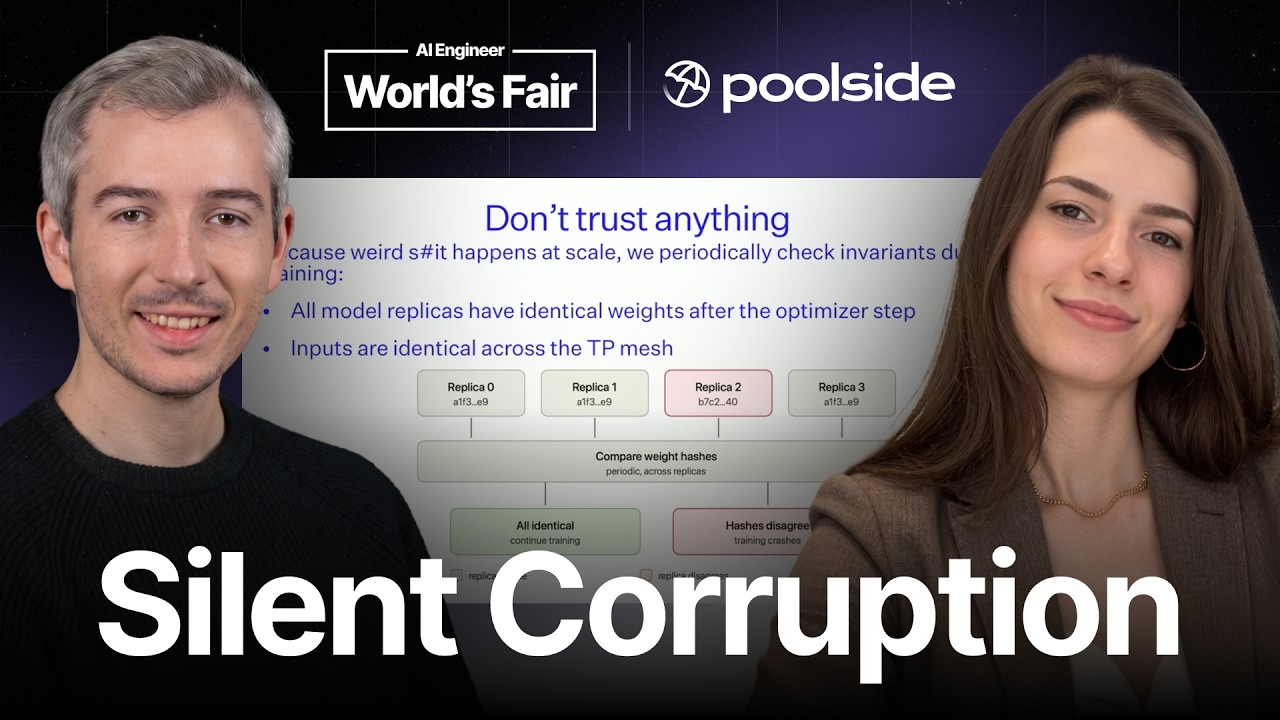
Poolside discusses their innovative approaches to synthetic data generation, pre-training validation, and distributed training challenges. They highlight how modular data pipelines, rigorous replica hash checks, and numerical stability fixes enabled them to scale their LLMs, culminating in the 118B parameter Laguna S model designed for agentic coding, which shows strong early results against leading open-weight models.

Opencode CEO: Blocked, 20X Growth in 6 Months, Building the Coding Agent for the World

Opencode CEO: Blocked, 20X Growth in 6 Months, Building the Coding Agent for the World

Jay V, founder and CEO of Opencode, shares insights into the explosive growth of his platform, an open-source alternative to proprietary coding agents. He details Opencode's journey to 13 million monthly active users and 7 trillion tokens processed daily, attributing its rapid rise partly to an unexpected controversy with Anthropic and the maturing open-source model ecosystem. The discussion delves into global user adoption, the economic shift in AI token consumption, and how Opencode's strategic product design, rooted in 16 years of entrepreneurial persistence, positions it as a critical marketplace for diverse AI models, serving both individual developers and Fortune 500 companies.