Llm as judge

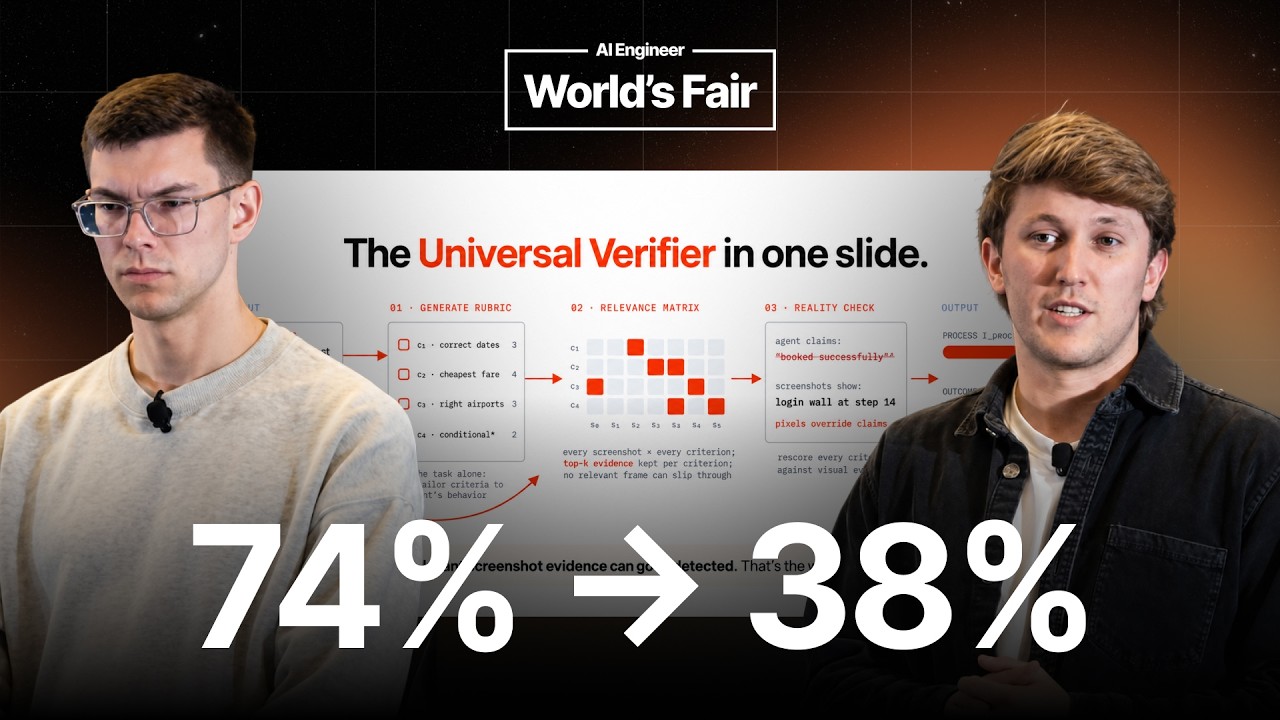
Your LLM Judge Is a Confident Liar: Building Better Verifiers — Browserbase

Your LLM Judge Is a Confident Liar: Building Better Verifiers — Browserbase

Browserbase and Microsoft Research unveil their Universal Verifier for computer-use and web agents, addressing the critical flaw of inaccurate LLM-as-judge benchmarks that yield "confident liars." They detail its four guiding principles, demonstrating how it drastically cuts false positives and provides high agreement with human evaluations, leading to better training data. An auto-research experiment highlights the synergy between AI and human expertise in developing robust evaluation systems.
The Loop Is the Product — Roland Gavrilescu, Introspection

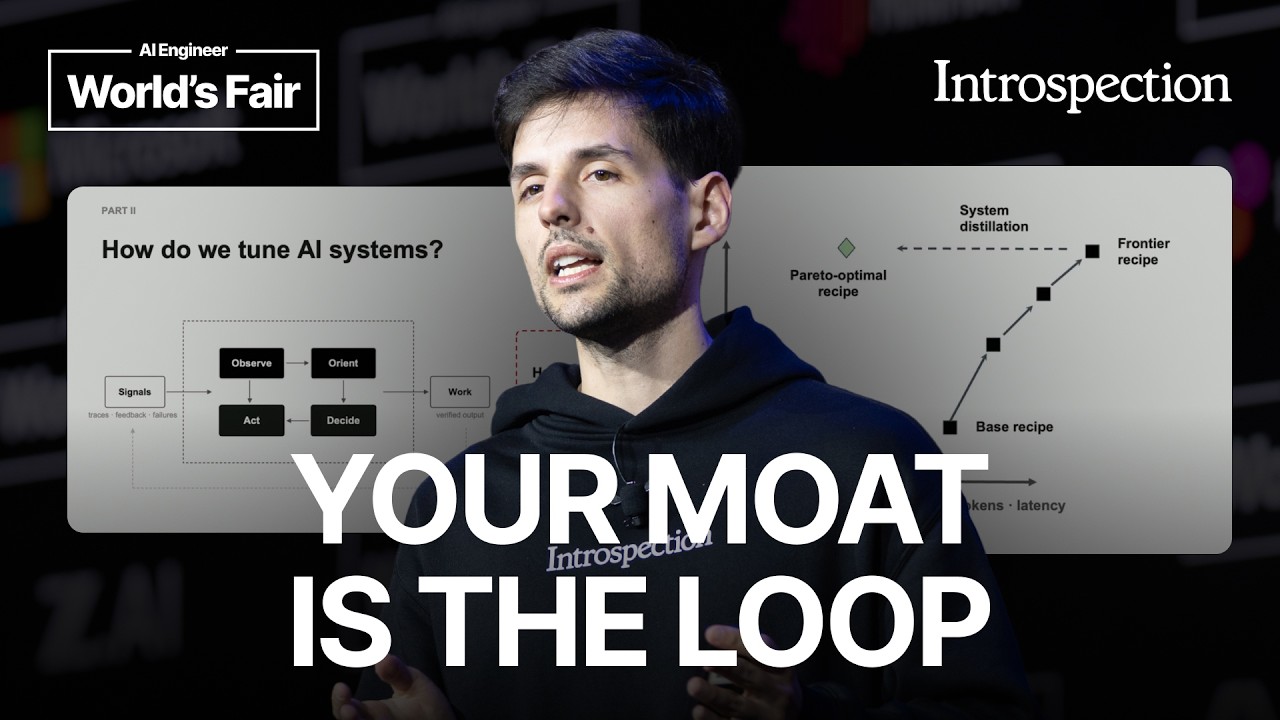
The Loop Is the Product — Roland Gavrilescu, Introspection

Roland Gavrilescu, co-founder and CEO of Introspection and formerly at xAI, presents a blueprint for autoresearch in 2026 built on three ideas: the loop is the product, system distillation is the moat, and valued work per watt is the score to optimize. He illustrates these with the OpenClaw car-haggling loop, the concept of portable agent recipes, and a talent-sourcing agent example that shows how to spot patterns in traces, calibrate judges with humans, and A/B test taste in production.

Frontier results, on device - RL Nabors, Arize

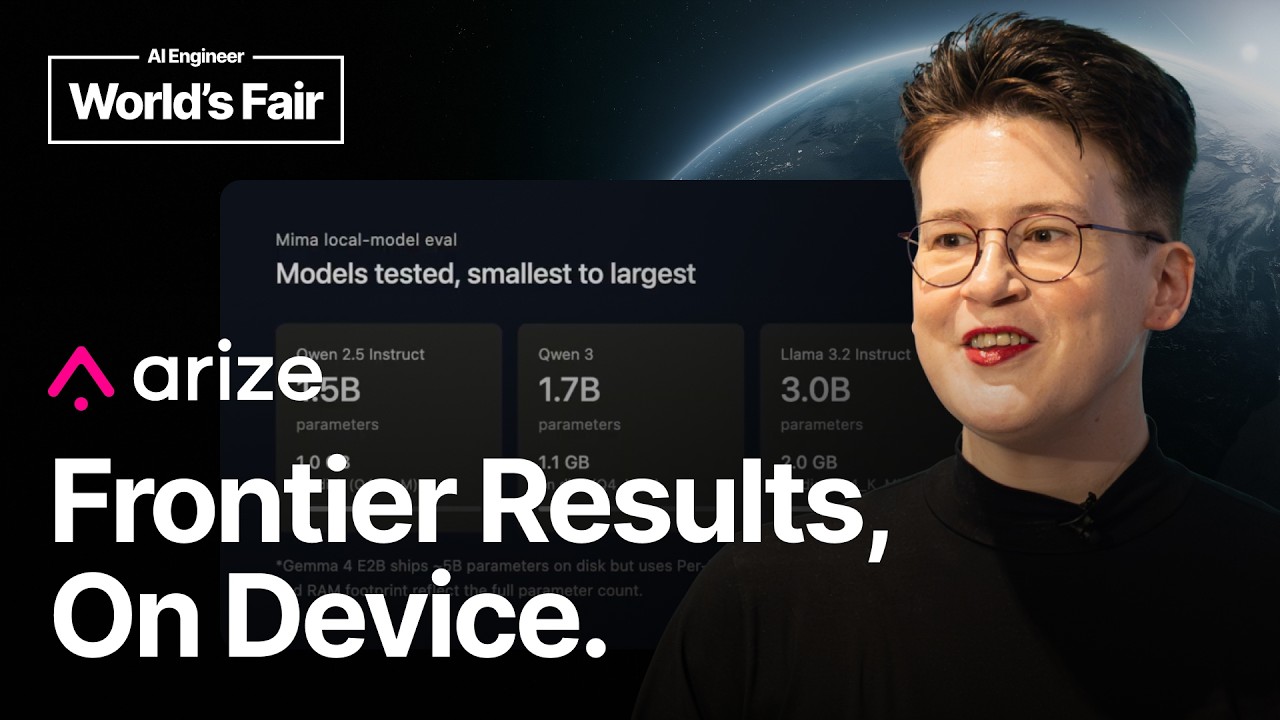
Frontier results, on device - RL Nabors, Arize

RL Nabors discusses the significant costs associated with using frontier AI models, covering security, latency, and financial implications. She introduces a framework for right-sizing AI solutions by leveraging smaller, task-specific models and Small Language Models (SLMs). The framework details how to prove task feasibility, establish success criteria with golden datasets, conduct capability evaluations (using tools like Phoenix), and select the most appropriate "Small And Good Enough" (SAGE) model. Nabors further demonstrates how prompt engineering, particularly few-shot prompting, and post-processing can close performance gaps with larger models, while advocating for continuous regression evaluations to maintain performance integrity. The overarching message is to "prototype big, deploy small" to optimize AI deployments.