Feature

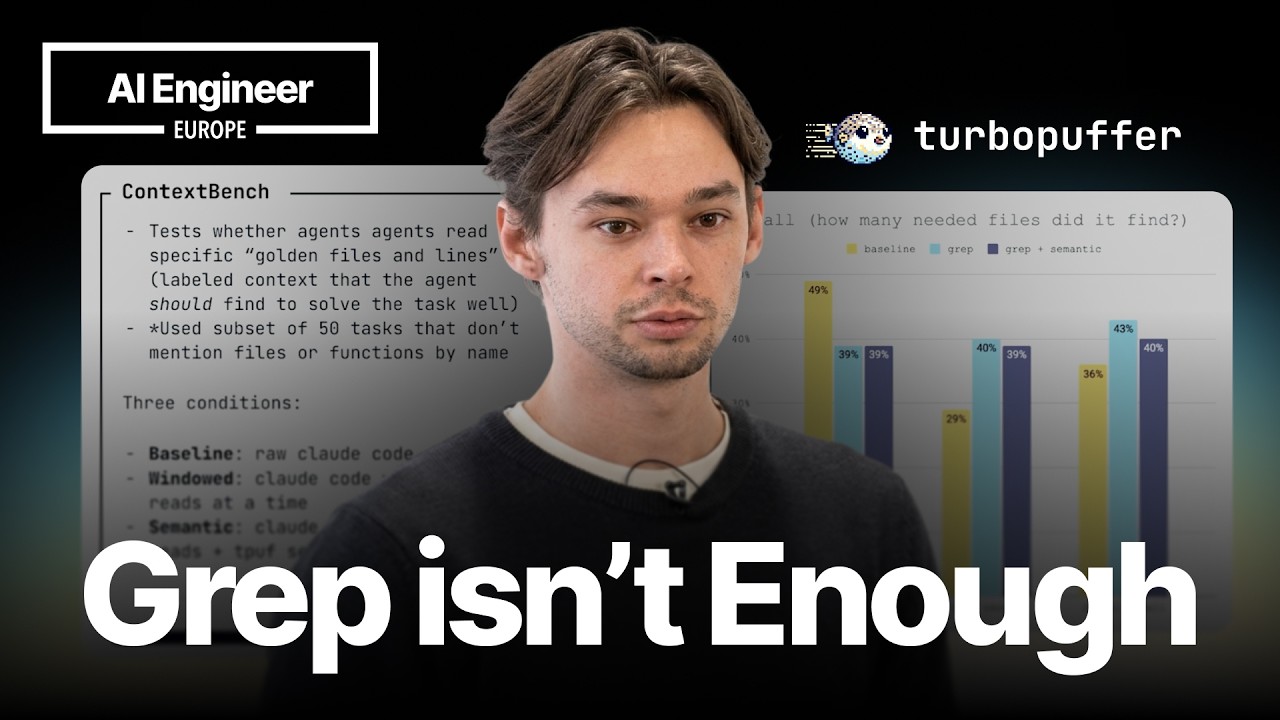
Benchmarking semantic code retrieval on Claude Code — Kuba Rogut, Turbopuffer

Benchmarking semantic code retrieval on Claude Code — Kuba Rogut, Turbopuffer

A detailed benchmark analysis comparing raw Claude Code's performance with windowed grep and Turbopuffer's semantic search for code retrieval in LLM agents. The study reveals significant improvements in file precision (65% to 87%) and reduced wasted reads (1 in 3 to 1 in 8) with semantic search, while highlighting the importance of the agent's understanding of when to use retrieval tools.
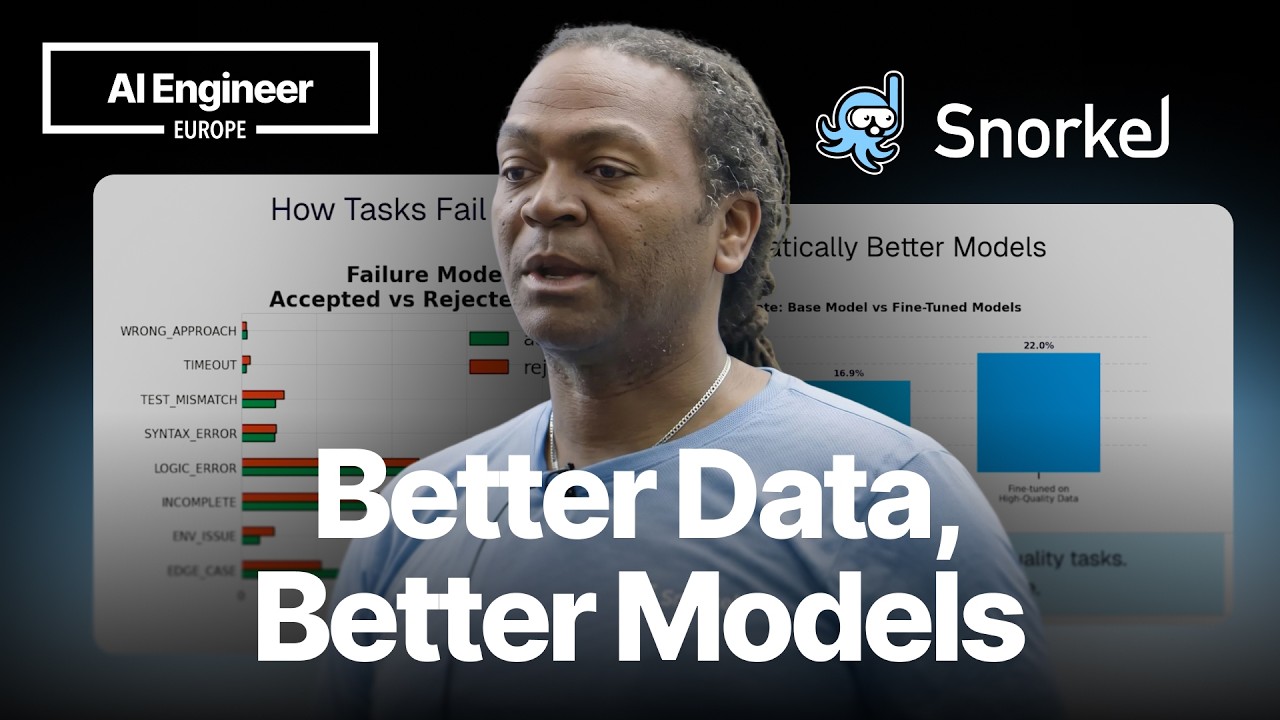
Task Fidelity Scaling Laws — Kobie Crawdord, Snorkel

Task Fidelity Scaling Laws — Kobie Crawdord, Snorkel

An experiment by Snorkel AI reveals that in agentic AI training, the quality of tasks is paramount. Using the same model and compute, fine-tuning on high-quality tasks yielded a 6% performance improvement, a 5x greater uplift compared to the 1% gain from low-quality tasks. The key difference lies in the nature of the tasks: high-quality tasks are genuinely harder, featuring more tool calls and cleaner failure modes that provide a meaningful learning signal. In contrast, low-quality tasks often fail due to ambiguity and environmental noise, hindering effective model improvement.

GitHub’s Agent Era: 14x Commits, 200M Developers, Copilot’s Next Act — Kyle Daigle

GitHub’s Agent Era: 14x Commits, 200M Developers, Copilot’s Next Act — Kyle Daigle

GitHub COO Kyle Daigle discusses the new era of AI agents from the inside. He covers how he uses AI for leadership, the shift from "mega-skills" to "micro-skills," and how GitHub is navigating a 14x growth in commits. The conversation goes deep on the evolution of Copilot, the future of PRs in an agent-driven world, the challenges of scaling, and Microsoft's vision for an ambient AI operating system.

He Raised $70M to Cure Every Disease With AI

He Raised $70M to Cure Every Disease With AI

Samuel Rodriques, founder of Edison Scientific, shares his journey from physics to building an AI scientist named Kosmos. He discusses how AI agents are already making novel discoveries, including a potential cure for blindness, and are poised to revolutionize drug discovery. The conversation dives into AI's strengths in high-throughput reasoning, the critical bottlenecks in clinical trials, proposed reforms for the US medical system, and whether human scientists will still be needed in an age of hyper-intelligent AI.

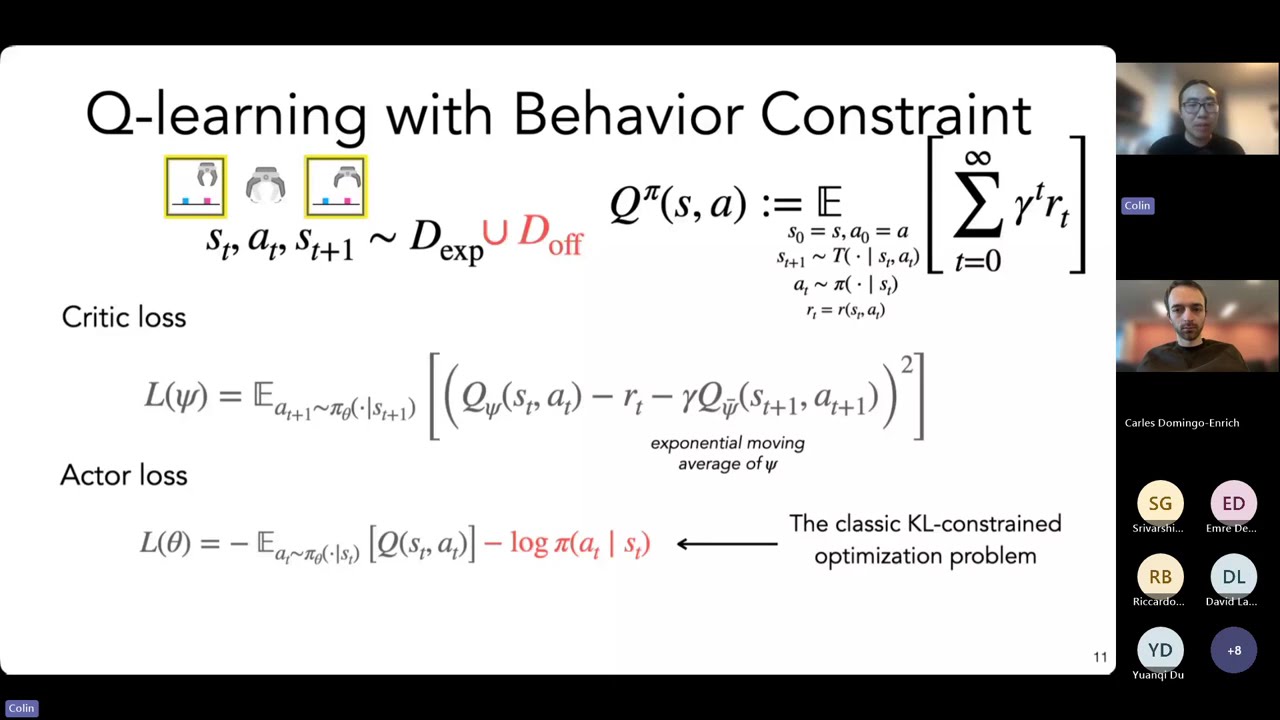
Q-learning with Flow-Matching Policies

Q-learning with Flow-Matching Policies

This talk explores methods for optimizing expressive, multi-modal policies, such as those based on flow-matching, with off-policy reinforcement learning. The speaker presents two novel algorithms, FQ-RL and CAM, designed to overcome the instability of backpropagation through multi-step generative models, enabling effective online self-improvement and adaptation for robotic manipulation tasks.

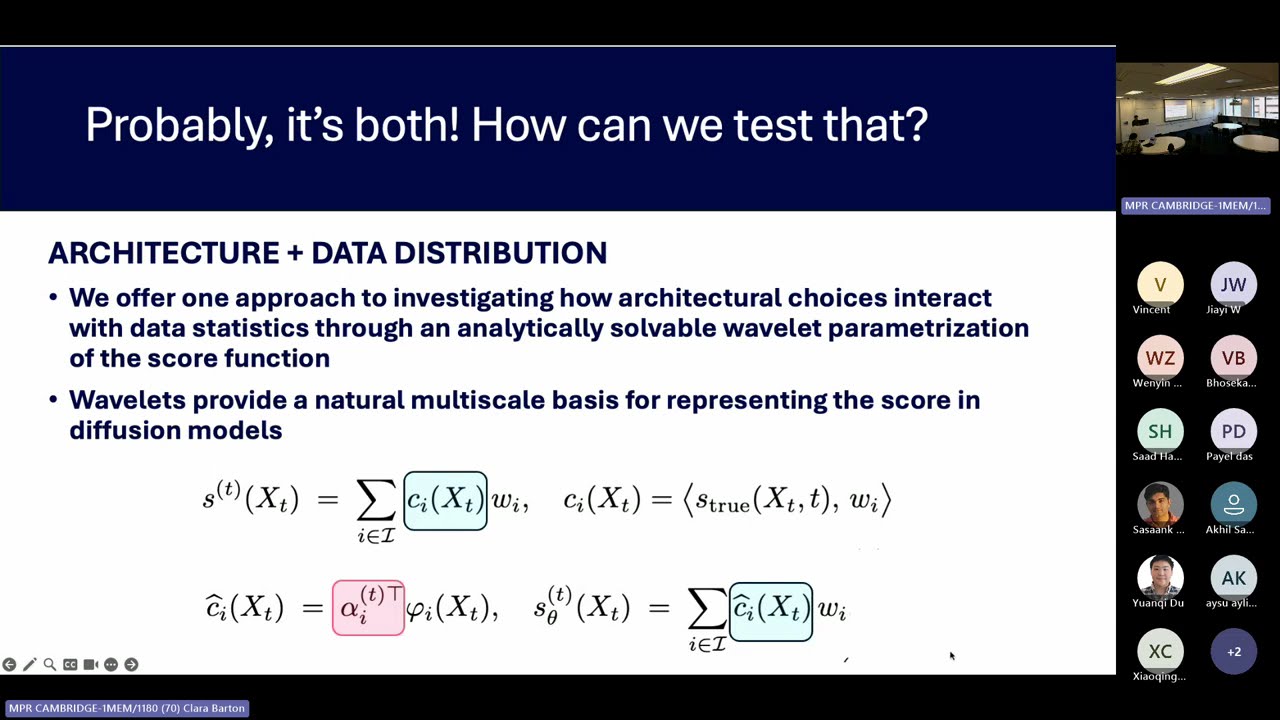
Where the Score Lives: What Wavelets Reveal About Diffusion Models

Where the Score Lives: What Wavelets Reveal About Diffusion Models

This talk explores the paradox of why diffusion models generalize rather than memorize. It introduces an analytically tractable, wavelet-based parameterization of the score function, allowing for an interpretable analysis of how architectural biases (like locality) and data statistics interact to influence denoising performance and generalization.