Benchmarking

How to Test AI Agents When No Benchmark Exists — Nathanael Weill, Air Canada

How to Test AI Agents When No Benchmark Exists — Nathanael Weill, Air Canada

Nathanael Weill of Air Canada explains how to evaluate AI agents when no public benchmark exists and expert time is scarce: start from a known answer, generate the input from it, and check whether the agent recovers it. He covers lessons from a telecom RAG project that moved from one expert-graded test a week to dozens a day, and five ways to build test sets for a supplier contract review agent, along with why code-based checks are preferred over LLM judges.
AI Safety Fact vs. Fiction | YC Paper Club

AI Safety Fact vs. Fiction | YC Paper Club

This episode of Paper Club addresses AI safety from a scientific perspective, contrasting it with recent media sensationalism. Stanford professors Clark Barrett and Mykel Kochenderfer discuss how automated reasoning can mathematically prove code security, how aircraft stress-testing methods are being adapted for language models, and the potential need for an NTSB-like agency for AI, highlighting the real-world engineering challenges and solutions for AI safety.

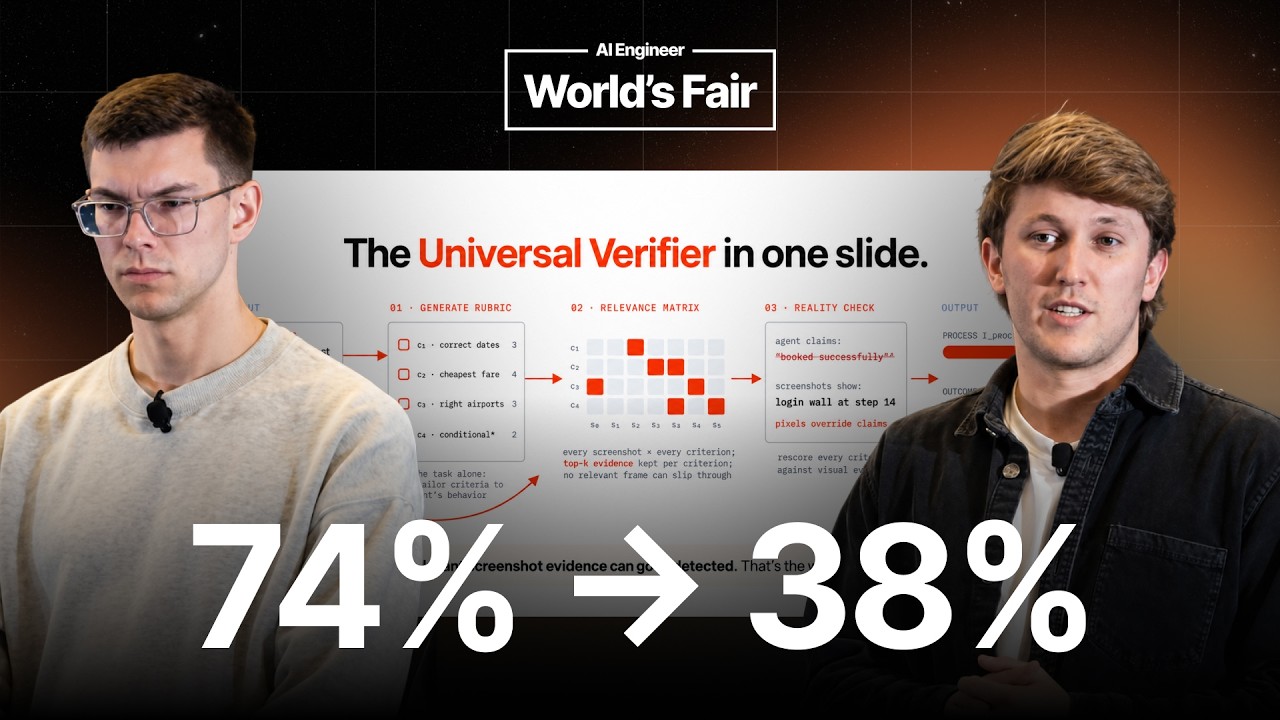
Your LLM Judge Is a Confident Liar: Building Better Verifiers — Browserbase

Your LLM Judge Is a Confident Liar: Building Better Verifiers — Browserbase

Browserbase and Microsoft Research unveil their Universal Verifier for computer-use and web agents, addressing the critical flaw of inaccurate LLM-as-judge benchmarks that yield "confident liars." They detail its four guiding principles, demonstrating how it drastically cuts false positives and provides high agreement with human evaluations, leading to better training data. An auto-research experiment highlights the synergy between AI and human expertise in developing robust evaluation systems.

The Best Models Still Reason Like Toddlers — Andrew Dai, Elorian

The Best Models Still Reason Like Toddlers — Andrew Dai, Elorian

Andrew Dai discusses how current frontier models struggle with visual reasoning, often hallucinating or failing to understand spatial relationships and context. He highlights limitations of existing benchmarks and proposes a 'visual thinking' paradigm, exemplified by Elorian's approach using native visual chain of thought, new data, and architectural advances to tackle real-world challenges in robotics, construction, and mechanical design.

The Death of Developer Advocates — Stephanie Jarmak, Sourcegraph

The Death of Developer Advocates — Stephanie Jarmak, Sourcegraph

Stephanie Jarmak argues that Developer Relations (DevRel) isn't dead, but its audience has shifted to include AI agents. She introduces the "Agent Advocate" role, focusing on measuring agent experience (e.g., through CodeScaleBench), optimizing for "Generative Engine Optimization" (GEO), and adapting traditional DevRel principles like enablement and community for this new user. The core message is that designing for agents, like a curb cut, ultimately improves the experience for all human developers.

Going In Deep On Data | YC Paper Club

Going In Deep On Data | YC Paper Club

Three experts discuss the evolving landscape of data in AI, covering its critical role in model performance, challenges in sourcing and evaluating expert data, the development of advanced data generation techniques for diffusion models, and the complexities of multilingual pre-training.