It’s Tokens All The Way Down: How RLMs are Different — Kevin Madura, AlixPartners
Kevin Madura introduces Recursive Language Models (RLMs), a paradigm shift where an LLM treats its context as an interactable object within a REPL, rather than mere tokens. This allows for direct computation, recursive decomposition of problems by delegating to sub-models, and significantly mitigates context rot, outperforming traditional RAG, agents, and tool calls. Use cases range from complex data analysis and long document processing to code auditing and harness optimization, hinting at a future where models are natively RLM-aware.
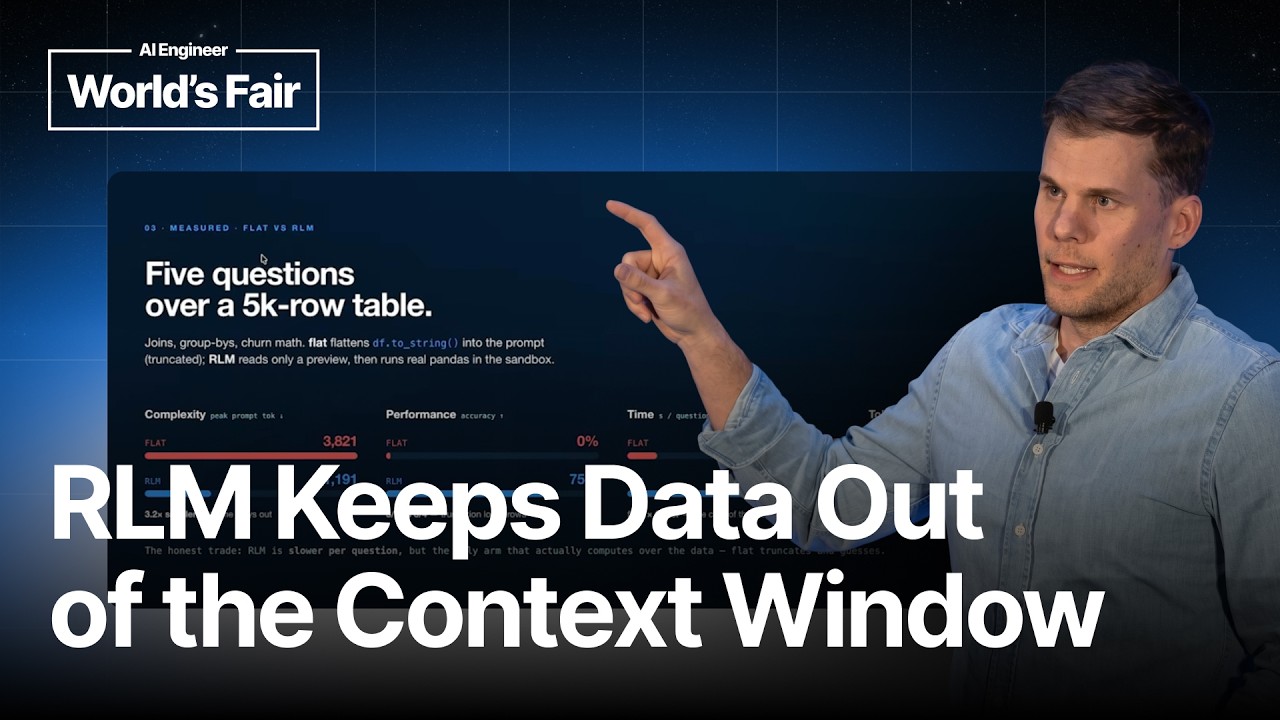
Kevin Madura introduces Recursive Language Models (RLMs) as a novel approach to overcome limitations in traditional LLM interactions. An RLM fundamentally differs by treating its context not as a mere sequence of tokens, but as a symbolic object residing within an interactive environment, typically a Python REPL. This allows the model to interact with, slice, compute over, and iterate on input data as variables, akin to a human user typing in a Jupyter notebook. This is a significant departure from conventional tool calls, which often involve passing static JSON strings back and forth.
Key Differentiators and Mechanisms
- Symbolic Interaction: The RLM interacts directly with a symbolic environment (e.g., REPL) where data lives as variables, rather than merely attending to tokens in a fixed context window. This enables dynamic computation and manipulation of the input.
- Recursive Delegation: RLMs can delegate complex sub-problems to other LLMs, often to themselves, each with their own parameters, within the same REPL environment. This allows for recursive decomposition of challenging tasks, where only the relevant results are returned to the main context.
- “Bitter Lesson Pilled”: The philosophy is that as models become more capable, they should be entrusted with greater autonomy to figure out solutions on their own, allowing for higher levels of abstraction.
Performance and Context Management
RLMs demonstrate significantly better performance on long-context tasks, such as those in the Ulong and BrowseComp benchmarks, outperforming other models. Notably, they also offer a more cost-effective solution compared to complex tool-calling setups like GPT-5 with BM25.
Context Rot Avoidance: A major advantage of RLMs is their ability to mitigate “context rot” – the degradation of performance as the context window fills up. Because the full context lives as a variable in the REPL and subtasks are offloaded to sub-models, the main model’s context window doesn’t fill as quickly. It only receives the salient results from delegated tasks, enabling efficient handling of vast amounts of information.
Comparison to Existing Approaches
- RAG (Retrieval Augmented Generation): RAG approaches typically “stuff” the context window with retrieved information, leading to quality degradation as context size increases.
- Agents and Tool Calls: These methods usually involve shuttling JSON strings, resulting in a loose coupling between logic, execution, and results. This lacks the tight integration and direct symbolic interaction offered by RLMs.
- Anthropic’s Workflows: Kevin notes that recent advancements like Anthropic’s Workflows exhibit similar principles, where intermediate results live in script variables, confirming the industry’s move towards this paradigm.
Use Cases and Benchmarks
RLMs are particularly well-suited for:
- Large or dense input contexts.
- Generating large outputs (e.g., hundreds of thousands of lines).
- Tasks amenable to recursive decomposition (e.g., analyzing complex legal texts, exploring vast datasets).
- Longer horizon sessions.
They excel where traditional models struggle, such as summing numbers buried across 30,000 tokens or interacting with data frames. Benchmarks like the “Long Chain of Thought” show accuracy improvements from 2.6% to 45.4%, with the largest gains on tasks that reduce cleanly to code (e.g., logic puzzles, chemistry).
Real-World Applications and Libraries
Several open-source libraries (e.g., DSPI, Ax, Predict RLM, Fast RLM) are implementing RLM principles. Case studies highlight their practical utility:
- Cohort Analysis: An RLM can process multiple data frames, reason, write code, and iterate within its REPL to perform complex cohort retention analysis, deciding when to submit a final, structured answer.
- Invoice Consolidation (Trampoline AI / Predict RLM): Consolidating inventories from directories of long, complex invoices without needing manual chunking or embedding, focusing on abstract goals rather than context engineering. Predict RLM leverages DSPI for schema enforcement between main and sub-LLM calls, enhancing readability and potentially improving performance for smaller models.
- Log Data Analysis: An RLM can process arbitrary log data to surface interesting patterns and insights.
- Agent Harness Optimization (Halo Project): An RLM analyzes long traces of agent tasks to meta-optimize the agent harness itself, recommending better configurations.
- Code Security Auditing: An RLM can be used to analyze large codebases (e.g., 500,000 lines) to generate security reports with minimal context engineering.
The Future of RLMs
Madura posits that the true potential of RLMs will be unleashed when models are explicitly post-trained to be “RLM-aware.” This native understanding and utilization of the RLM methodology promises to make current LLM capabilities “pretty crazy pretty quick.”