Agent harness optimization

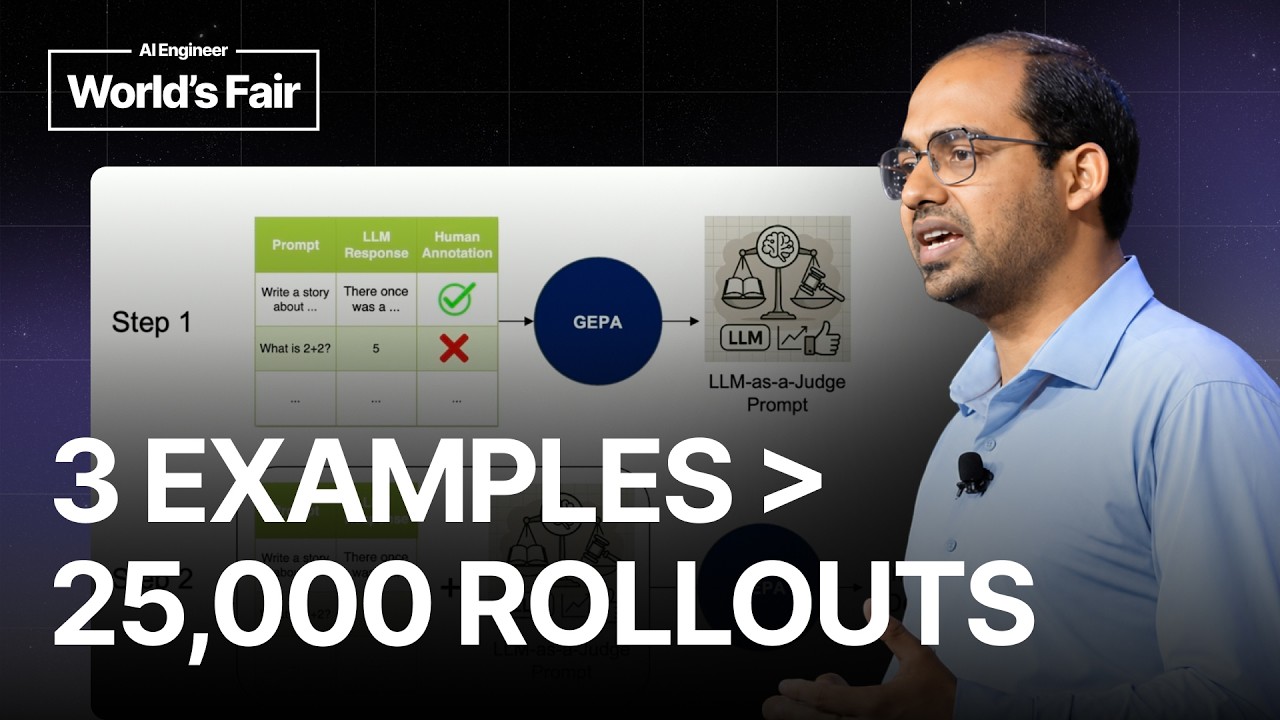
Beating RL With Reflection: GEPA and Optimize Anything — Lakshya A. Agrawal, GEPA

Beating RL With Reflection: GEPA and Optimize Anything — Lakshya A. Agrawal, GEPA

Lakshya Agrawal, creator of GEPA and a PhD student at UC Berkeley's Sky Computing Lab, presents reflective optimization as an alternative to scalar-reward reinforcement learning. GEPA lets a model read full rollout traces, including reasoning, tool calls, and error messages, and rewrite prompts from that feedback, with a Pareto candidate pool guarding against local optima. The talk covers the GEPA vs. GRPO sample-efficiency comparison, domain-knowledge discovery, the Optimize Anything API for text-based artifacts like code, harnesses, and skills, and production results from Databricks, Snorkel, and others.
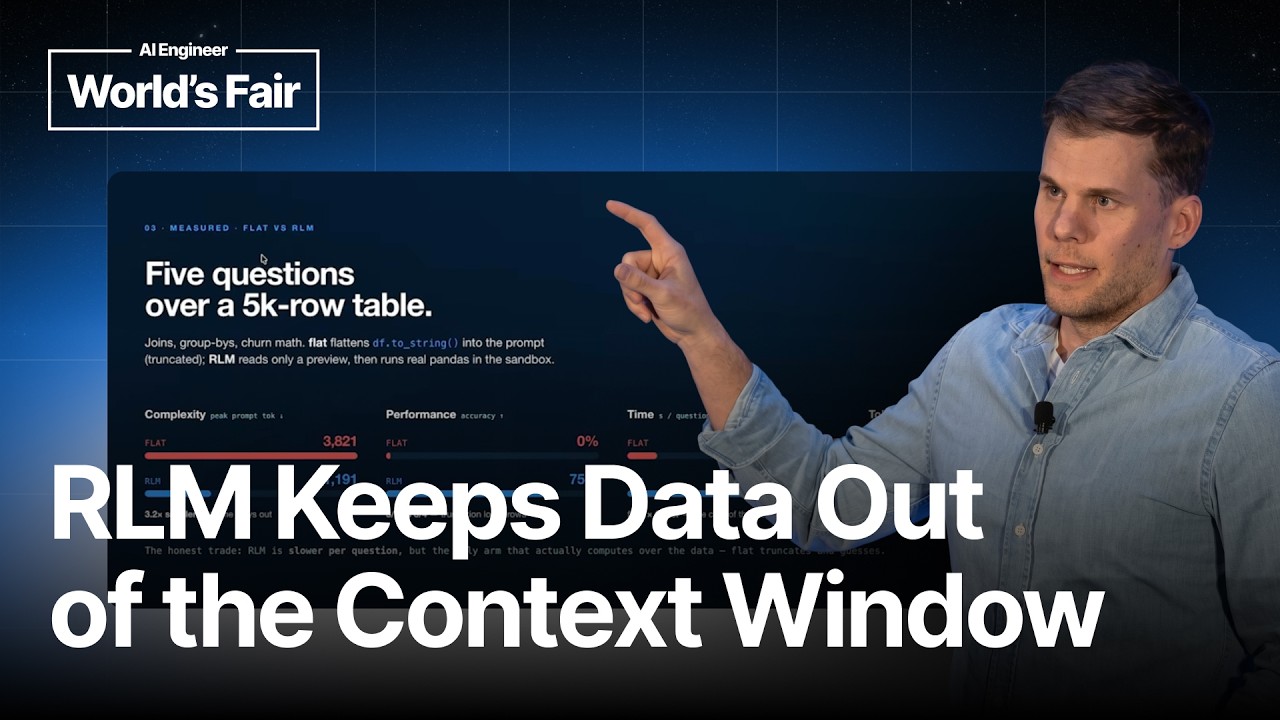
It’s Tokens All The Way Down: How RLMs are Different — Kevin Madura, AlixPartners

It’s Tokens All The Way Down: How RLMs are Different — Kevin Madura, AlixPartners

Kevin Madura introduces Recursive Language Models (RLMs), a paradigm shift where an LLM treats its context as an interactable object within a REPL, rather than mere tokens. This allows for direct computation, recursive decomposition of problems by delegating to sub-models, and significantly mitigates context rot, outperforming traditional RAG, agents, and tool calls. Use cases range from complex data analysis and long document processing to code auditing and harness optimization, hinting at a future where models are natively RLM-aware.