Build AI Systems for Discernment, Not Approval - Angel Ortmann Lee, Duolingo
The talk addresses the critical flaw in human-in-the-loop AI: humans often surrender cognitive effort, leading to "automation bias" rather than true discernment. Through a Duolingo English Test case study and various interaction design examples, it demonstrates how engineering the human-AI interface—rather than just the model or oversight—can elicit critical thinking, generate high-quality data, and foster a virtuous cycle of AI improvement.
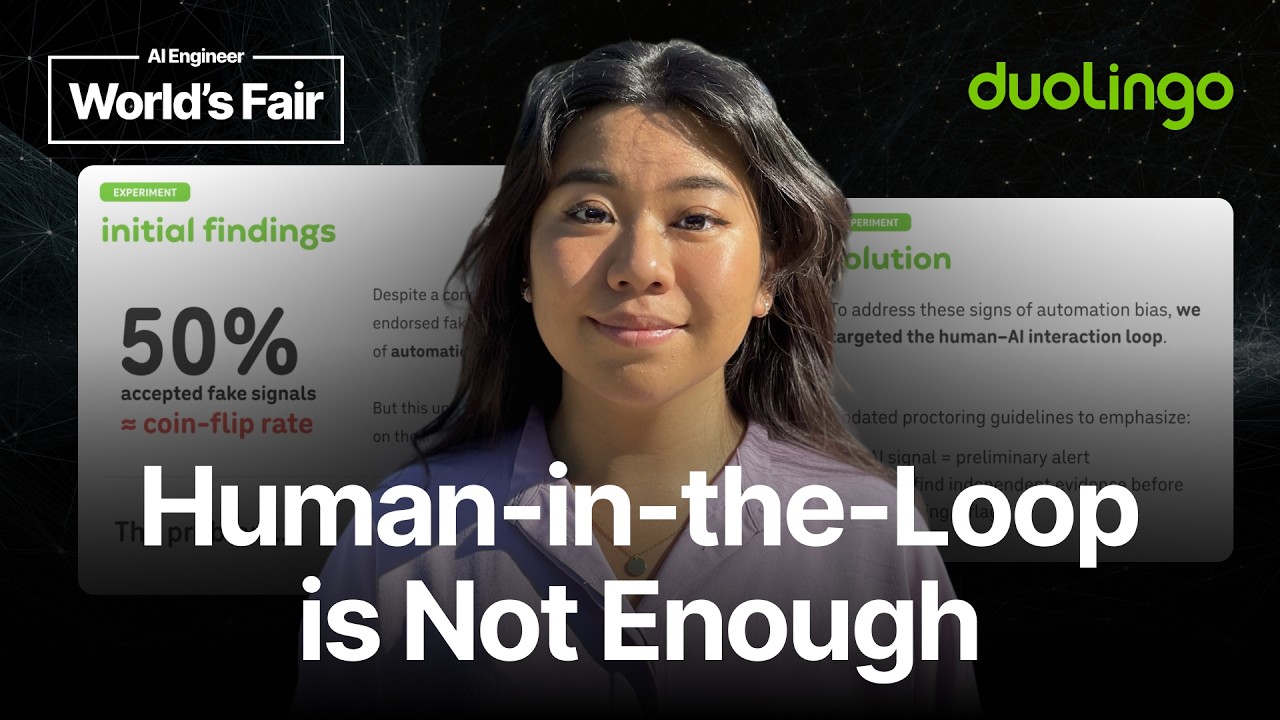
Angel Ortmann Lee, a Software Engineer at Duolingo, delivered a talk titled “The Human in Your Loop Isn’t Thinking,” emphasizing the critical need to design AI systems for discernment rather than mere approval. The core premise is that while human-in-the-loop (HITL) AI aims to ensure accuracy, safety, and ethical decision-making, it often falls short due to an underexamined assumption: that human involvement genuinely leads to critical thinking.
The Problem: Cognitive Surrender and Automation Bias
Modern society increasingly delegates cognitive tasks to AI, fostering a high level of trust. This phenomenon, termed “cognitive surrender” by Shaw & Nave (Wharton, 2026), describes how humans forgo deliberation and adopt AI outputs with minimal scrutiny. A study found that participants accepted AI answers over 80% of the time, even when incorrect, leading to a 15 percentage point decrease in human performance when the AI was wrong. This indicates that humans are “taking in that AI cognition and not really thinking critically.”
Duolingo English Test (DET) Case Study
The Duolingo English Test (DET), a high-stakes, remotely proctored exam, presented a real-world example. To ensure security, the DET employs AI-assisted monitoring for cheating, with human proctors conducting a final review of video footage and AI results. The team investigated their AI copy typing detection system, which flags anomalous keystroke patterns indicative of transcribing rather than composing. The model itself is conservative with a 1% false positive rate.
In a controlled experiment, experienced human proctors, consistently scoring over 90% in accuracy calibration, were presented with sessions containing fabricated AI cheating alerts (i.e., no actual cheating). Despite their expertise, they “accepted 50% of these fake signals, meaning they were falsely accusing people of cheating half the time.” This “coin flip rate” was a strong indicator of automation bias, where proctors deferred judgment to AI without seeking corroborating evidence.
The problem was not the model or the skilled proctors but the human-AI interaction. A simple “copy change” in the proctoring guidelines dramatically improved discernment. Proctors were explicitly reminded that:
- The AI signal is only a preliminary alert; they are the final decision-maker.
- They must find independent evidence in video footage before upholding a flag. This minor change resulted in a 21% increase in accurate rejections, shifting from 50% to 71% correctly identifying non-cheating sessions. This demonstrated that engineering the interaction, rather than tweaking models or increasing oversight, was key.
Cyclical Nature of Human-AI Interaction and the Feedback Flywheel
The human-AI interaction is not linear but cyclical: Model Output → Interaction → Human Behavior → Data for Evals → Model Improvement. While human behavior cannot be directly controlled, the interaction design can be tweaked to elicit desired behaviors and generate high-quality data.
- Vicious Cycle: A confident model paired with an interface that doesn’t encourage deliberation leads to human “rubber stamping.” Positive signals are logged as truth, even if incorrect, polluting data and making the model overconfident while humans defer further.
- Virtuous Cycle: An interface that forces independent judgment elicits critical thinking and surfaces genuine disagreements. This provides true positive and negative labels, leading to honest data that drives targeted model improvements.
Examples of Effective Interaction Design
-
Headphone Detection (Duolingo):
- Ineffective: A single “yes/no” question conflating two issues: “Were headphones detected?” and “Is this a violation?”. Answering “no” to avoid penalizing a hearing aid user sends a false negative signal to the model regarding detection accuracy.
- Effective: Separating these into two distinct questions (detection vs. violation) yields more granular, higher-quality data without compromising fairness.
-
Writing Tutor (LLM):
- Ineffective (Overwhelming): An LLM providing 400 lines of general feedback, praise, and unsolicited rewrites for a short paragraph. The feedback was untargeted, hard to parse, and unnatural.
- Effective (Delightful): A Duolingo-style interface with direct text markup (green for good, yellow for awkward, red for mistakes). On-hover feedback is concise, actionable, and tied directly to specific text portions, mimicking natural academic feedback and enabling incremental improvement.
-
Coding Agent:
- Ineffective (Rubber Stamp): Agents that produce massive diffs for review or constantly ping for trivial approvals. Both scenarios turn the developer into a “rubber stamp,” deferring debugging to post-approval.
- Effective (Junior Developer Partner): An agent that plans, asks clarifying questions, documents design decisions, provides specs, and breaks tasks into manageable, reviewable PRs. This encourages genuine partnership, allows for highlighting assumptions, and provides richer, structured data on development choices rather than just binary “accepted/rejected” signals.
Design Principles for Discernment
-
Engineer the Reasoning:
- Treat the human as an investigator, not just a validator.
- Surface assumptions early for sign-off to prevent future miscommunication.
- Weigh tradeoffs by presenting options with clear reasoning, keeping the user in control.
- Build in friction where stakes are high to encourage slow, deliberate thought.
-
Match Friction to Stakes:
- High-stakes systems (e.g., DET): Introduce review gates and friction points to ensure thoughtful decision-making and high-quality output.
- Low-stakes systems (e.g., chat AI): Optimize for frictionless, seamless interactions to enhance user delight.
-
Every Interaction is Already a Label:
- Approved plans or accepted suggestions signal alignment.
- Modified or overridden outputs indicate AI shortcomings. Critically, capture the diff between AI output and human correction; failing to do so logs a false positive signal.
- Human questions or requests for explanations indicate low trust or AI issues, providing valuable feedback.
-
Proactively Define Success:
- Instead of evaluating the model post-hoc, define success metrics and the necessary data for improvement from the outset. This informs interaction design to ensure collection of hard evidence for future iterations.
- Interactions should actively teach users how to improve the system, fostering a partnership with the AI.
Conclusion
The speaker concludes that designing for discernment is paramount. Often, the solution for improving human-AI systems isn’t a better model or increased human oversight, but rather deliberate engineering of the human-AI interaction itself. This includes using structured inputs/outputs, proactively highlighting assumptions, building in friction and review gates, and collecting explicit, nuanced feedback to drive continuous improvement.