What Is Jev? The AI Model That Doesn't Generate Text
Jev is a System 1 AI model from TypeSafe that skips text generation entirely, returning calibrated probabilities for fixed-option questions in a single fast request. This explores how it works, how it is trained with reinforcement learning for calibrated decisions, how its probabilities drive software thresholds and guardrails, and how it can complement LLMs in workflows.
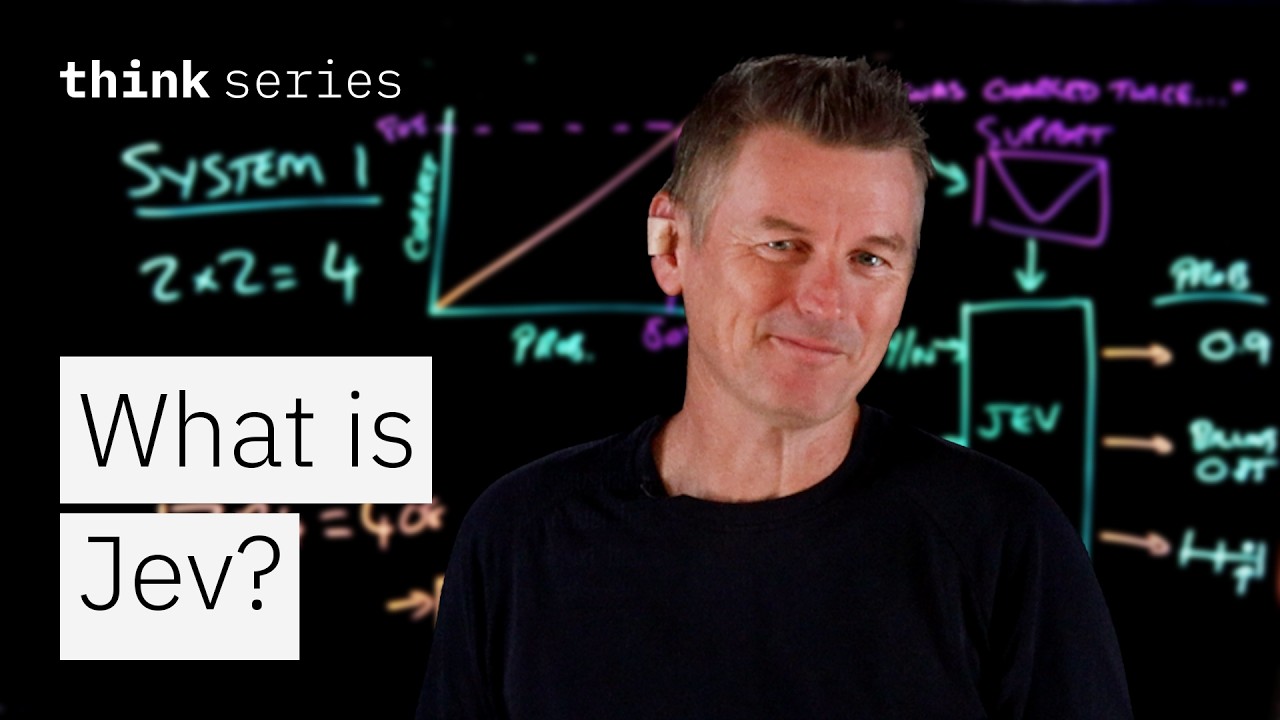
System 1 thinking meets AI models
Jev is a new AI model from the startup TypeSafe that does not write text. Instead of generating an answer token by token, it selects from a predefined set of options and returns a probability for each one. Its name draws on Daniel Kahneman’s distinction between System 1 thinking, which is fast, automatic, and intuitive (knowing that two times two is four), and System 2 thinking, which is slow and deliberate (working through 17 times 24). Chatbots are built to write, and reasoning models come closer to System 2 by writing out a chain of thought. Yet many decisions inside software are quick judgment calls, and that is the work Jev targets.
A worked example: triaging a support email
Consider an email from customer support saying a customer was charged twice this month and asking for a fix. The software handling it needs to answer several questions: is this a refund request (yes or no), which team should process it (billing, technical support, or sales), and how urgent is it (on a scale from low to critical). A person skimming the email would answer the refund question almost instantly.
The usual approach is to hand the email to an LLM and ask for structured output, often JSON. This generally works, but the model gives no reliable signal of its own confidence. Asking the model how sure it is doesn’t solve the problem, since its self-reported confidence need not match the probabilities that actually produced its answer.
Jev takes two kinds of input: the state, meaning the data the decision concerns (the email and recent customer charges), and the questions themselves. The questions have different types. Refund is a binary yes/no question, team is a categorical choice among fixed options, and urgency is an ordinal score. All three go in a single request, and all three answers come back at once as probabilities. For refund, that’s a single number, such as 0.9, meaning a 90% chance this is a refund request. For team, each option gets its own probability, such as 0.85 for billing. Answers are constrained to the listed options. Jev can still be wrong, but the probability expresses how likely that is. Because it generates no text and returns everything in parallel, it is much faster and cheaper than an LLM for this kind of question.
Training for calibration
Standard LLM training begins with pre-training, where the model learns to predict the next token from huge amounts of text, followed by post-training to make it useful as a chatbot. Post-training often relies on reinforcement learning. RLHF uses human raters who pick preferred responses to train a reward model. Its side effect is that models learn to sound confident even when they are wrong, because people tend to like confident answers. RLVR instead uses automatically verifiable rewards, such as whether a math answer is correct or code passes its unit tests, and this is a big part of why reasoning models have become strong at math and coding. However, RLVR only rewards the correct final answer. It doesn’t reward the model for knowing how sure it should be, and long chains of thought make these models slow and expensive to run.
Jev is trained with RLCD, reinforcement learning for calibrated decisions. The model outputs a probability for each option and is rewarded when those probabilities prove accurate. Calibration means stated probabilities match observed frequencies. Among cases where the model says 80%, about 80% should turn out to be correct, which would appear as a diagonal line when predicted probability is plotted against actual correctness. TypeSafe has published little about Jev’s architecture, so what is known comes from what the company has said.
Turning probabilities into software decisions
Calibrated probabilities can drive code through thresholds. In the refund example, a score above roughly 0.9 can be treated as a legitimate refund request and sent straight to the refund queue. Scores in a middle band signal uncertainty, so a human should review the email. Scores below about 0.1 can be dismissed as not a refund request. The thresholds also indicate how often the automatic path will be wrong, so the more a mistake costs, the higher the threshold should be set.
Beyond support email, Jev can serve as an AI guardrail around chatbots, screening incoming and outgoing messages for things like jailbreak attempts.
Limits and how it fits with LLMs
Jev currently accepts only text input, is not good at math or even counting, and, like any AI model, can be tricked by instructions hidden in the data it reads. It is therefore not a replacement for LLMs. The two complement each other in a workflow. Jev makes quick classification calls, such as deciding whether the support email is a refund request. An LLM handles slower work like drafting a reply to the customer, and Jev can then classify the customer’s response. This mirrors Kahneman’s point that most of what we do runs on fast, automatic processes, with slow, careful reasoning called in only when something needs real thought.
Jevons paradox
The name also nods to William Stanley Jevons, who observed in 1865 that as steam engines became more efficient, Britain actually used more coal. This is known as Jevons paradox. The same could happen with System 1 models. When judgment calls become super fast and super cheap, they could be applied in places where an LLM would be too slow or too expensive today, such as to every row of a database or every line of a log file.