912: In Case You Missed It in July 2025 — with Jon Krohn (@JonKrohnLearns)
A review of five key interviews covering the importance of data-centric AI (DMLR) in specialized fields like law, the challenges of AI benchmarking, strategies for domain-specific model selection using red teaming, the power of AI in predicting human behavior, and the shift towards building causal AI models.
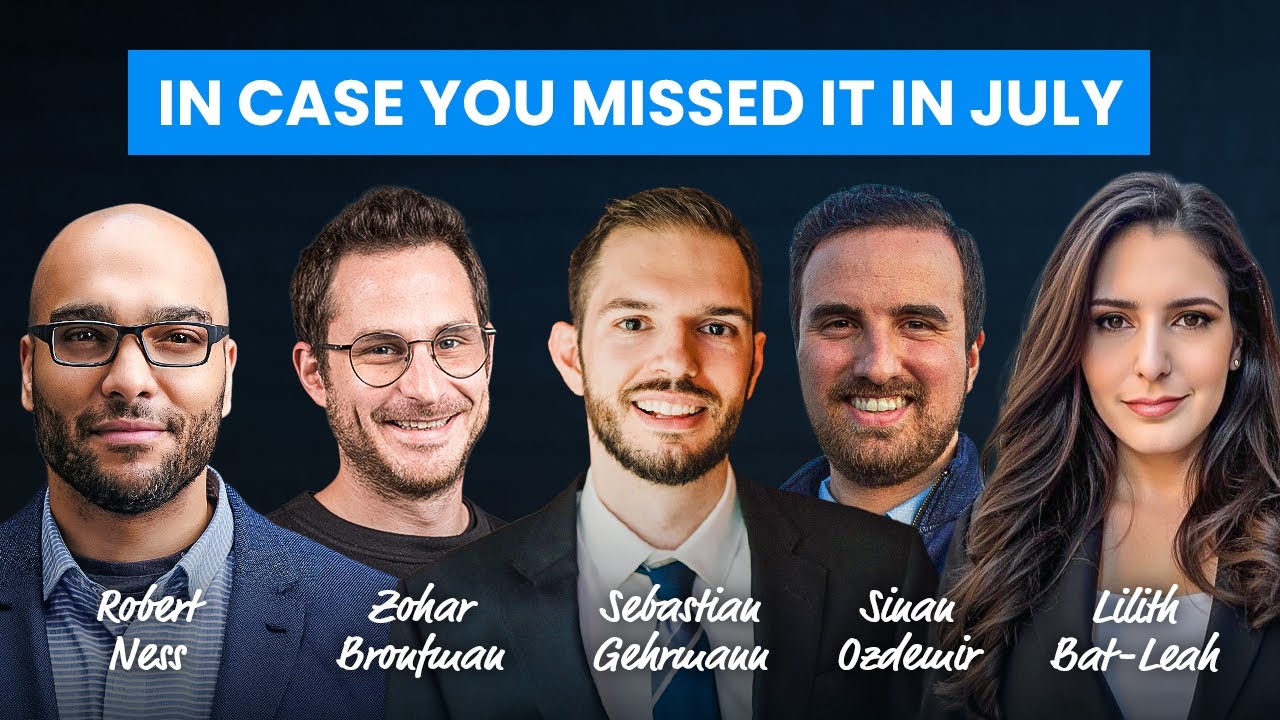
This episode provides a look back at key conversations from the SuperDataScience podcast, synthesizing insights from experts across the AI and machine learning landscape. The discussion spans the critical shift to data-centric AI, the challenges in evaluating large models, the necessity of domain-specific risk management, the predictability of human behavior, and the frontier of causal AI.
From Model-Centric to Data-Centric AI
Lilith Bat-Leah discusses the rise of Data-Centric Machine Learning Research (DMLR), a paradigm shift born from practical necessity. Working in legal tech, she found that the noise and mislabeling in the data were a greater barrier to performance than the choice of algorithm. This led to her involvement with the Data-Centric AI movement, a term coined by Andrew Ng.
The core principle of data-centric AI is to hold the model fixed while systematically iterating on and engineering the data to improve quality. This contrasts with the traditional approach of iterating on model architecture. This movement has gained significant traction, leading to the formation of the DataPerf working group at ML Commons (now the DMLR working group) and workshops at top-tier conferences like ICLR, ICML, and NeurIPS. The group is actively working on projects like creating low-resource language datasets in partnership with Common Crawl. Examples of data-centric techniques include:
- Strategically deciding whether to aggregate labels.
- Weighting different data domains during pre-training, as explored in the “DoReMi” paper.
- A priori selection of the most valuable data points for labeling, using linear algebra to identify them before training even begins.
The Challenge of Evaluating AI: Benchmarks and Beyond
Sinan Ozdemir delves into the inherent limitations of AI benchmarks. A primary issue is contamination, where models are effectively trained on benchmark questions and answers that are publicly available. This makes it difficult to assess a model’s true capabilities.
While a Kaggle-style hidden test set is a potential solution, it raises questions of ownership and centralization. A more novel approach is the Chatbot Arena, where humans perform blind A/B tests on model outputs. However, Ozdemir points out several flaws in this method:
- It tends to reward user preference and conversational style (sycophancy) rather than factual correctness or knowledge.
- The judging process is a “black box,” and it’s unclear what criteria are used for evaluation.
- It is still susceptible to being gamed, with allegations that some models are specifically tuned to perform well in the arena format.
The fundamental question remains: who has the right to judge an AI’s correctness? Benchmarks are our current, imperfect proxy for answering this.
Selecting Models for Regulated, Knowledge-Intensive Domains
Dr. Sebastian Gehrmann extends the evaluation conversation, focusing on the risks of using general-purpose foundation models in specialized fields like finance, healthcare, or law. He argues that these models, and their associated safety systems (e.g., Llama Guard), are not trained on domain-specific corpora. This creates two problems:
- They lack the helpfulness to handle complex, domain-specific tasks.
- Their harmlessness filters are not attuned to domain-specific risks, such as inadvertently providing regulated financial advice.
Gehrmann’s primary recommendation is to “evaluate the system in the context that it’s deployed in.” For organizations in regulated industries, this involves:
- Adapting Risk Taxonomies: Start with general frameworks from NIST or ML Commons and customize them for your specific domain and regulatory obligations.
- Organizing Red Teaming: Conduct structured events where users actively try to break the system in domain-relevant ways. This helps quantify the “risk surface.”
- Investing in Evaluation: Do not simply trust benchmark scores provided by model vendors. Rigorous, context-aware testing is the only way to build a trustworthy and reliable system.
AI, Neuroscience, and Predicting Human Behavior
Dr. Zohar Bronfman explores the intersection of neuroscience and AI, highlighting research that shows human decisions are often predetermined by subconscious neural processes. Experiments demonstrate that the neural basis for a decision can be detected hundreds of milliseconds before a person is consciously aware of making it.
This implies that much of human behavior is predetermined by factors outside our immediate conscious control. For businesses, this is a powerful concept. By analyzing a customer’s historical data, AI can predict future behaviors—such as purchases, churn, or lifetime value—with remarkable accuracy. This predictive capability is a significant lever for optimizing customer experiences and business processes. Bronfman’s mission is to democratize this technology, making it accessible to small and mid-size businesses to help them understand what their customers will do before they do.
The Next Frontier: Building Causal AI
Dr. Robert Ness explains how to move beyond standard correlation-based machine learning to Causal AI. While traditional models are excellent at finding patterns, they cannot distinguish correlation from causation. For example, does playing more side quests cause a gamer to spend more money, or is there a confounding variable, like being in a guild, that causes both?
Building causal models requires a more deliberate approach that separates the causal assumptions from the statistical inference. The goal is to focus on modeling the domain while letting libraries handle the complex computation. Dr. Ness highlights several tools for this:
- Probabilistic Programming Languages (PPLs): Libraries like Pyro (for PyTorch) and Stan allow you to specify a model’s structure and assumptions, and they handle the underlying inference.
- Differentiable Loss Functions in PyTorch: By encoding causal assumptions into a differentiable loss function, you can leverage PyTorch’s powerful optimization capabilities for inference.
- Specialized Causal Libraries: The DoWhy library (part of the PyWhy suite) is designed specifically for causal inference. It allows a practitioner to state their assumptions and then toggle between different statistical techniques (e.g., propensity scores, double machine learning) to estimate a causal effect and check for the stability of the results.