Tokenless

Interactive discovery

Explore the topic map

Follow the connections between themes, people, and ideas across the Tokenless archive in an interactive topic modeling map.

Machine Learning

View All
Judge a Transaction by the Company It Keeps — Somya Rai & MD Sharique, EXL

Judge a Transaction by the Company It Keeps — Somya Rai & MD Sharique, EXL

EXL developed an advanced fraud detection system that augments XGBoost with Graph Neural Network (GNN) embeddings. Traditional tabular models struggle to capture fraud signals residing in transaction neighborhoods. The system's innovative design includes meticulous sampling strategies, disjoint monthly graph construction for leakage control, and a GraphSAGE architecture that aggregates mean, max, and standard deviation of neighbor features to detect subtle fraud patterns. Emphasizing explainability for regulatory compliance and analyst trust, it also features a highly optimized serving architecture achieving 3ms P99 latency, pivoting to edge prediction to reduce cache footprint from 60GB to 2-3GB. This led to a 27-33% relative lift in true positive rates and a projected $65 million incremental fraud capture.
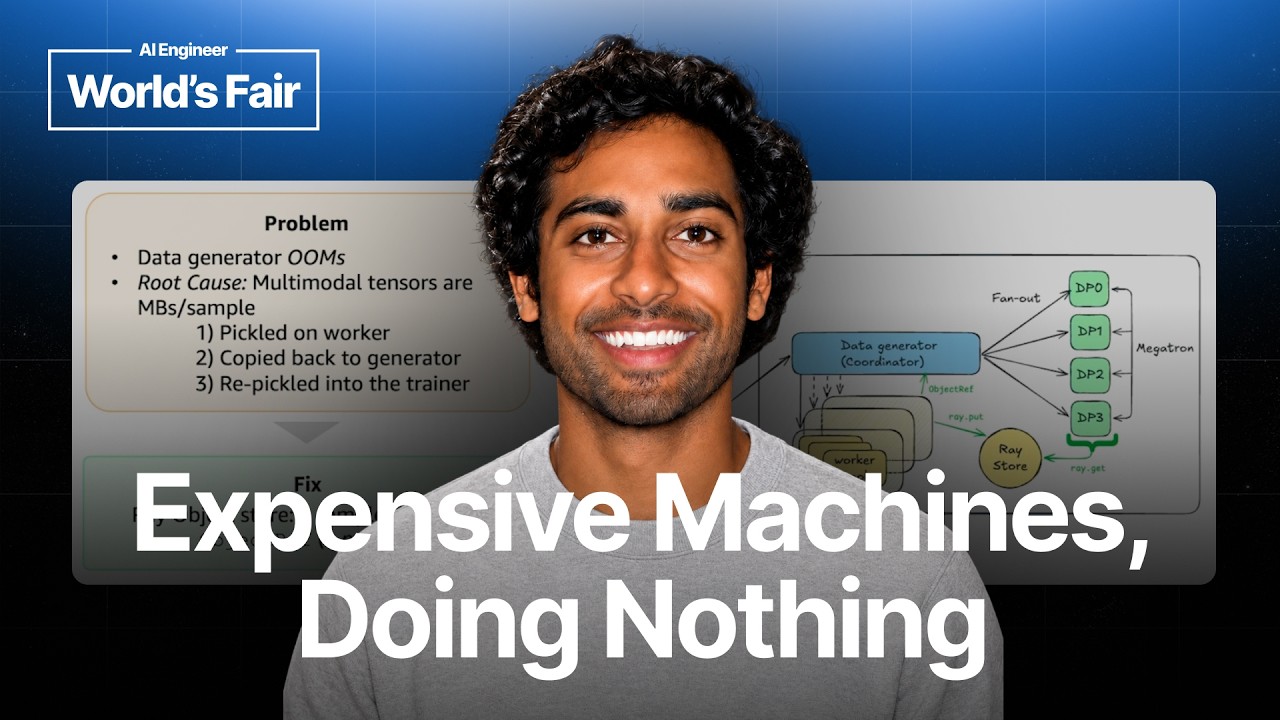
From 15% to 90% GPU Utilization: Fix the Data Pipeline, Not the Model

From 15% to 90% GPU Utilization: Fix the Data Pipeline, Not the Model

Tarun Sunkaraneni from Amazon AGI shows how a multimodal SFT pipeline that spent about 85% of its time waiting on data was brought to roughly 90% GPU utilization. He walks through concurrency with asyncio and Ray actors, prefetching, zero-copy transfer via Ray's object store, and a network-card bottleneck that appears only at scale, and argues that the hardest part of training throughput is often keeping GPUs fed rather than optimizing the model.

Small Models, Big Results: Training a Finance Agent for Under $500 — Charles Dickens, Snorkel AI

Small Models, Big Results: Training a Finance Agent for Under $500 — Charles Dickens, Snorkel AI

Snorkel AI and UC Berkeley's Sky Computing Lab show that a 4B Qwen3 model, trained with reinforcement learning for under $500 using the rLLM framework, beats its 235B sibling on expert-validated financial question answering built from SEC 10-K filings. The talk covers the FinQA dataset construction and verification, common failure modes of frontier models, transfer to multi-table and general tool-use tasks, and ablations showing that simple data and binary rewards outperform more elaborate setups, since the real bottleneck is disciplined tool use rather than reasoning depth.

Artificial Intelligence

View All
AI exposes a major web security flaw, plus a new kind of voice model

AI exposes a major web security flaw, plus a new kind of voice model

This week's panel examines a critical PHP vulnerability that AI tools are surfacing faster than organizations can patch, a voice model from Block that listens and speaks simultaneously, and a cultural riddle benchmark that exposes how evaluation rewards guessing over admitting uncertainty. The episode closes with an IBM TechXchange report on streaming data architecture for AI agents.

Why AI Won't Replace Stock Pickers - Jack Woodruff, Candlestick & Vinoo Ganesh, Kepler

Why AI Won't Replace Stock Pickers - Jack Woodruff, Candlestick & Vinoo Ganesh, Kepler

Jack Woodruff, founder and former CIO of Candlestick Capital and former Citadel portfolio manager, talks with Kepler CEO Vinoo Ganesh about what AI actually changes in fundamental investing. The conversation covers why humans remain the bottleneck, how AI compresses hours of prep into minutes and raises the baseline for analysts, why auditability matters more than speed, where edge comes from when every fund has the same tools, how fund teams may be restructured, and why a no-analyst hedge fund is unlikely to beat the best human-led funds.

The Cheaper AI Model That Costs You More - Rayan Krishnan, Vals AI

The Cheaper AI Model That Costs You More - Rayan Krishnan, Vals AI

Rayan Krishnan of Vals AI explains why single benchmark scores in model cards hide a jagged frontier, using finance tasks like tax and Excel LBO modeling to show that the best model changes by task and that cheaper models can cost more. He covers benchmark design lessons (accuracy metrics, validity, reliability, reward hacking, multi-turn work), a case study in which a team cut token spend about 90% using internal evals built from its own GitHub history, and why a firm's own work history is its most valuable eval source.

Technology

View All
Why Founders Are Betting Big on Factories, Mines, and Energy

Why Founders Are Betting Big on Factories, Mines, and Energy

Erin Price-Wright and Connor Love unpack the AD50 and the rebuilding of America's industrial base, covering how defense demand is financing manufacturing capacity for commercial markets, how AI is reshaping factory economics, how a new generation of founders applies lessons from SpaceX, Tesla, Anduril, and Palantir to mining, energy, and manufacturing, and why private capital is now willing to fund physical infrastructure before government demand is guaranteed.

Mark Cuban’s Plan to Make Healthcare Affordable

Mark Cuban’s Plan to Make Healthcare Affordable

Mark Cuban and Julie Yoo discuss how transparency, direct contracting, and AI could reshape healthcare economics, from Cost Plus Drugs and modular pod manufacturing to personalized medicine, the future of physicians, and advice for founders who want to use AI to learn rather than to stop thinking.

Exploits Now Beat Patches: Open Source Security in the AI Era - Patrick Smyth, Chainguard

Exploits Now Beat Patches: Open Source Security in the AI Era - Patrick Smyth, Chainguard

Patrick Smyth of Chainguard examines how frontier AI has compressed the time between vulnerability disclosure and exploitation, leaving 30-day remediation cycles obsolete. The talk covers AI-assisted attacks, waves of supply chain malware, four attack surfaces spanning malware, known CVEs, zero days, and side doors like CI/CD, developer laptops, and agent skills, and practical defenses including cooldown periods, faster CVE remediation, and signing artifacts with SLSA and Sigstore.


Recent Post

MCP Tasks (async): Why Aren't Any Agents Supporting Them? — Cornelia Davis, Temporal

MCP Tasks (async): Why Aren't Any Agents Supporting Them? — Cornelia Davis, Temporal

Cornelia Davis explains why the MCP tasks specification, designed for durable, long-running, and interactive operations, hasn't seen widespread adoption. She details V1's architectural flaws, particularly concerning scalability and stateful human-in-the-loop interactions, and introduces V2's shift to a stateless core, client-initiated updates, and a clearer path for client-side durability, while outlining future work on scaling and adoption.

When Will The Benchmaxxing Plague End? — Nick Heiner, Surge AI

When Will The Benchmaxxing Plague End? — Nick Heiner, Surge AI

Nick Heiner explores the phenomenon of "benchmaxing" in AI, where models are optimized for benchmark scores rather than real-world utility. He exposes common antipatterns in benchmark creation, such as contamination, reward hacking, and misaligned verifiers, and critiques labs' tactics like gaming leaderboards. Heiner advocates for a higher standard, emphasizing the need for human expertise, high-fidelity data, and rigorous alignment in evaluation to ensure benchmarks genuinely reflect AI's value.

This CPO regrets that product management exists | Tom Verrilli (CPO of Whatnot)

This CPO regrets that product management exists | Tom Verrilli (CPO of Whatnot)

Tom Verrilli, CPO at Whatnot, discusses his controversial stance that "we regret product management exists," advocating for a leaner, more hands-on PM approach. He delves into how Whatnot structures its product team, its rigorous hiring process focused on deep systems thinking and IC work, and the transformative impact of AI on product and data science functions. Verrilli also shares mental models for balancing strategy and iteration, navigating the CPO-founder relationship, and key lessons from his time at Twitter, emphasizing the importance of core PM skills in an AI-driven world.

Understanding AI Agent Hallucination in AI Systems

Understanding AI Agent Hallucination in AI Systems

Learn about AI hallucinations, why they occur in autonomous agents, and how they pose new risks as AI takes action. Discover key mitigation strategies including data grounding, tool-based reasoning, scope control, and human-in-the-loop interventions to ensure reliable AI performance.

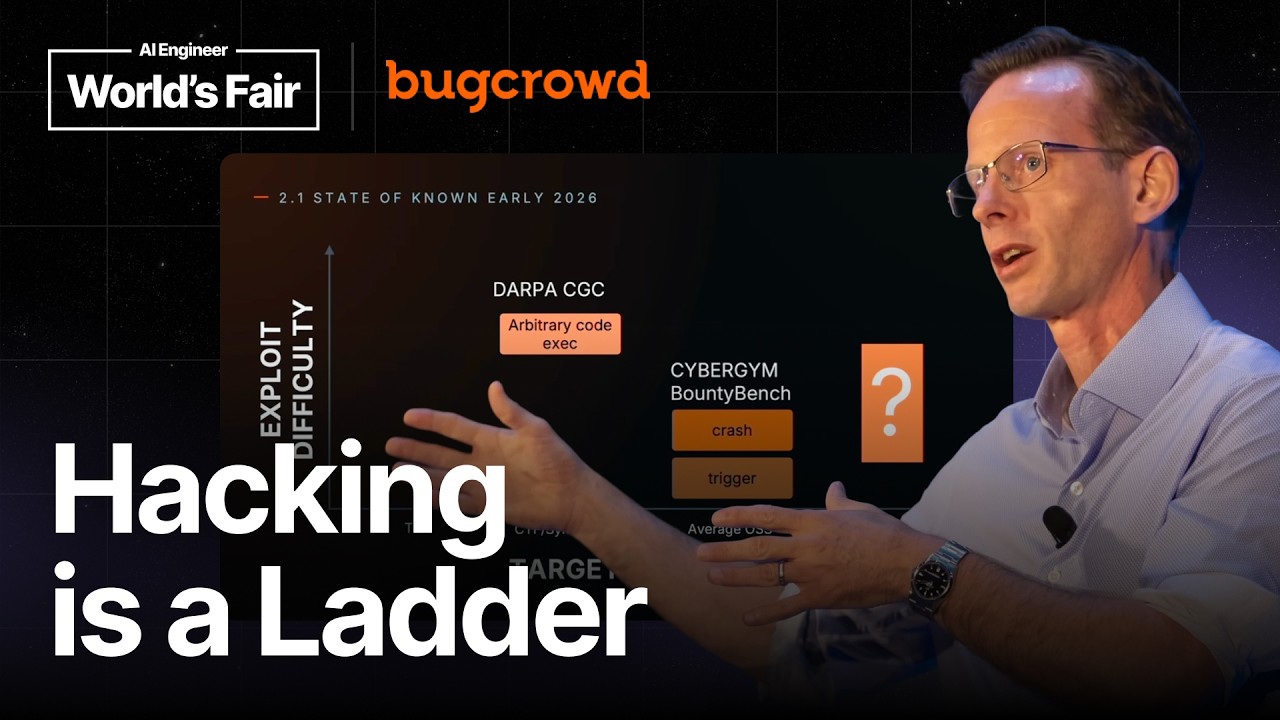
Teaching AI to Find Real Vulnerabilities — David Brumley, Bugcrowd

Teaching AI to Find Real Vulnerabilities — David Brumley, Bugcrowd

David Brumley discusses the challenges and solutions for teaching AI models to hack, drawing parallels with human learning. He introduces a 'ladder of tasks' approach for reinforcement learning and addresses the critical flaw of traditional benchmarks: measurement difficulties with multiple vulnerabilities and 'reward hacking.' His team's 'Audit Task' uses deterministic graders and precision/recall metrics for open-world assessment. He demonstrates this with an in-depth case study on attacking Chrome's V8 engine, showcasing how advanced models achieve real zero-day exploits, and warns against 'benchmaxxing security' without robust, honest grading.

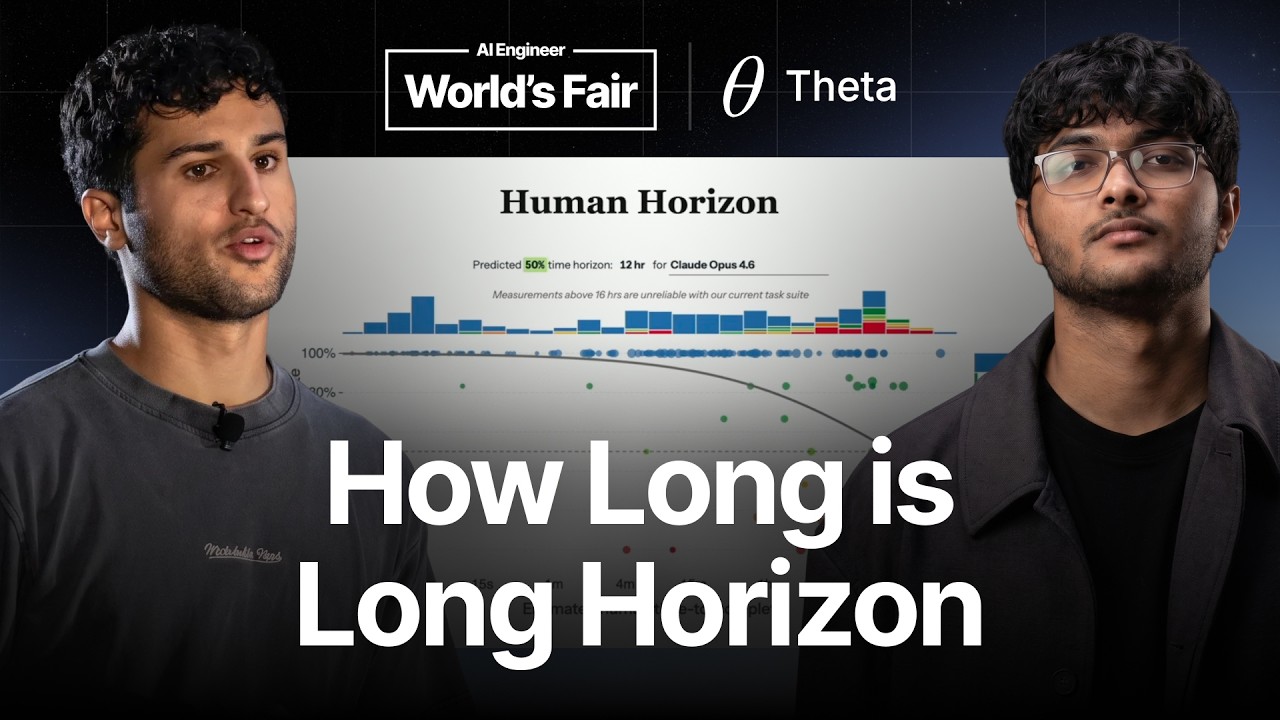
Rethinking Environments for Long-Horizon Work — Rayan Garg, Theta Software

Rethinking Environments for Long-Horizon Work — Rayan Garg, Theta Software

Rayan Garg from Theta Software delves into the complexities of defining and evaluating "long horizon" tasks for AI agents. He critiques current metrics and benchmarks, emphasizing the critical role of sophisticated environment design and robust verifiers (judge models) in driving true progress, particularly in "software-failing domains." The discussion highlights issues like task ambiguity, state changes, and the necessity for granular reward signals for effective model training.

Stay In The Loop! Subscribe to Our Newsletter.

Get updates straight to your inbox. No spam, just useful content.