Tokenless

Interactive discovery

Explore the topic map

Follow the connections between themes, people, and ideas across the Tokenless archive in an interactive topic modeling map.

Machine Learning

View All
Judge a Transaction by the Company It Keeps — Somya Rai & MD Sharique, EXL

Judge a Transaction by the Company It Keeps — Somya Rai & MD Sharique, EXL

EXL developed an advanced fraud detection system that augments XGBoost with Graph Neural Network (GNN) embeddings. Traditional tabular models struggle to capture fraud signals residing in transaction neighborhoods. The system's innovative design includes meticulous sampling strategies, disjoint monthly graph construction for leakage control, and a GraphSAGE architecture that aggregates mean, max, and standard deviation of neighbor features to detect subtle fraud patterns. Emphasizing explainability for regulatory compliance and analyst trust, it also features a highly optimized serving architecture achieving 3ms P99 latency, pivoting to edge prediction to reduce cache footprint from 60GB to 2-3GB. This led to a 27-33% relative lift in true positive rates and a projected $65 million incremental fraud capture.
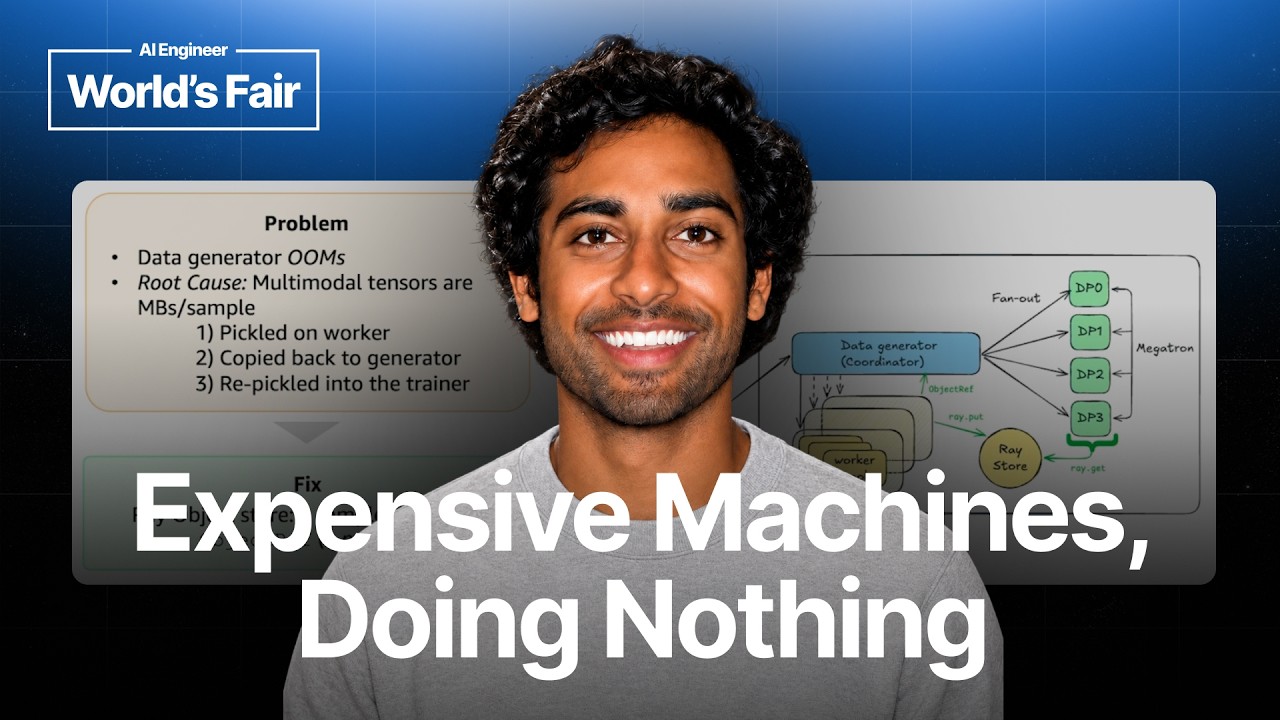
From 15% to 90% GPU Utilization: Fix the Data Pipeline, Not the Model

From 15% to 90% GPU Utilization: Fix the Data Pipeline, Not the Model

Tarun Sunkaraneni from Amazon AGI shows how a multimodal SFT pipeline that spent about 85% of its time waiting on data was brought to roughly 90% GPU utilization. He walks through concurrency with asyncio and Ray actors, prefetching, zero-copy transfer via Ray's object store, and a network-card bottleneck that appears only at scale, and argues that the hardest part of training throughput is often keeping GPUs fed rather than optimizing the model.

Small Models, Big Results: Training a Finance Agent for Under $500 — Charles Dickens, Snorkel AI

Small Models, Big Results: Training a Finance Agent for Under $500 — Charles Dickens, Snorkel AI

Snorkel AI and UC Berkeley's Sky Computing Lab show that a 4B Qwen3 model, trained with reinforcement learning for under $500 using the rLLM framework, beats its 235B sibling on expert-validated financial question answering built from SEC 10-K filings. The talk covers the FinQA dataset construction and verification, common failure modes of frontier models, transfer to multi-table and general tool-use tasks, and ablations showing that simple data and binary rewards outperform more elaborate setups, since the real bottleneck is disciplined tool use rather than reasoning depth.

Artificial Intelligence

View All
If Your AI Scores 100%, Your Eval Is Wrong - Ramakrishnan Lokanathan, eslams.com

If Your AI Scores 100%, Your Eval Is Wrong - Ramakrishnan Lokanathan, eslams.com

Ramakrishnan Lokanathan argues that AI evals are broken because they are overcomplicated, and lays out a practical framework for building them for high-stakes applications: define the most ambitious version of success, test every step of a workflow, combine automated checks with human review and adversarial tests, guard against regressions, and turn real user failures into tests. He also introduces eSlams, an open-source package where models compete in games like chess, Go, and poker as a window into how they reason.

Your AI Agent Wants Your Data. Here's How to Lock It Down - Jeff Smith, Oracle

Your AI Agent Wants Your Data. Here's How to Lock It Down - Jeff Smith, Oracle

Oracle's Jeff Smith explains how to let agents query enterprise databases safely through an MCP server, covering reports exposed as vetted tools, the risks of natural language to SQL, performance tuning on read-only standbys, schema annotations, and deep data security enforced at the database layer.

Everyone Has the Same AI Models. Here's What Sets Agents Apart - Richmond Alake, Oracle

Everyone Has the Same AI Models. Here's What Sets Agents Apart - Richmond Alake, Oracle

Richmond Alake argues that after the control plane, agent architectures need an intelligence plane covering what an agent knows, remembers, is allowed to see, and how it improves. He draws on the WWII Midway codebreaking story to separate information from intelligence, then demos a governed agent using an ontology and semantic layer that answers correctly about 99% of the time with far fewer tokens than a naive agent. The talk also covers Oracle's agent memory package, deep data security, private inference, and fine-tuned decision models for memory routing.

Technology

View All
Why Founders Are Betting Big on Factories, Mines, and Energy

Why Founders Are Betting Big on Factories, Mines, and Energy

Erin Price-Wright and Connor Love unpack the AD50 and the rebuilding of America's industrial base, covering how defense demand is financing manufacturing capacity for commercial markets, how AI is reshaping factory economics, how a new generation of founders applies lessons from SpaceX, Tesla, Anduril, and Palantir to mining, energy, and manufacturing, and why private capital is now willing to fund physical infrastructure before government demand is guaranteed.

Mark Cuban’s Plan to Make Healthcare Affordable

Mark Cuban’s Plan to Make Healthcare Affordable

Mark Cuban and Julie Yoo discuss how transparency, direct contracting, and AI could reshape healthcare economics, from Cost Plus Drugs and modular pod manufacturing to personalized medicine, the future of physicians, and advice for founders who want to use AI to learn rather than to stop thinking.

Exploits Now Beat Patches: Open Source Security in the AI Era - Patrick Smyth, Chainguard

Exploits Now Beat Patches: Open Source Security in the AI Era - Patrick Smyth, Chainguard

Patrick Smyth of Chainguard examines how frontier AI has compressed the time between vulnerability disclosure and exploitation, leaving 30-day remediation cycles obsolete. The talk covers AI-assisted attacks, waves of supply chain malware, four attack surfaces spanning malware, known CVEs, zero days, and side doors like CI/CD, developer laptops, and agent skills, and practical defenses including cooldown periods, faster CVE remediation, and signing artifacts with SLSA and Sigstore.


Recent Post

How a reasoning model cracked an 80-year-old math problem — the OpenAI Podcast Ep. 20

How a reasoning model cracked an 80-year-old math problem — the OpenAI Podcast Ep. 20

OpenAI's reasoning researchers discuss how a general-purpose AI model disproved an 80-year-old conjecture from mathematician Paul Erdős. They detail the journey from initial IMO/IOI breakthroughs to the verification of the proof, highlighting the model's creative application of advanced number theory. The episode explores the profound implications for the future of mathematics, AI-human collaboration, and the broader scientific landscape, offering advice for researchers seeking to leverage AI for groundbreaking discoveries.

The Art & Science of Benchmarking Agents — Vincent Chen, Snorkel AI

The Art & Science of Benchmarking Agents — Vincent Chen, Snorkel AI

Vincent Chen of Snorkel AI discusses the crucial gap between rapidly advancing AI capabilities and our ability to measure them. He presents a framework for building effective benchmarks, encompassing task quality, distributional diversity, model headroom, and robust evaluation methodologies, alongside the "art" of having a clear thesis, inspiring research roadmaps, and prioritizing researcher UX. He concludes by outlining three critical axes for future benchmarks: environment complexity, autonomy horizon, and output complexity, to better reflect real-world AI applications.

SWE-rebench: Lessons from Evaluating Coding Agents — Ibragim Badertdinov, Nebius

SWE-rebench: Lessons from Evaluating Coding Agents — Ibragim Badertdinov, Nebius

Ibragim Badertdinov from Nebius AI shares lessons from building and maintaining SWE-ReBench, a monthly leaderboard that evaluates coding agents on fresh, real-world software engineering tasks. The talk covers the anatomy of a good benchmark task, the challenges of filtering out noisy or flawed problems, and fascinating examples of how advanced models like Claude Code "cheat" by exploiting the environment. Finally, it explains how the same pipeline used for evaluation has produced large-scale, high-quality training datasets like SWE-bench, used by frontier AI labs.

The Rise of the Full-Stack Builder and Hyper-Leveraged Generalist with Microsoft CEO Satya Nadella

The Rise of the Full-Stack Builder and Hyper-Leveraged Generalist with Microsoft CEO Satya Nadella

Microsoft CEO Satya Nadella discusses the future of AI at Microsoft Build, emphasizing an ecosystem approach where every company can create its own "frontier intelligence." He highlights the critical role of private evaluations as a new form of intellectual property, the strategic use of multi-modal harnesses for enterprise, and how autonomous AI agents are reshaping software development and business models. Nadella also shares insights on the societal impact of AI, from data center investments to the potential for AI-driven transformation in education.

Benchmarking semantic code retrieval on Claude Code — Kuba Rogut, Turbopuffer

Benchmarking semantic code retrieval on Claude Code — Kuba Rogut, Turbopuffer

A detailed benchmark analysis comparing raw Claude Code's performance with windowed grep and Turbopuffer's semantic search for code retrieval in LLM agents. The study reveals significant improvements in file precision (65% to 87%) and reduced wasted reads (1 in 3 to 1 in 8) with semantic search, while highlighting the importance of the agent's understanding of when to use retrieval tools.

BDD, ADR, PRD, WTF: Capturing Decisions for Humans and AI Alike — Michal Cichra, Safe Intelligence

BDD, ADR, PRD, WTF: Capturing Decisions for Humans and AI Alike — Michal Cichra, Safe Intelligence

Michal Cichra from Safe Intelligence explains how to maintain consistency in AI-driven software development by capturing decisions and enforcing rules. He argues for reviving Behavior-Driven Development (BDD) with Cucumber to close the loop left by spec-driven development. The core idea is to enforce architectural and product decisions (ADRs, PRDs) through an automated loop of git hooks and CI, ensuring both human and AI developers adhere to established standards.

Stay In The Loop! Subscribe to Our Newsletter.

Get updates straight to your inbox. No spam, just useful content.