Model comparison

The Model Swap Workshop: GPT-5.5 vs Kimi vs DeepSeek vs Mistral

The Model Swap Workshop: GPT-5.5 vs Kimi vs DeepSeek vs Mistral

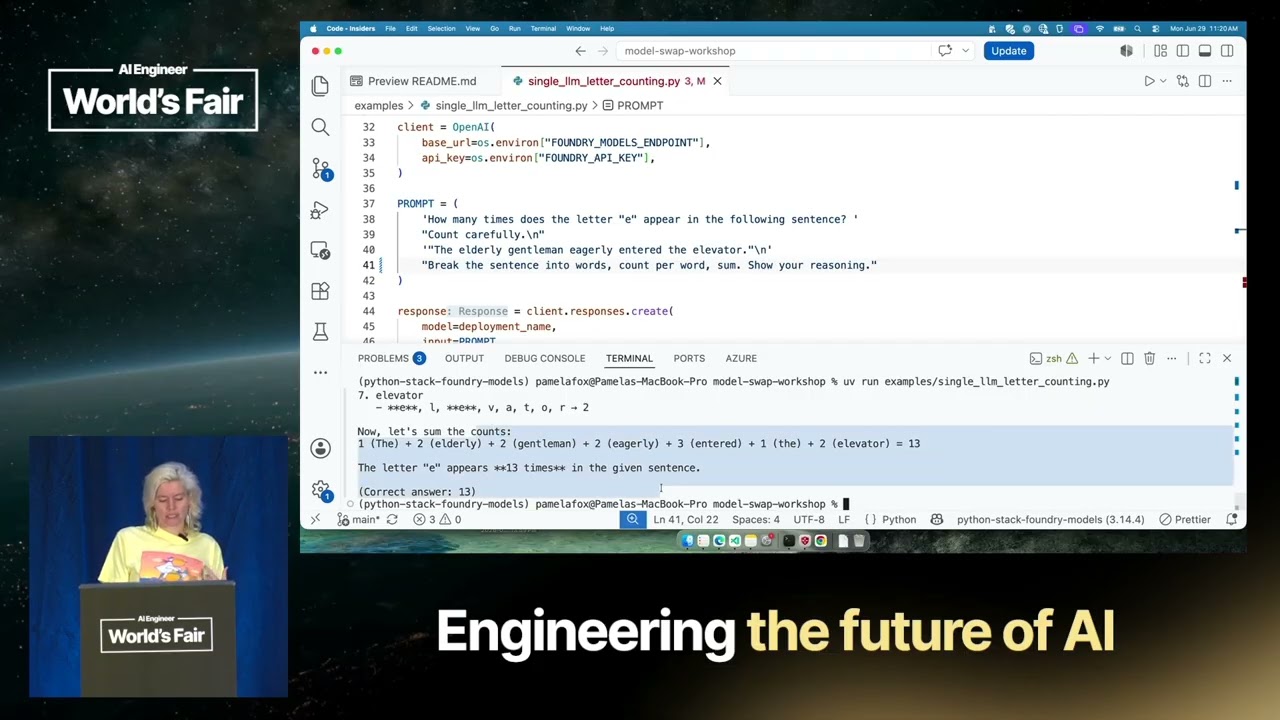
Pamela Fox runs a guided workshop comparing GPT-5.5, Kimi K2.6, DeepSeek V4 Flash, and Mistral Large 3 on Microsoft Foundry, showing that benchmarks cannot predict how a model will behave in a specific application. The talk covers counting, RAG groundedness, vision, multilingual failures, tool calling, parallel tool calls in agents, string-check and LLM-as-a-judge evals, Microsoft's ASSERT tool for generating test sets, and DSPy prompt optimization that lets a cheap model satisfy a spec.
High Taste Testers: OpenAI Shipped Everything. What Actually Works?

High Taste Testers: OpenAI Shipped Everything. What Actually Works?

A roundtable of AI power users reviews OpenAI DevDay and asks what actually works in daily use. Topics include personal assistants and their trust, permission, and safety trade-offs; durable agent state and remote execution; the Jev decision model and calibrated classification; model preferences across Anthropic, OpenAI, xAI, Meta, and open models; subagents and context management; and the gap between impressive capabilities and products that hold up.

Anthropic Claude Opus 4.6 vs OpenAI GPT-5.3-Codex: The AI "big game”

Anthropic Claude Opus 4.6 vs OpenAI GPT-5.3-Codex: The AI "big game”

The release of Anthropic's Claude Opus 4.6 and OpenAI's GPT-5.3-Codex within an hour of each other signals an intensifying "AI Super Bowl." Experts Chris Hay and Mihai Criveti compare the models, discuss the strategic battle for the enterprise market, and reveal their practical, multi-agent workflows that leverage the unique strengths of both.

OpenAI dropped GPT-5, is AGI here?

OpenAI dropped GPT-5, is AGI here?

In this analysis, experts Bryan Casey, Mihai Criveti, and Chris Hay dissect the OpenAI GPT-5 release, comparing its capabilities against Anthropic's Claude Opus 4.1. While GPT-5 introduces significant improvements in accessibility, agentic capabilities, and reliability, the consensus is that it does not yet dethrone Claude as the daily driver for developers due to key differences in user experience and workflow management.