Llms

The AI Employee for Banks

The AI Employee for Banks

Kastle founders Rishi and Nitish discuss their journey building AI employees for banks, from a difficult pivot before YC Demo Day to processing billions in transactions. They share insights into finding product-market fit in a highly regulated industry, ensuring AI reliability and compliance despite non-deterministic LLMs, and their vision for automating financial operations.
Stop Chunking Like It's 2022 — Yuval Belfer, AI21 Labs

Stop Chunking Like It's 2022 — Yuval Belfer, AI21 Labs

Yuval Belfer addresses the fundamental challenge in Retrieval Augmented Generation (RAG): the optimal chunk size is query-dependent, but chunking decisions are fixed during indexing. This "information problem" leads to significant recall loss, as shown by experiments demonstrating a 20-40% gap between fixed chunking and an oracle. His proposed solution, multiscale indexing, involves creating multiple document copies with different chunk sizes, querying all of them, retrieving whole documents, and merging results using Reciprocal Rank Fusion, yielding substantial recall improvements with minimal latency increase.

AI Tech Stack | The Founders and Builders Architecting Product Market Fit | Creator's Cut | 2026 |4K

AI Tech Stack | The Founders and Builders Architecting Product Market Fit | Creator's Cut | 2026 |4K

This panel discussion explores the evolving AI tech stack and its impact on product-market fit, ethical governance, and business transformation. Experts from Humana, Catenate, In-Telecom, and Spacer AI explain how AI-powered prompts are replacing static dashboards, detail multi-model API strategies for cost efficiency, and delve into the critical role of human-in-the-loop oversight for autonomous agents to ensure data security and responsible AI deployment. They emphasize that true value lies in domain expertise and solving real-world pain points, not just building 'shiny toys'.

Realtime Voice Agents with Frontier Intelligence — Bohan Li, EliseAI

Realtime Voice Agents with Frontier Intelligence — Bohan Li, EliseAI

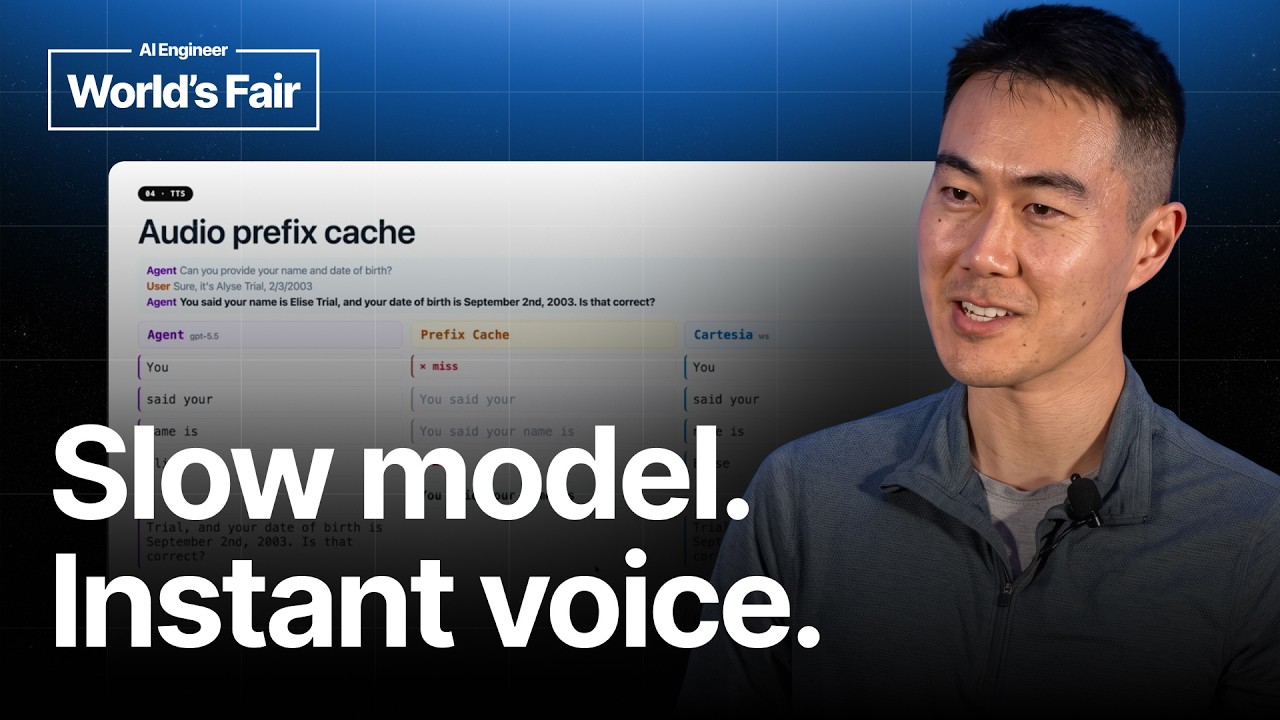
Bohan Li of EliseAI unveils a sophisticated architecture for real-time voice agents that merges high intelligence with low latency, akin to a self-driving car's perception, planning, and control systems. Key innovations include a speculative transcriber combining fast streaming with accurate contextual correction, background agents for offloading LLM tool calls and enabling eager generation, and a clever prefix cache for speech synthesis that seamlessly blends pre-cached audio with dynamically generated speech to mask underlying processing delays.

OpenAI’s GPT-6 Astra (Ep. 1026 with Jon Krohn)

OpenAI’s GPT-6 Astra (Ep. 1026 with Jon Krohn)

Jon Krohn examines OpenAI's GPT-6 Astra, its new flagship model. He delves into its state-of-the-art capabilities across computer use, coding, abstract reasoning, and scientific discovery, including its role in finding zero-day vulnerabilities. Krohn also critically analyzes the AGI claims surrounding Astra, comparing its performance and safety features with competitors like Anthropic's Fable 5.1, offering a balanced perspective on its significance.

Your agents lack context: Here's how to fix "You're absolutely right!" — Brandon Waselnuk, Unblocked

Your agents lack context: Here's how to fix "You're absolutely right!" — Brandon Waselnuk, Unblocked

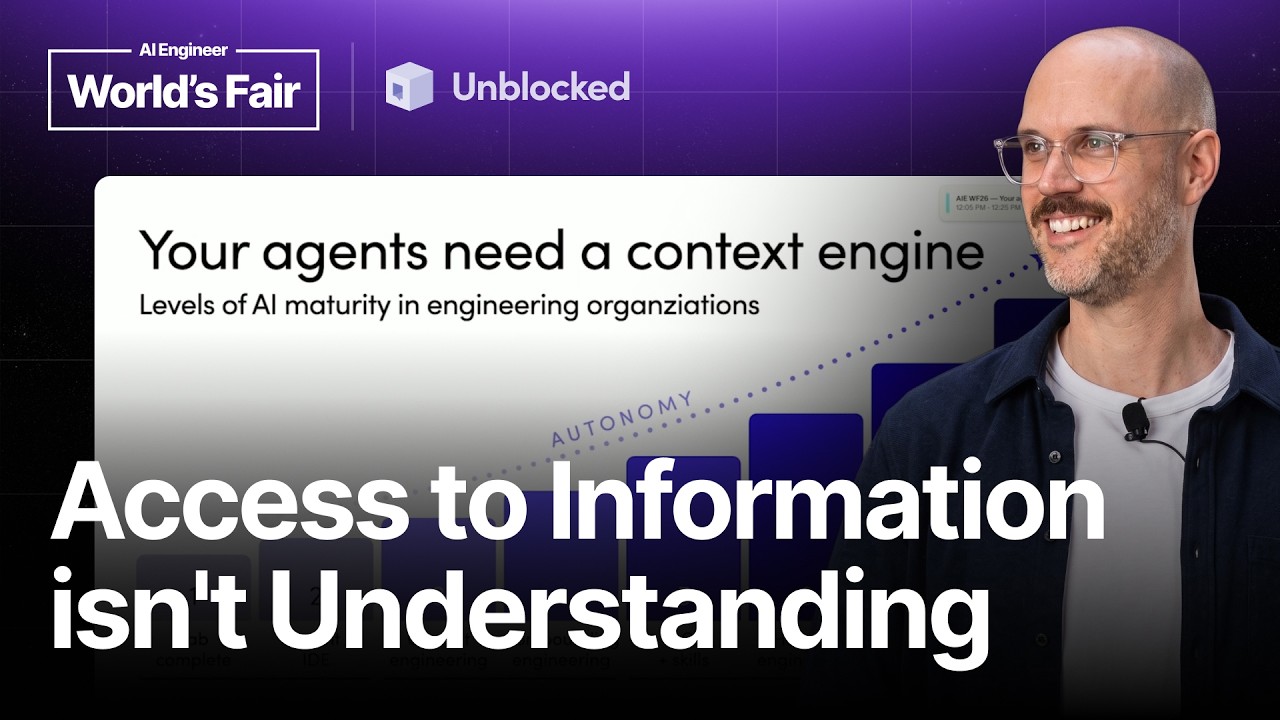
Brandon Waselnuk of Unblocked discusses the critical need for robust context engines in AI-driven software development. He explains how AI agents' lack of company-specific understanding leads to compounding costs like wasted tokens and rework. Waselnuk outlines common pitfalls in providing context and details six essential characteristics of an effective context engine, demonstrating its impact with a 50% token reduction and significant time savings. He also introduces three open-source tools from Unblocked, including a workshop to build a relational context engine, emphasizing that "access to information is not understanding" and that context, not intelligence, is the current bottleneck for AI effectiveness.