Agent benchmarking

How to Build Voice Agents That Don't Fall Apart When You Interrupt - Jesse Hall, LiveKit

How to Build Voice Agents That Don't Fall Apart When You Interrupt - Jesse Hall, LiveKit

Jesse Hall of LiveKit explains how to build voice agents for financial services that feel human rather than robotic. The talk covers why model leaderboards mislead for real-time conversations, why time to first audio and time to first sentence matter more than first byte or first token, and how async tool calls keep a conversation flowing during slow back-end work. It also covers audio-aware turn detection, the roughly 1.5-second latency budget, and benchmarking your own stack with simulated callers.
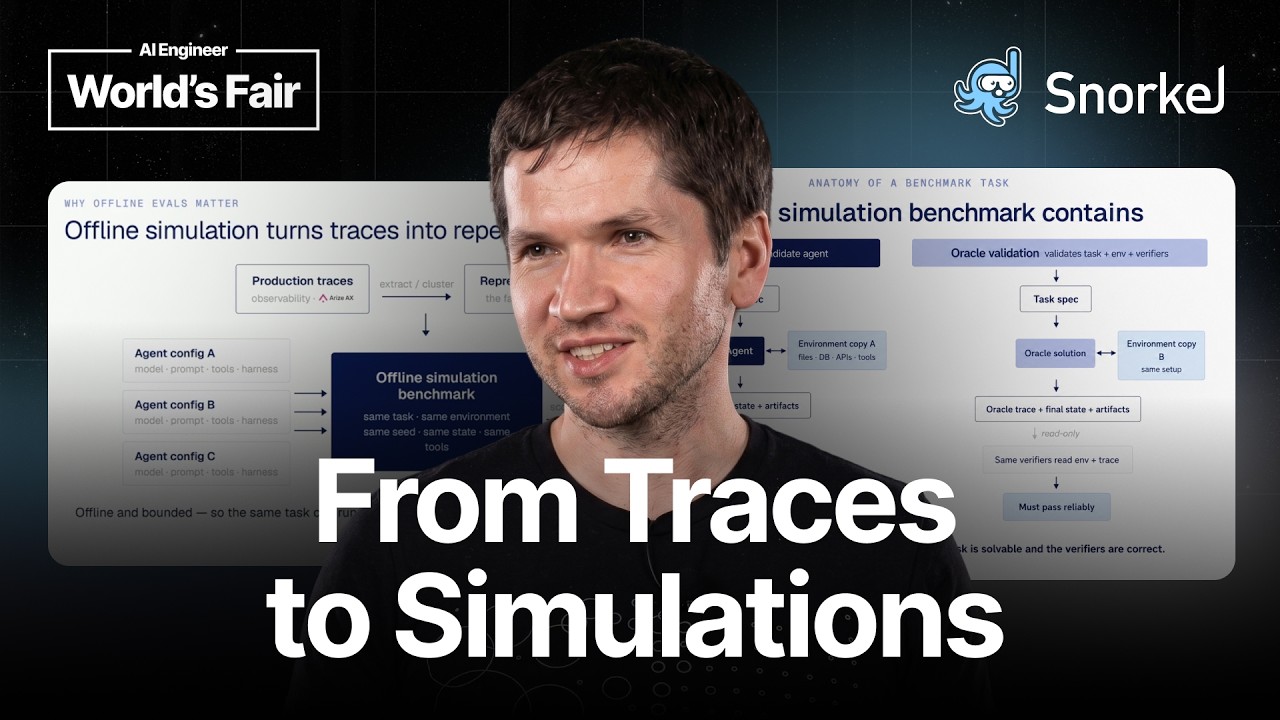
From Agent Traces to Agent Simulations — Rustem Feyzkhanov, Snorkel AI

From Agent Traces to Agent Simulations — Rustem Feyzkhanov, Snorkel AI

Rustem Feyzkhanov discusses the critical need for companies to build private, production-aligned benchmarks for AI agents. He explains how to turn agent traces into repeatable simulations, why public benchmarks are insufficient, and how a CI pipeline for agents, integrating observability and experimentation, can ensure reliable evaluation, continuous improvement, and effective release management, moving beyond simple pass rates to measure cost, latency, and policy adherence.