Understanding AI Agent Hallucination in AI Systems
Learn about AI hallucinations, why they occur in autonomous agents, and how they pose new risks as AI takes action. Discover key mitigation strategies including data grounding, tool-based reasoning, scope control, and human-in-the-loop interventions to ensure reliable AI performance.
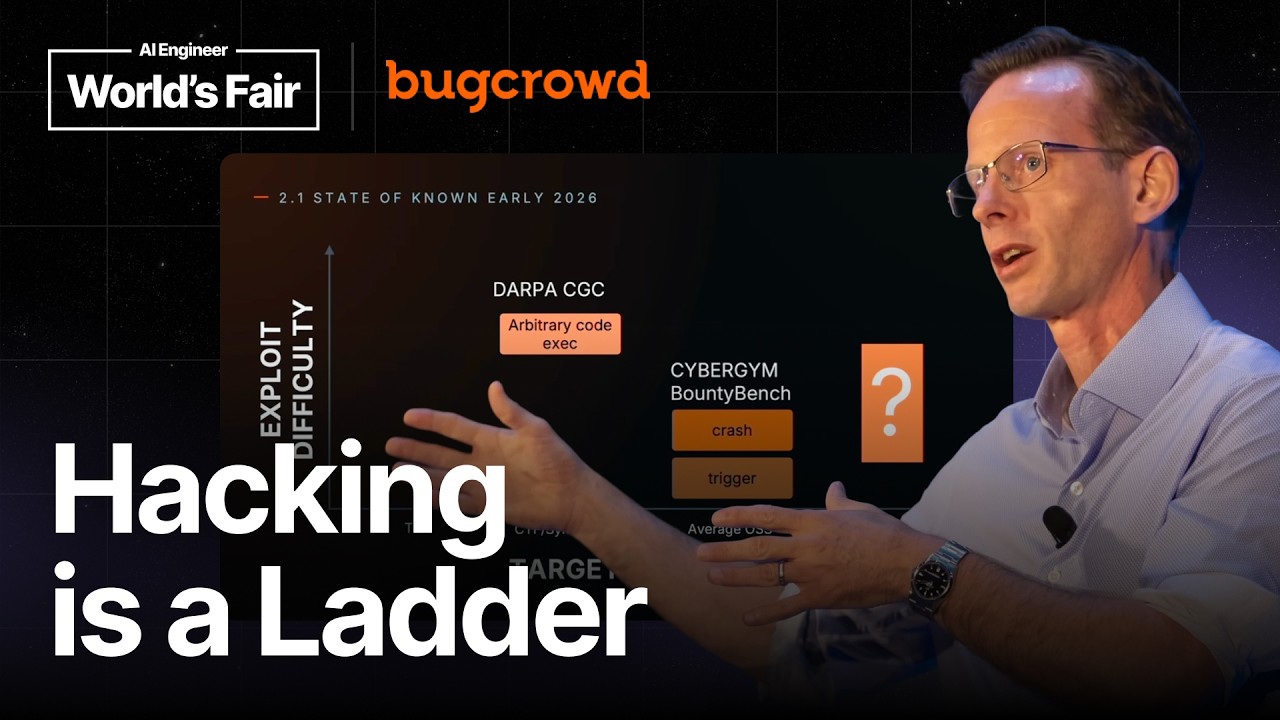
Teaching AI to Find Real Vulnerabilities — David Brumley, Bugcrowd
David Brumley discusses the challenges and solutions for teaching AI models to hack, drawing parallels with human learning. He introduces a 'ladder of tasks' approach for reinforcement learning and addresses the critical flaw of traditional benchmarks: measurement difficulties with multiple vulnerabilities and 'reward hacking.' His team's 'Audit Task' uses deterministic graders and precision/recall metrics for open-world assessment. He demonstrates this with an in-depth case study on attacking Chrome's V8 engine, showcasing how advanced models achieve real zero-day exploits, and warns against 'benchmaxxing security' without robust, honest grading.
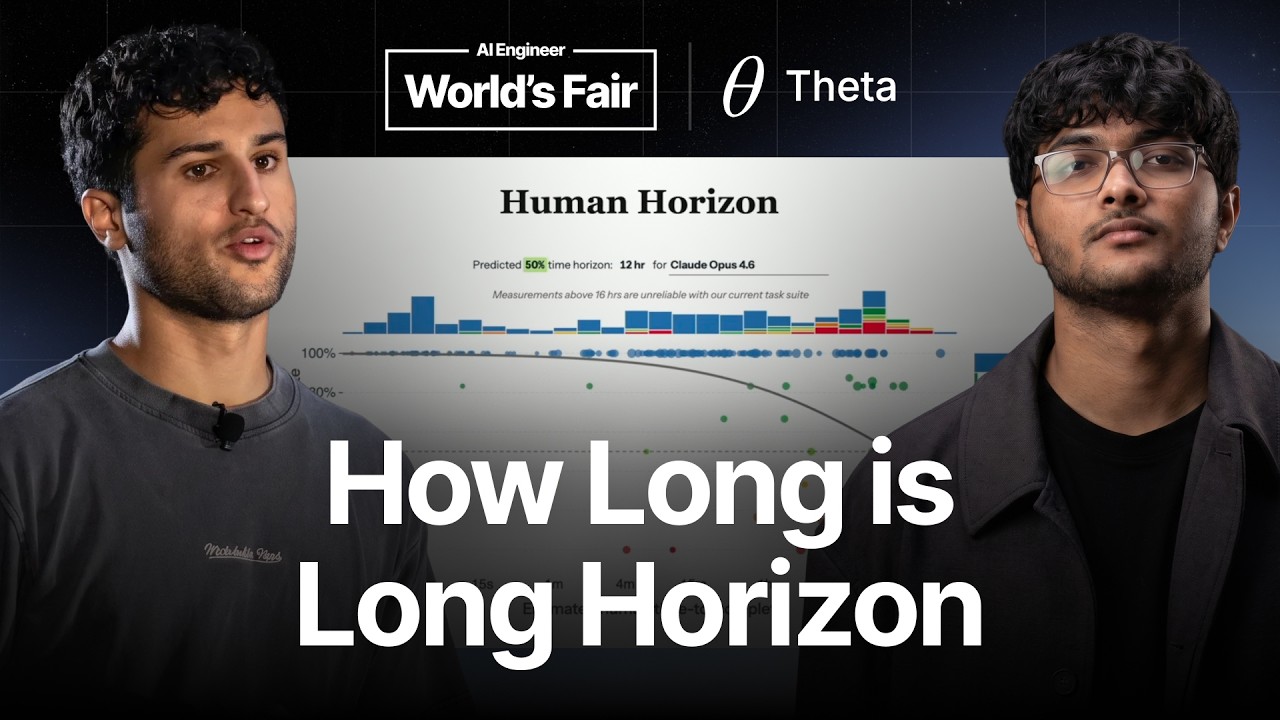
Rethinking Environments for Long-Horizon Work — Rayan Garg, Theta Software
Rayan Garg from Theta Software delves into the complexities of defining and evaluating "long horizon" tasks for AI agents. He critiques current metrics and benchmarks, emphasizing the critical role of sophisticated environment design and robust verifiers (judge models) in driving true progress, particularly in "software-failing domains." The discussion highlights issues like task ambiguity, state changes, and the necessity for granular reward signals for effective model training.
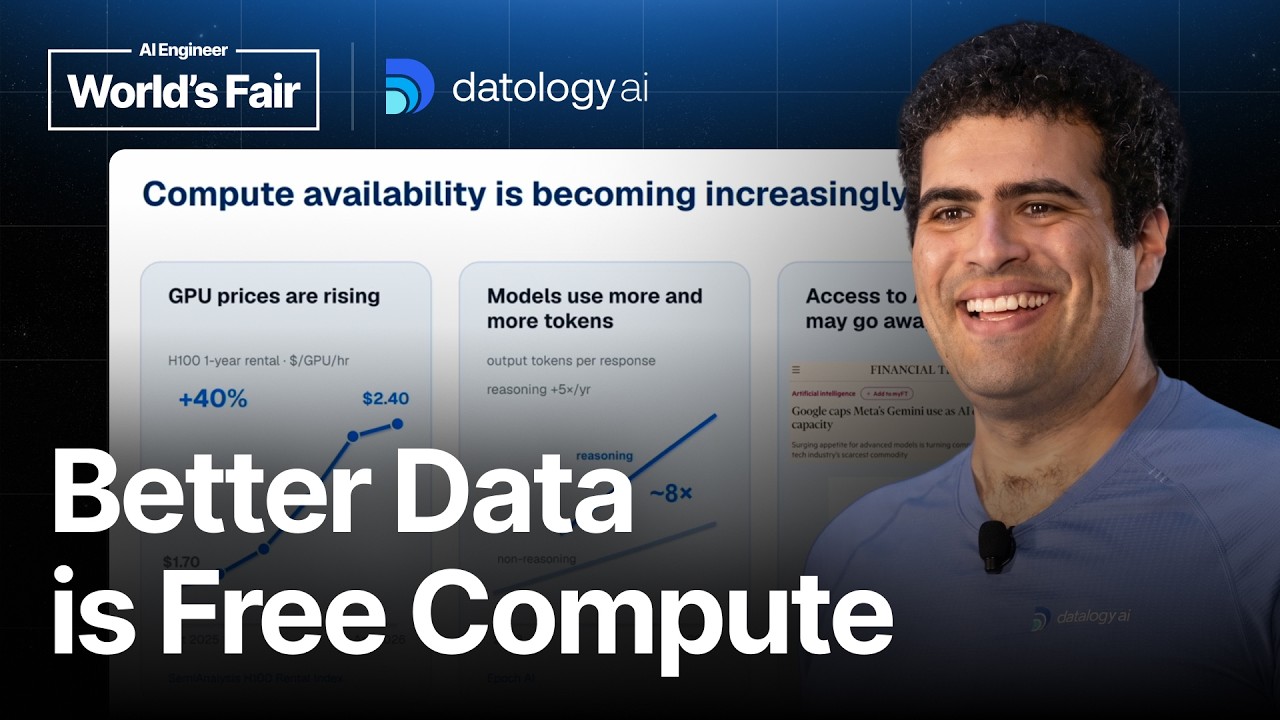
Data Quality Is the Compute Multiplier — Ari Morcos, DatologyAI
Ari Morcos, CEO of DatologyAI, explains why data quality is the critical "compute multiplier" in an era of scarce and expensive compute. He outlines DatologyAI's "oil refinery" process (Clean, Curate, Create, Compose) for enhancing datasets. Through empirical results and customer cases like Thomson Reuters and Arcee, he demonstrates how superior data curation leads to significantly better models, reduced training costs, improved inference efficiency, and the ability to train competitive models for a fraction of traditional costs, proving that manufacturing high-quality data is more effective than buying more compute.
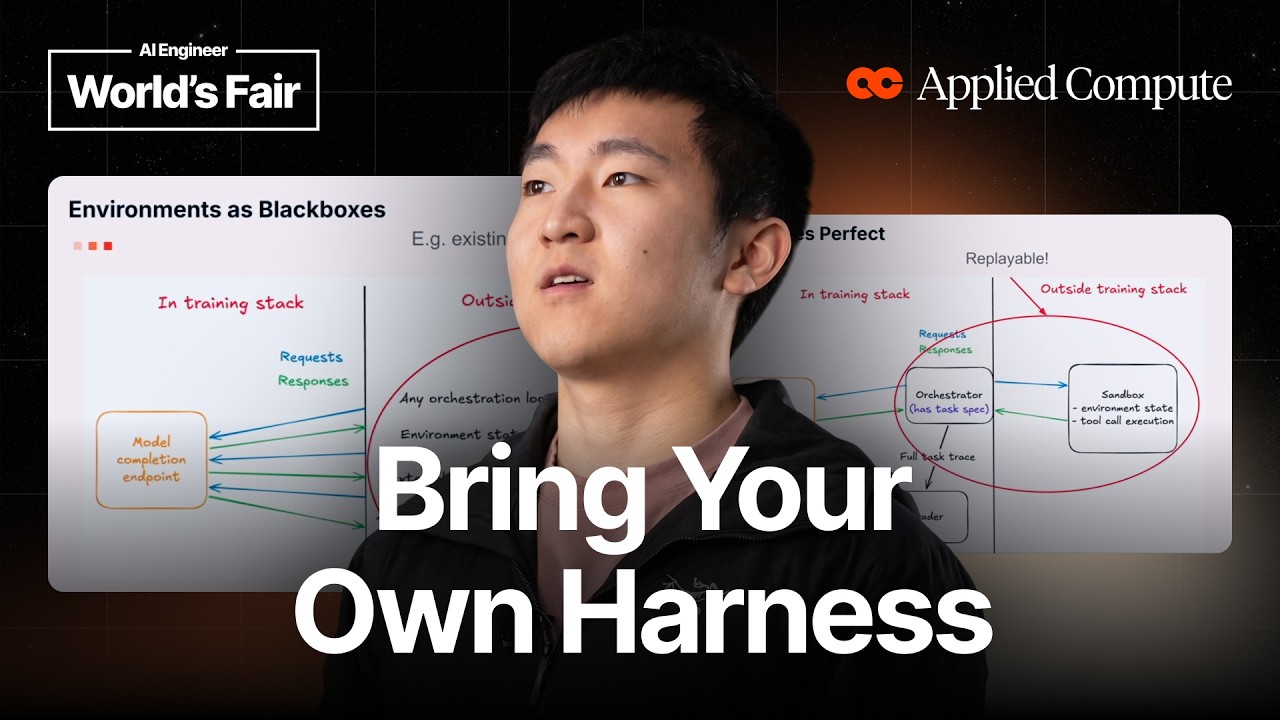
Learning on the Job: The Future of Post-Training — Raymond Feng, Applied Compute
Raymond Feng presents Applied Compute's approach to training custom AI models that learn "on the job" using reinforcement learning. He details the evolution from controlled Q&A to synthetic environments, highlighting the core GRPO-style loop. A major focus is tackling the challenges of environment fidelity and "reward hacking" in simulated settings. The discussion then moves to the complexities of training directly within real-world enterprise harnesses, addressing issues like non-replayability and off-policy data. Feng concludes by outlining frontier research in self-distillation, automated data pipelines, and qualitative feedback, envisioning a future where models continuously learn and self-evaluate from every interaction, making "experience the dominant medium of improvement."
Data and Environment Curation for Post-Training LLMs — Mahesh Sathiamoorthy, Bespoke Labs
Mahesh Sathiamoorthy of Bespoke Labs argues that high-quality data and curated RL environments are the true bottlenecks for post-training LLMs, especially for building reliable, autonomous agents. He grounds this in experiences with OpenThoughts, a reasoning dataset, highlighting counterintuitive lessons like the importance of diverse reasoning traces and the fact that stronger teachers aren't always best. A key takeaway, reinforced by their Curator tooling, is that a disciplined curation stack is essential for transforming base models into capable, post-trained agents for real-world applications like credit card compliance.