Binomial Flows: Denoising and flow matching for discrete ordinal data
Shenfeld presents binomial flows, a discrete analogue of Tweedie-based diffusion for ordinal, non-negative integer data. The method pairs binomial thinning for noising with a Poisson-type continuous-time Markov chain whose rate is expressed through a learned denoiser, enabling training with MSE, sampling, and exact likelihood estimation. Results include the best reported CIFAR-10 FID among ordinal discrete diffusion models, obtained by adapting the EDM framework.
Yair Shenfeld opens by framing the talk around a gap in discrete diffusion: in continuous flow matching and diffusion, Tweedie’s formula ties the learned denoiser (the conditional expectation E[x1 | xt]) to the score used for sampling, but in discrete settings most work learns scores or rates directly and that link is largely missing. He argues the right target for this link is ordinal discrete data, i.e., non-negative integers, which sit between continuous data (where order matters) and categorical data such as language tokens (where it does not). Practical examples include pixel intensities 0 to 255 and gene expression counts in single cells.
The talk follows a three-step “cookbook” for generative modeling. Step one is choosing a noising process: a family of conditional distributions p_t(x_t | x_1) that recovers the data at t=1 and forgets it at t=0 while remaining easy to sample. Step two is training a denoiser, which can be done with a simple mean squared error or any Bregman divergence. Step three is sampling, which requires converting the denoiser into a score or rate. Shenfeld stresses that Gaussian noise is special here: it makes Tweedie’s formula hold, so the denoiser determines the score. A generic choice of noising kernel gives a denoiser that is still well defined but no longer tied to the gradient of the log marginal.
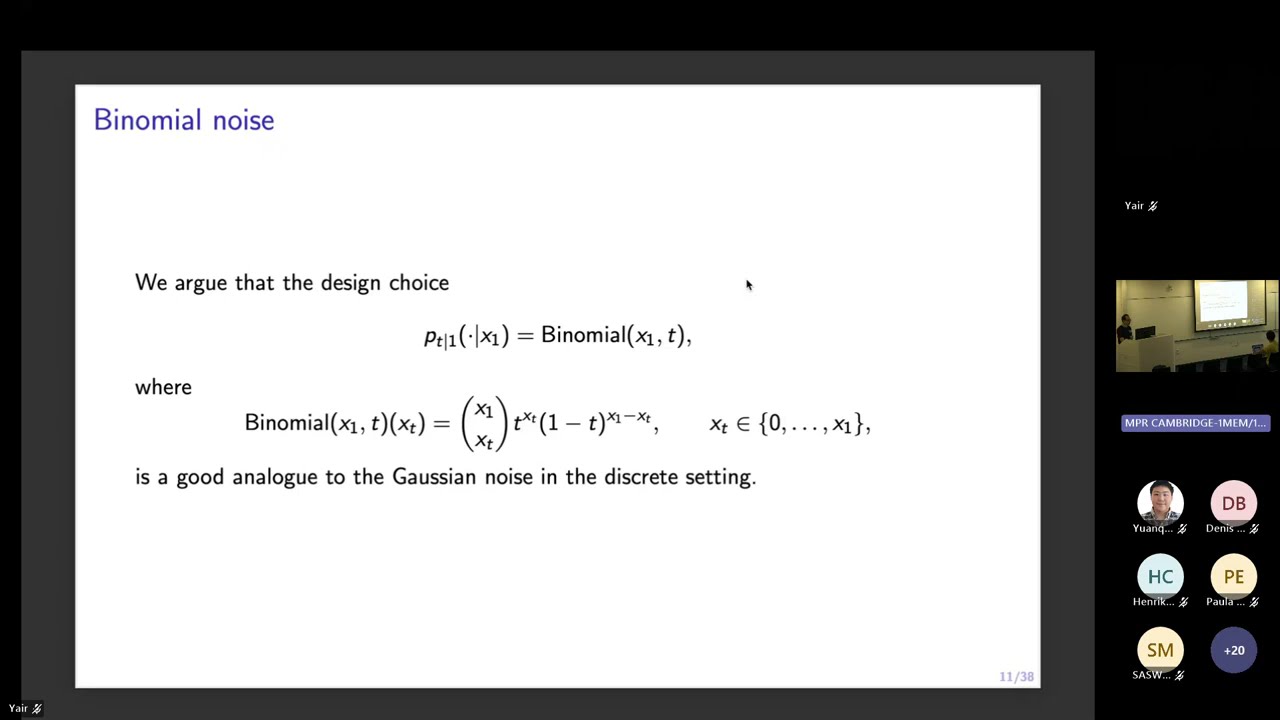
For the discrete case the proposed noising is binomial thinning. Each coordinate x_1 is treated as the number of trials, and x_t is drawn as Binomial(x_1, t). At t=1 this returns the data exactly, and at t=0 it collapses to zero. Because the noise only ever removes counts, the process never overshoots the support and stays on the non-negative integers. Shenfeld notes the asymmetry: the process always perturbs downward toward zero, which can be a benefit (no overshoot) or a drawback, and he mentions ongoing work on breaking this symmetry. Adding Gaussian noise to integers is rejected because the result leaves the integer lattice.
The central theoretical result is a discrete analogue of Tweedie’s formula. The denoiser is linked to a rate of a continuous-time Markov chain that jumps upward from zero, the Poisson-type process whose marginal at t=1 equals the data distribution. This “Poisson flow” is described from several equivalent viewpoints: a controlled Poisson point process (points placed under a time-varying intensity that is controlled by the current state, illustrated with a plotted example), a Schrödinger-bridge-style relative-entropy minimization against a Poisson reference, an h-transform of the Poisson semigroup, and a time reversal of a Poisson bridge. Sampling uses standard continuous-time Markov chain samplers, such as Euler or tau-leaping. Shenfeld also points out that the Poisson flow is the discrete counterpart of the Gaussian flow with its drift given by a heat-semigroup score, and that this process has been studied before mainly for theoretical high-dimensional probability work.
A further benefit is exact likelihood estimation. The log-likelihood can be written as an integral over the rate, which is in turn expressed through the denoiser. Shenfeld acknowledges that the integral has high variance in practice, but initial checks on synthetic distributions gave reasonable results.
On experiments, synthetic one-dimensional distributions were recovered well, with exact likelihoods that matched the explicit PMFs. The main benchmark is CIFAR-10 FID. Shenfeld places the result in context: continuous diffusion remains state of the art, but among discrete diffusion models that respect the ordering of values, the binomial flow reports the best FID, with a clear margin over categorical approaches and over other ordinal methods such as Blackout diffusion and Poisson-based alternatives. The gain is attributed to adopting the EDM framework (Karras et al.), whose preconditioning, scaling, and noise-level sampling tricks depend on training with mean squared error. Ablations show EDM is essential, since removing it sharply worsens FID. He also explains the time parameterization: signal-to-noise changes sharply near t=0, so the denoiser needs a logarithmic or otherwise adapted time grid, and time samples should be concentrated where the gap between the learned denoiser and an affine baseline is largest. He concedes the method needs more neural function evaluations than continuous models.
During Q&A, Shenfeld addresses several points. Shifting the data to allow negative values is possible but changes the interpretation. Choosing a base point other than zero is viable with rescaling, though it was not explored heavily. He doubts that large integer ranges are essential, suggesting the method should work for small supports too. On applicability to language or DNA, he is cautious: biological count data such as gene expression is a natural fit, but mapping vocabulary tokens to integers would make the process inefficient because the Poisson flow moves by small steps and tokens have no meaningful order. On whether the binomial-Poisson pairing is fundamental, he says the right analogue is a matter of matching the noising kernel to a process that yields a Tweedie-like identity. He also notes that in the Gaussian case a single mean parameter determines the posterior, which is why a denoiser suffices, and that the discrete setting needs an analogous property.