How METR measures Long Tasks and Experienced Open Source Dev Productivity - Joel Becker, METR
AI models show remarkable progress on benchmarks, yet a field study with experienced developers revealed no productivity gains. This summary explores the disconnect between lab results and real-world impact, examining the causal relationship between compute and AI capabilities, the nuances of the developer productivity study, and future directions for measuring what AI can truly do.
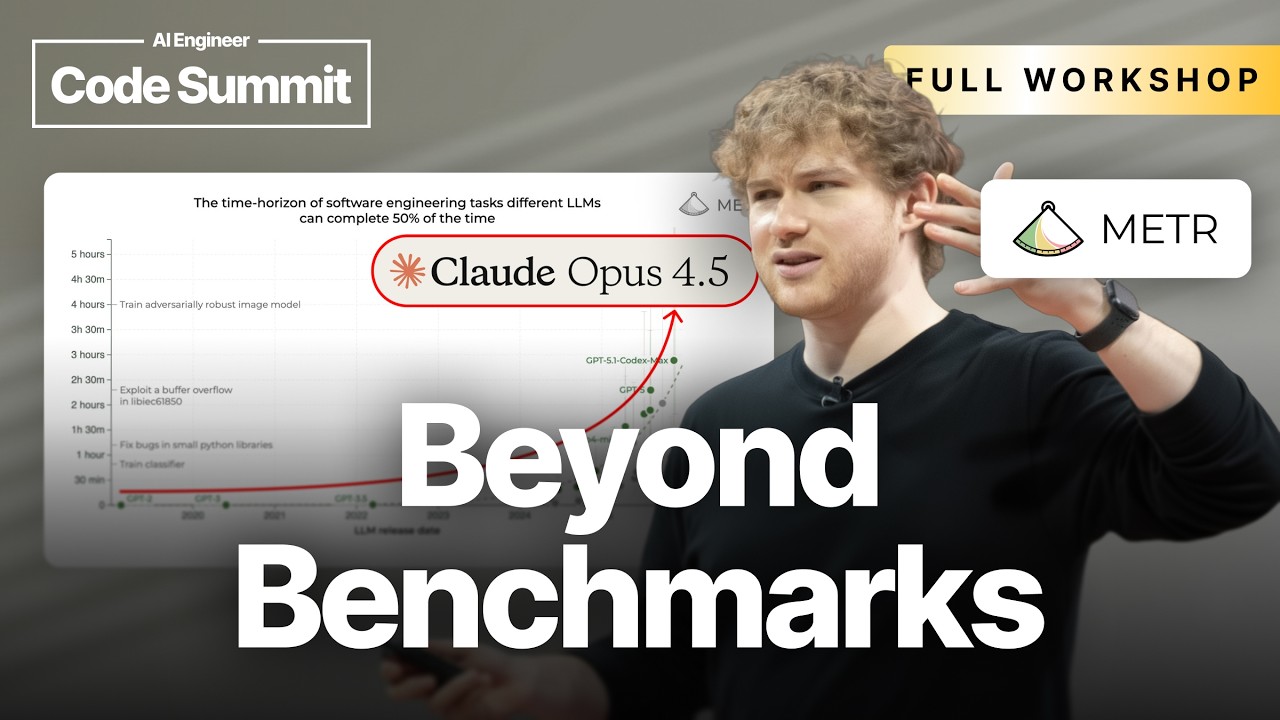
The Link Between Compute Growth and AI Capabilities
A core argument posits a causally proportional relationship between the growth of compute power and the growth of AI capabilities, as measured by metrics like METR’s “time horizon.” The time horizon represents the duration a model can effectively work on a complex task. This relationship has been observed as a straight line on log-linear plots, a forecasting tool that has proven highly reliable across many orders of magnitude.
This causal link has significant implications. If compute growth were to slow down—due to physical constraints like power or, more likely, financial limitations—it would directly lead to a proportional slowdown in the growth of AI capabilities. A milestone that might seem near could be delayed enormously, assuming no unpredictable technological breakthroughs, like another “Transformer moment,” occur.
The Surprising Results of the Developer Productivity Study
Despite impressive benchmark scores (e.g., on SWE-bench), a randomized controlled trial (RCT) with experienced developers working on mature, open-source projects yielded a surprising result: AI tools did not speed up their work. In fact, the point estimate suggested a slight slowdown.
This contradicts the developers’ own perception; they felt more productive and predicted they would be faster with AI assistance. This highlights a known cognitive bias: humans are notoriously bad at estimating the time a task takes. The study suggests that while developers believe AI makes them faster, the quantitative data does not support this, at least not for this specific group of experts.
The quality bar in these open-source projects is exceptionally high. Developers are incentivized to maintain the long-term health and ease of maintenance of the codebase. The median pull request (PR) in the study required zero minutes of post-review code changes, indicating that PRs were submitted in a near-perfect state. AI-generated code, while often making progress in the right direction, frequently fails to account for the deep, accumulated context of a project, requiring significant human effort for verification and cleanup to meet this high standard.
Investigating the Discrepancy: The “J-Curve” Hypothesis
A primary explanation for the lack of speedup is the “J-curve” effect: an initial dip in productivity as users learn a new tool, followed by a later increase as they gain proficiency. The discussion explored this possibility in depth:
- Familiarity as a Factor: Could the developers’ lack of familiarity with the specific AI tool (Cursor) be the cause? The speaker is skeptical, noting that most of the learning curve is in understanding what AI is good or bad at, and these developers already had experience with LLMs in their workflow. Watching screen recordings, the speaker observed that the developers were already prompting effectively.
- Data Analysis: Plots analyzing performance based on prior AI experience or over the course of the study did not show a clear trend of improvement. While one graph plotting hours of experience did hint at a J-shape, the speaker cautioned against over-interpreting it due to the small sample size (16 developers) and conservative coding of experience levels.
- Expert vs. Novice Users: The study deliberately used expert developers to reduce variance and isolate the effect of the AI tool. For these experts, who have a vast amount of mental context about their projects, the AI may struggle to provide value compared to their own established workflows. In contrast, AI can be a significant help in unfamiliar legacy codebases with poor documentation.
Ultimately, while the J-curve explanation remains “on the table,” the evidence from this particular study is weak.
Challenges for AI in Other Domains: Data Science and Law
The discussion extended to other professional domains, hypothesizing where AI might struggle.
- Data Science: This field presents a significant challenge due to the messy, undocumented, and often contradictory nature of enterprise data. An analyst at a large company might face thousands of tables with similar names (e.g., “impressions”), and the “tacit knowledge” required to navigate this landscape is not present in AI training data. Models are good at writing SQL but fail at the complex, context-heavy task of figuring out what data to query and how to interpret its historical inconsistencies.
- Law: While AI shows promise for tasks like legal discovery, the profession is constrained by legacy practices and legal restrictions. The “stodginess” of the field may slow adoption, though new, more agile firms could eventually outcompete older ones.
Future Directions for Measuring AI Capabilities
To better understand and forecast AI progress, the research is moving beyond current benchmarks and RCTs.
- Extending Time Horizon Tasks: As models improve, creating tasks that are long and complex enough to challenge them becomes increasingly difficult. One proposed direction is to measure capability on dangerous tasks “whilst being watched,” i.e., with an AI or human monitor in the loop. The cognitive load of evading detection could significantly reduce a model’s effective time horizon, buying researchers more time to create evaluations.
- Triangulating Evidence from New Sources:
- In-the-Wild Transcripts: Analyzing the vast traces of data left by agents in products like Cursor can provide a more realistic, less experimental view of how models perform on real-world “crap.”
- Simulations (e.g., AI Village): Observing agents trying to accomplish fuzzy, open-ended goals (e.g., “organize an event”) in a simulated environment reveals where they fail. Currently, models “fall on their faces and suck” at these tasks, often because the real world is not neatly packaged like a benchmark. This points to a “neurodivergence” in AI; the world is shaped for human cognition, and AIs struggle with the misalignment.
- Robotics and Physical Automation: The lag in robotics capabilities behind LLMs is a key area of debate. While often attributed to data limitations, the immense difficulty, cost, and slow iteration cycles of manufacturing and hardware present a fundamental bottleneck. Automating AI R&D might require a “software-only singularity,” but this seems unlikely without also automating chip design and production—a challenge that may take far longer than many expect.