Distill the LLM, Don't Serve It: Search & Personalization at DoorDash — Raghav Saboo, DoorDash
Raghav Saboo, Staff ML Engineer at DoorDash, argues that semantic understanding, not engagement, is the real bottleneck in marketplace discovery. He walks through four LLM-driven primitives (graded relevance supervision, semantic IDs, multi-timescale consumer memory, and steerable personalized collections) and explains the core pattern of reasoning offline with LLMs and distilling that into fast serving models.
The core claim
Raghav Saboo, Staff ML Engineer and Tech Lead for Search and Personalization at DoorDash, opens with a simple claim: in a marketplace like DoorDash, the real bottleneck for discovery is semantic understanding rather than engagement optimization. The hard problem is knowing what items actually mean in context and what a shopper intends to do. Historically DoorDash treated discovery as an engagement problem, but he argues LLMs give the team a genuinely new lever. The gluten-free pasta example makes the point clearly. An engagement-trained ranker will happily surface regular spaghetti because it sells well, and gluten-free white bread may get retrieved simply because it shares a term with the query. Neither is the right answer. What the team actually wants is graded relevance: true gluten-free pasta is highly relevant, chickpea pasta is a reasonable substitute, and regular spaghetti fails the user’s constraint.
Beyond restaurants: broad shopping missions
DoorDash now spans grocery, retail, pets, gifting and more, with a goal of capturing every shoppable moment. Users arrive with broad missions. A new puppy owner searching for puppy food may reformulate queries, land on collections for crates, leashes and training pads, and eventually check out, often across several sessions and days. Capturing that whole arc is hard because it spans many models. This is the motivation for the four primitives: supervision, catalog semantics, consumer memory, and steerable content generation.
Primitive 1: LLM supervision
The question is how to teach retrieval and ranking what ‘good’ means for each task. Human annotation is accurate but expensive, slow, and stale in a fast-changing catalog. Behavioral signals are abundant but biased by exposure, position, price, promotions and previous model choices. The LLM supplies a scalable reasoning signal.
The pipeline starts with a high-quality seed set of query-item pairs labeled on a three-level scale (0, 1, 2). Suspicious cases are audited. If an item labeled irrelevant performs well on add-to-cart or conversion, it is re-evaluated by a stronger LLM using more granular prompts. Labels are also reconciled with query-to-taxonomy and category models, so a label can be adjusted when a query maps to valid categories that the item belongs to. The resulting high-precision golden dataset fine-tunes a lightweight LLM labeler (GPT-4o mini is the example given), which runs offline across the full catalog to produce graded labels. Those labels then become one shared target for both retrieval and ranking. The guiding pattern is to reason expensively once, offline, and distill the result into models that can be served cheaply.
For retrieval, standard embeddings at e-commerce scale collapse the distinction between related items and exact matches, substitutes and complements. The fix is a two-stage contrastive method trained on the graded labels. Stage one, mining, shapes global geometry with two-tower encoders and a multi-level supervised contrastive loss, then uses the base model to find hard negatives (items ranked too high) and strong positives ranked too low. Stage two applies curriculum training on these relabeled hard cases, which sharply separates relevant from moderately relevant items. This produced a 2.3 percent NDCG gain in relevance, which carried through to downstream business metrics.
For ranking, the team does not replace engagement objectives. An ordinal relevance tower sits alongside the click, add-to-cart and conversion towers on shared bottom layers, so semantic fit is distilled in the same backward pass. A value function then blends engagement and relevance, tuned per surface. The recurring theme is distill, don’t replace: the LLM stays out of the serving path.
Primitive 2: catalog semantics with semantic IDs
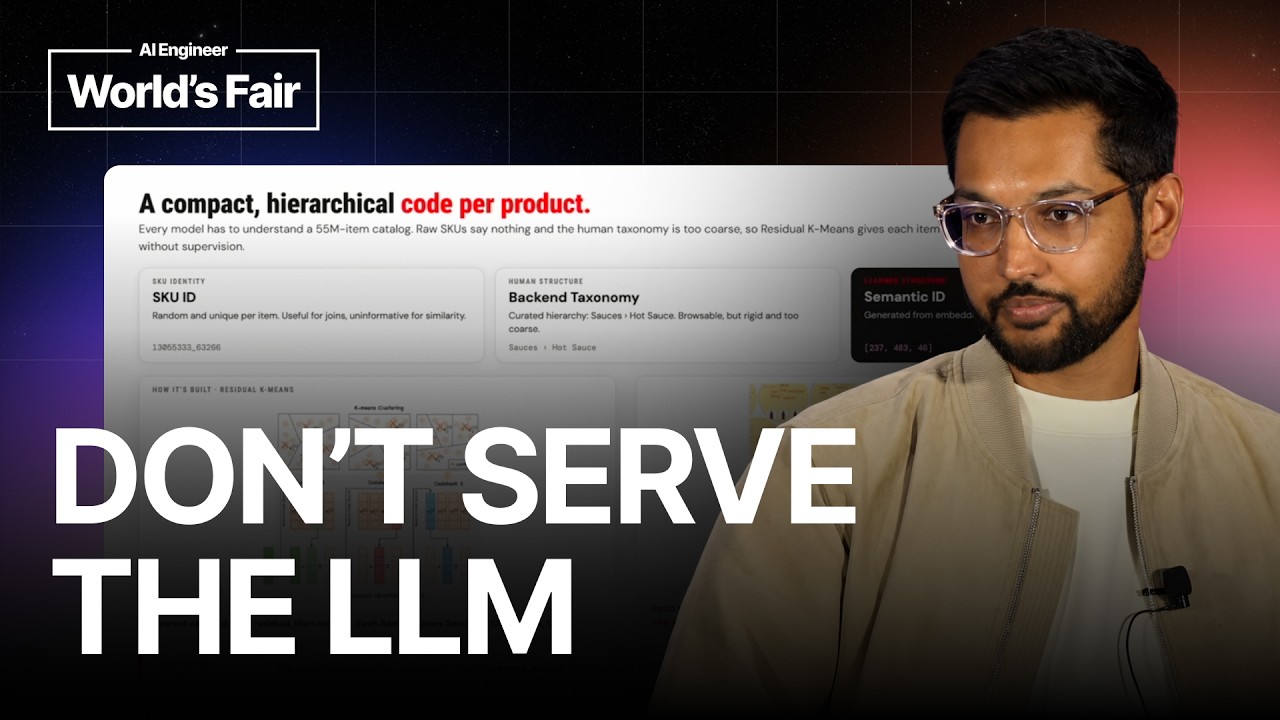
At a scale of billions of store-item SKUs, opaque SKU identifiers carry no semantic meaning, and the human-curated taxonomy is often too coarse and rigid. A ‘hot sauces’ node cannot express how Frank’s, Tabasco and Huy Fong relate to one another. Semantic IDs are learned hierarchical codes. The prefix captures broad neighborhoods and later tokens capture finer distinctions. In the hot sauce example, items share the first two prefix tokens and then split into Mexican, Caribbean and Korean styles, with zero labels involved.
This learned structure unlocks several capabilities. It enables cross-category relationships, so chips, salsa and guacamole can sit in different taxonomy branches yet belong to the same shopping mission. It helps cold start, since new catalog items can be added as sparse ID features using n-gram and byte-pair style token encoding. It improves tail coverage, because sparse items inherit signal from semantic neighbors without waiting for exposure. It also supports reverse auditing, measuring how well human labels agree with the learned structure.
The impact is measurable. Semantic IDs are among the biggest ranker improvements the team has seen, with MRR gains of 4 to 5 percent that translated into conversion wins. They also power query reformulation. A query like Sriracha can expand to garlic chili sauce or sambal oelek, and because those suggestions are grounded in catalog neighborhoods, they correspond to items DoorDash actually has in inventory. Suggestions that lack inventory are, in his words, meaningless.
Primitive 3: consumer memory
User embeddings capture a lot about consumers but not why they hold certain intents or preferences, and LLMs cannot readily consume them. The memory primitive represents the consumer in forms that are semantic, inspectable and reusable, organized across three timescales. Long-term memory holds durable preferences drawn from orders, searches, browsing and support interactions. Real-time context covers in-session state such as cart contents and active searches. Stated preferences come from explicit agentic interactions, such as consumers telling Ask DoorDash their constraints.
Long-term memory is stored as structured memory blocks that can gain new dimensions over time, such as dietary, dining or substitution preferences, while remaining decoupled from downstream systems that do not need to reinterpret them. Each consumer’s memory is materialized three ways: human-readable text, latent vectors that feed retrieval and ranking models, and graph or hierarchical structures linking consumers, brands, taxonomy nodes and revealed preferences. Context graphs suit shopping journeys well, because consumer-item interactions are sparse and multi-hop. At fine-grained taxonomy levels, graph-based embeddings have been shown to outperform the existing taxonomy-based embeddings for retrieval.
Today this memory framework appears in three places: personalized collections, agentic personalization in Ask DoorDash, and as features encoded into retrieval and ranking models.
Primitive 4: steerable content generation
The inputs described so far, including semantic IDs, memory blocks and graded relevance labels, feed LLMs, small language models and traditional models. These generate different output shapes, such as ranked semantic ID lists, carousel titles and subcopy. The clearest example is personalized collections on store pages. Previously these were fixed libraries or attribute-based. Now an offline batch LLM process synthesizes consumer-level collections, from title and subtitle down to the actual items, using consumer memory and semantic IDs. Because generation happens offline, the existing retrieval and ranking stack still handles item hydration and collection ranking at serving time.
The approach is steerable. The system reacts to occasions and moments. A shopper with plant-based affinity gets plant-based pantry rows, a cat-only household gets cat dry food rows, and a session indicating pantry restocking biases toward pantry staples. Early results are encouraging. Within the pets vertical, the rollout drove close to a 1 percent increase in order rate and a 6 percent increase in active users.
Takeaways
The talk closes with three points. First, discovery is a semantic understanding problem, not only an engagement one, and LLMs offer a way to reason about item meaning and shopper intent. Second, LLM reasoning should be distilled into durable primitives (labels, semantic IDs, memory and generated content) computed offline, so smaller and faster models can serve them, since the online LLM call is often not the right production architecture. Third, once these shared representations exist, they can power retrieval, ranking and content generation alike.