Evals Are Not Unit Tests — Ido Pesok, Vercel v0
Ido Pesok from Vercel explains why LLM-based applications often fail in production despite successful demos, and presents a systematic framework for building reliable AI systems using application-layer evaluations ("evals").
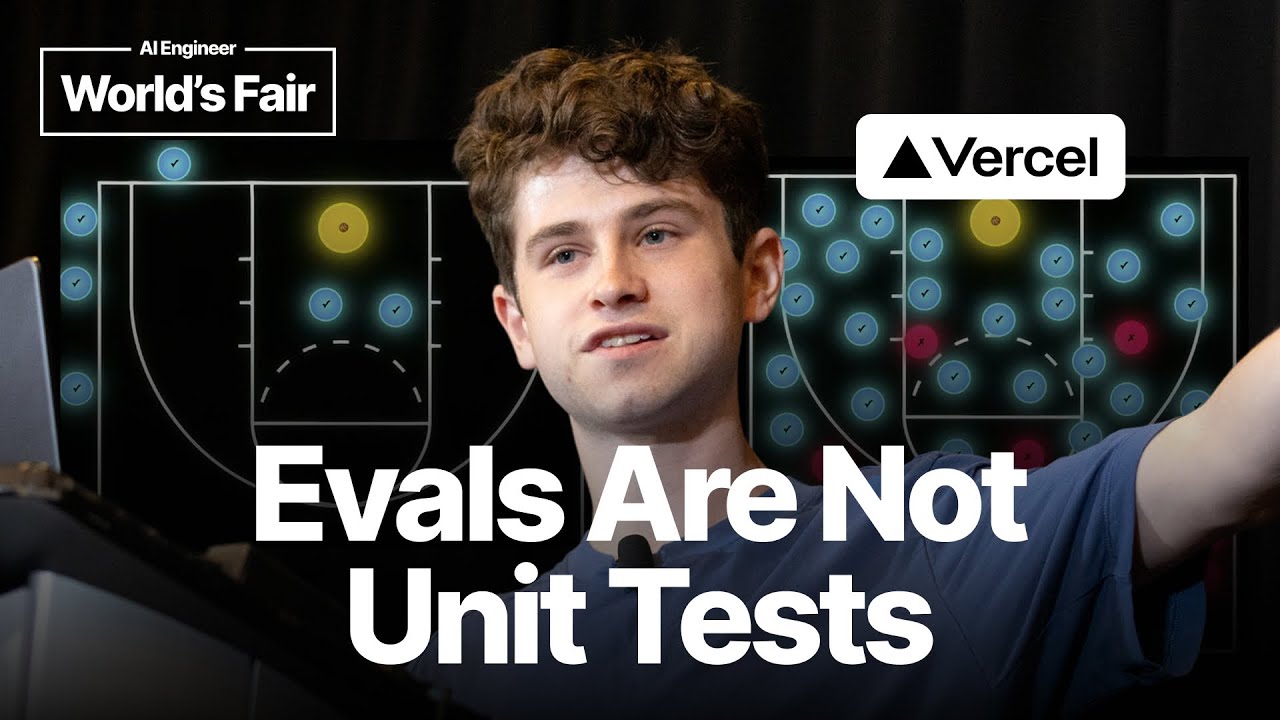
LLM-based applications possess a unique and challenging property: they are incredibly “demo-savvy,” appearing impressive during development but often failing unpredictably in production when faced with real-world user queries. This unreliability is a significant hurdle, as no one will use a product that doesn’t work. The core issue stems from the non-deterministic nature of LLMs, which can fail on inputs developers never anticipated. The solution is to move beyond simple testing and adopt a systematic evaluation framework at the application layer.
The Basketball Court Analogy for Evals
To visualize how to approach this, think of the evaluation process as a basketball court. This analogy helps structure the problem of testing a non-deterministic system.
- The Court: Represents the entire domain of possible user queries for your specific application.
- The Basket: The desired, correct outcome or response from the AI.
- A Shot: A specific user query being tested (the “task”).
- A Make (Blue Dot): The AI successfully produced the correct output for the query.
- A Miss (Red Dot): The AI failed to produce the correct output.
- Shot Difficulty: More complex or unusual queries are like shots taken from further away—they are inherently harder.
- Out of Bounds: Queries that fall outside the intended scope of your application. It’s crucial not to waste time evaluating these.
The goal is to systematically “plot” your application’s performance across the entire “court” to understand where it succeeds (blue dots) and where it fails (red dots).
Building an Effective Eval Framework
A robust evaluation framework consists of several key stages, from data collection to scoring and integration.
1. Define Your Court: Understand the User Domain
This is the most critical step. You must deeply understand the range of queries your users actually make. Avoid two common traps:
- The Out-of-Bounds Trap: Don’t waste energy creating evals for data that is irrelevant to your users’ needs. You have enough real problems to solve.
- The Concentrated Points Trap: Ensure your evals cover the entire court, not just a small, easy cluster of test cases. A good set of evals tests the boundaries and diverse regions of your application’s domain.
2. Collect Data for Evals
There is no shortcut to building a comprehensive dataset for your evals. You must do the work to understand what your court looks like.
- User Feedback: Collect thumbs-up/thumbs-down data. While noisy, it’s a strong signal.
- Observability Logs: Regularly review random samples from your production logs to gain an unfiltered understanding of how the product is being used.
- Community Channels: Forums and social media platforms like X are valuable sources for finding user-reported issues.
A good dataset allows you to create a visual map of your system’s strengths and weaknesses, helping you prioritize which “red areas” of the court to focus on improving.
3. Structure Evals: Constants vs. Variables
To create scalable and reusable evals, separate the constant elements from the variable ones.
- Constants in
data: The user input itself (e.g., “how many Rs are in strawberry”) is a constant. It should be stored as part of the dataset and not change. - Variables in the
task: The components you are testing—such as different system prompts, models, or RAG strategies—are the variables.
This structure allows you to test a new system prompt against your entire dataset of user queries without having to rewrite every test case. It is also crucial to share code between your evals and your production environment. Abstractions like the Vercel AI SDK’s middleware can be used to share pre-processing logic, ensuring your “practice” in evals is as close to the “real game” in production as possible.
4. Scoring Evals: Simplicity and Determinism
The final step is scoring the outcome.
- Lean Towards Deterministic, Pass/Fail Scores: Complex scoring systems are difficult to debug, maintain, and share across teams. Ask yourself, “When I look at this output, what am I looking for to see if it failed?” and code that simple check.
- Human Review is Okay: For highly subjective tasks like evaluating writing quality, it’s acceptable to use human review to get an accurate signal. The long-term payoff from having an accurate evaluation set is worth the initial effort.
- Prompt Tweaks for Scoring: For an eval, it’s acceptable to slightly modify a prompt to make the output easier to score programmatically (e.g., “Output your final answer in
<answer>tags.”). This helps in creating a simple string-matching score while not affecting the core logic being tested.
Integration and The Payoff
To maximize their impact, evals should be integrated directly into your CI/CD pipeline. Running your full evaluation suite on every pull request generates a report showing improvements and, just as importantly, regressions. This prevents a change that fixes one part of the “court” from silently breaking another.
By treating evals as a core part of the development lifecycle, you can move from guesswork to systematic improvement. As the saying goes, “improvement without measurement is limited and imprecise.” Evals provide the clarity needed to build more reliable and high-quality AI applications, leading to higher user retention and less time spent on support and operations.