Verifiers

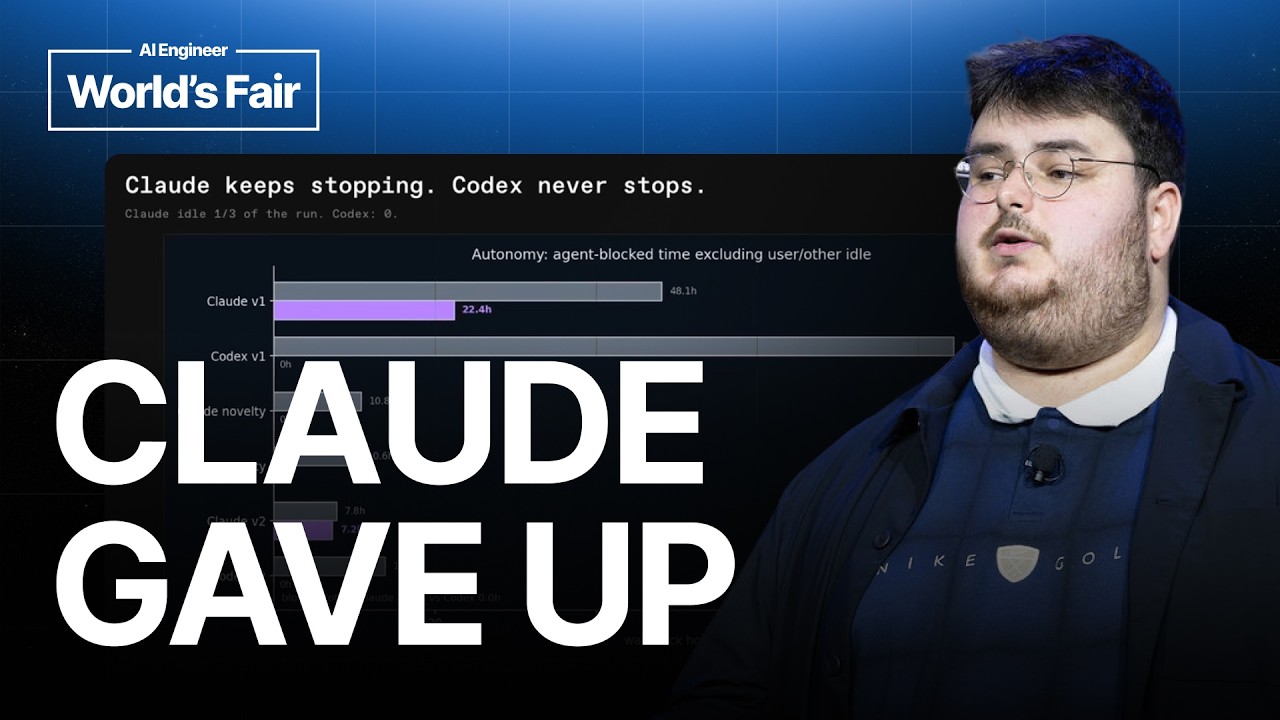
We Let Claude Code and Codex Race Human Researchers — Elie Bakouch, Prime Intellect

We Let Claude Code and Codex Race Human Researchers — Elie Bakouch, Prime Intellect

Elie Bakouch, a research engineer at Prime Intellect, reports on setting Claude Code and Codex loose on the community Optimizer Speedrun, a race to train a GPT-2-level model in the fewest steps. Both agents beat the human record, but they behaved very differently, and none of them invented a new optimizer. The talk closes with a proposed AlphaEvolve-style discovery loop and an argument for doing this research openly.
Rethinking Environments for Long-Horizon Work — Rayan Garg, Theta Software

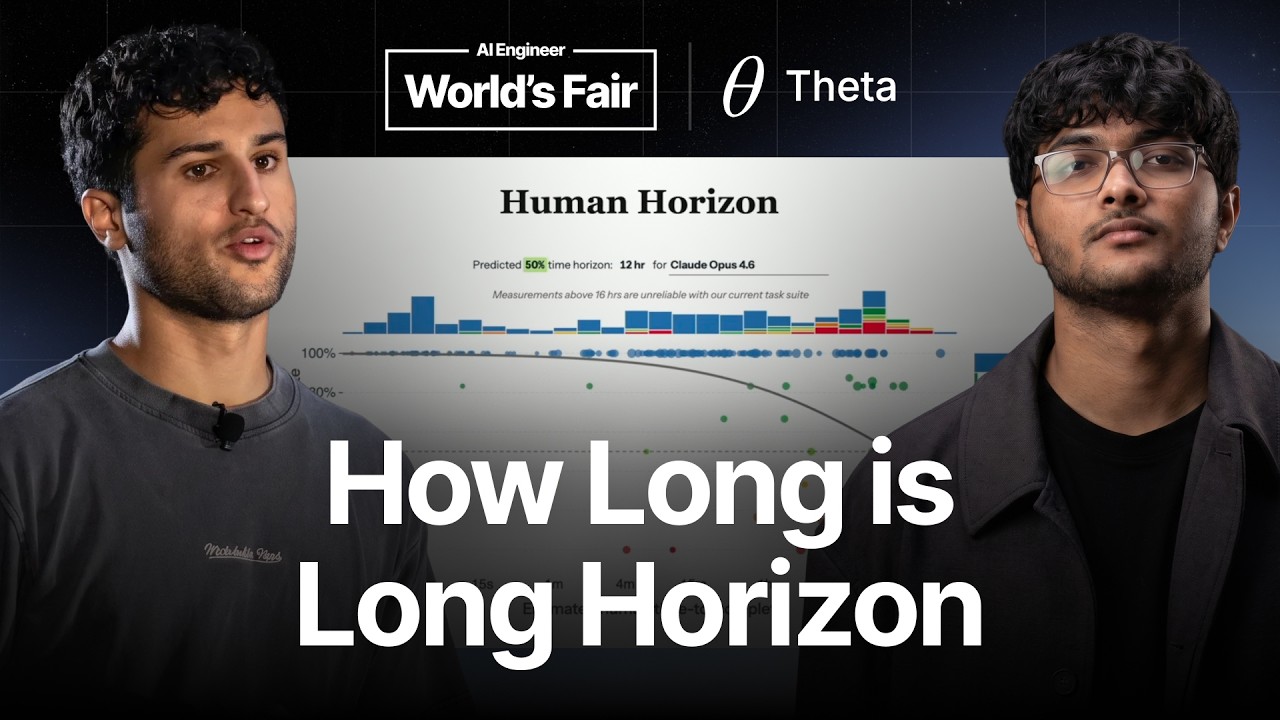
Rethinking Environments for Long-Horizon Work — Rayan Garg, Theta Software

Rayan Garg from Theta Software delves into the complexities of defining and evaluating "long horizon" tasks for AI agents. He critiques current metrics and benchmarks, emphasizing the critical role of sophisticated environment design and robust verifiers (judge models) in driving true progress, particularly in "software-failing domains." The discussion highlights issues like task ambiguity, state changes, and the necessity for granular reward signals for effective model training.

Claude for Long-Horizon Tasks — Lance Martin, Anthropic

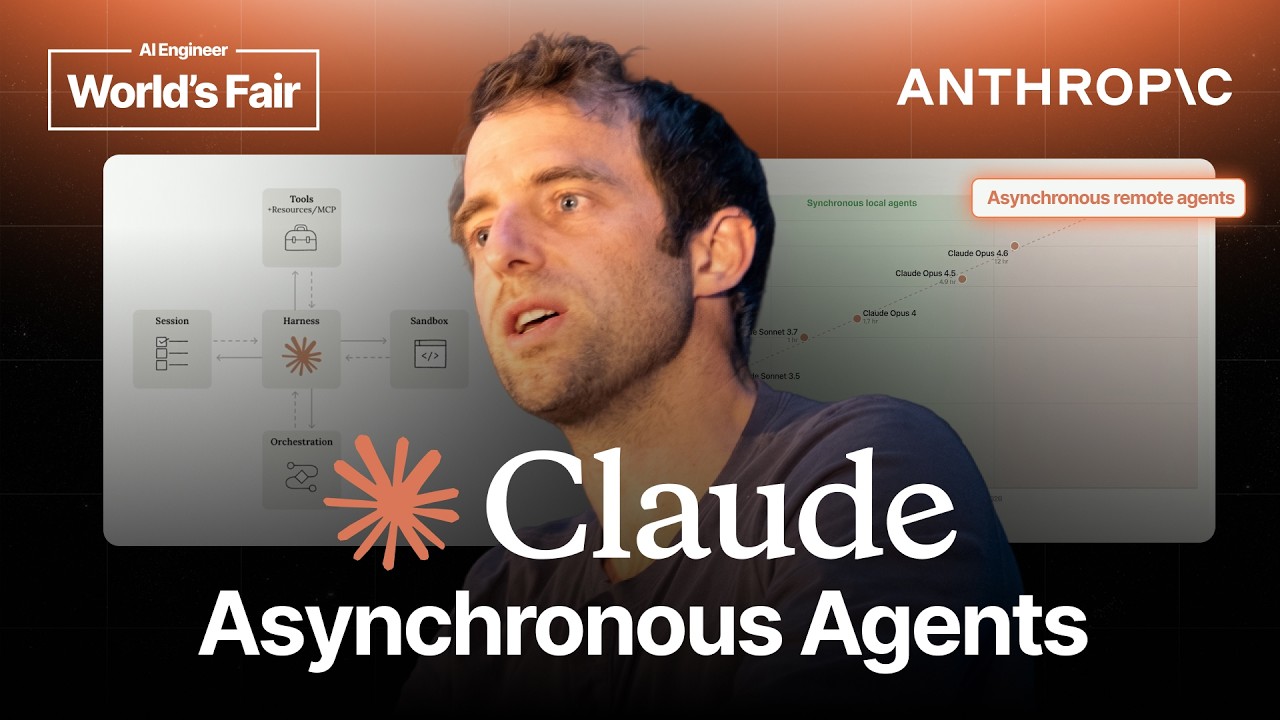
Claude for Long-Horizon Tasks — Lance Martin, Anthropic

Lance Martin from Anthropic shares insights into building reliable and secure long-horizon agents with Claude. He details architectural principles like decoupling the 'brain' from the 'hands' for reliability and security, implementing independent verifiers for self-correction, and developing advanced self-learning memory systems akin to human memory's in-band writing and offline 'dreaming' consolidation. The talk concludes with a vision for evolving agent harnesses towards organizational-level, proactive, and multiplayer capabilities.