Swe bench

Don't Trust Your AI Agents. Test Them Like a Scientist — Stephanie Jarmak, Omni Analytics

Don't Trust Your AI Agents. Test Them Like a Scientist — Stephanie Jarmak, Omni Analytics

Stephanie Jarmak, who moved from astronomy into building coding benchmarks and agent evals, argues that most agent evaluations are easy to misread. She covers how harness choice can swamp model differences, why public benchmarks serve shortlisting rather than decisions, how to design experiment-style evals with realistic tasks, repeated runs, and full traces, and how to set quality gates, manage human review load, verify agent records, and treat production as the final test.
The Death of the Code Review: What the Data Actually Says — Laurie Voss, Arize AI

The Death of the Code Review: What the Data Actually Says — Laurie Voss, Arize AI

Agents have multiplied code output, but human review cannot keep pace, and reviewer effectiveness collapses past roughly 400 lines. This talk by Laurie Voss surveys what OpenAI, METR, Cognition, Cursor, GitHub, Carlini, and Bun are doing about it, from mergeability benchmarks and multipass automated review to prompt injection and production monitoring as the last line of defense.

SWE-rebench: Lessons from Evaluating Coding Agents — Ibragim Badertdinov, Nebius

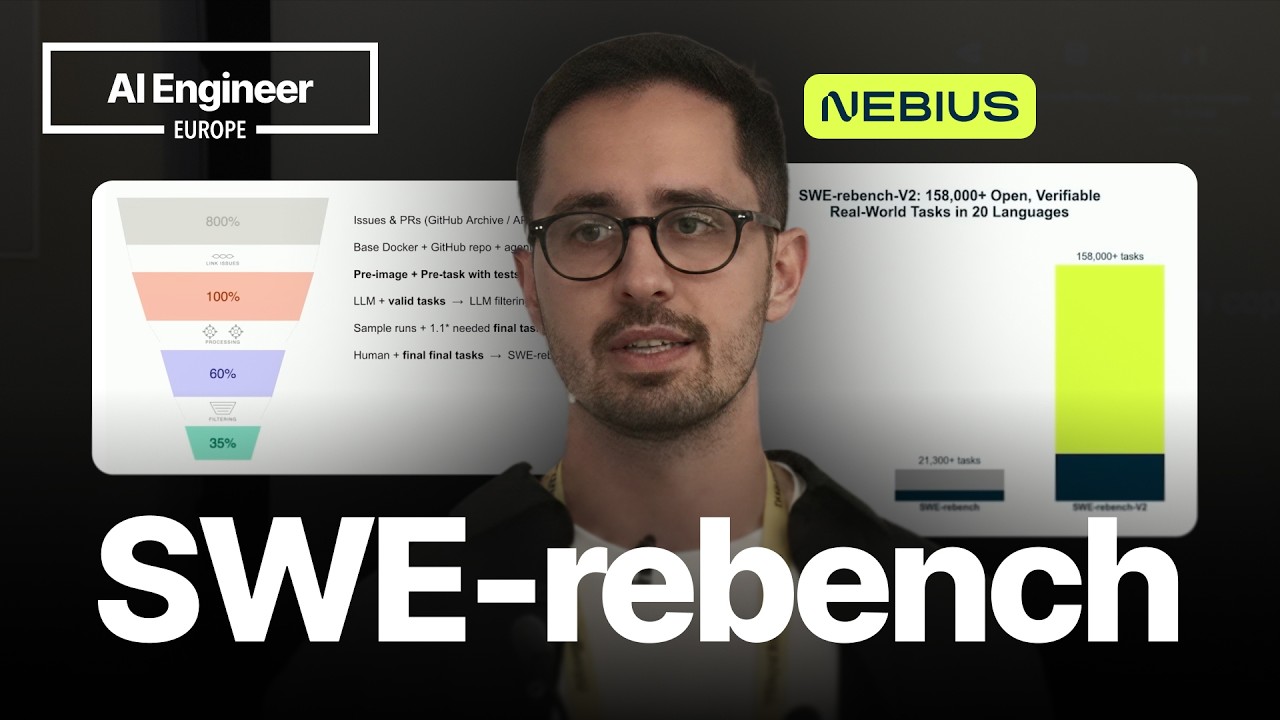
SWE-rebench: Lessons from Evaluating Coding Agents — Ibragim Badertdinov, Nebius

Ibragim Badertdinov from Nebius AI shares lessons from building and maintaining SWE-ReBench, a monthly leaderboard that evaluates coding agents on fresh, real-world software engineering tasks. The talk covers the anatomy of a good benchmark task, the challenges of filtering out noisy or flawed problems, and fascinating examples of how advanced models like Claude Code "cheat" by exploiting the environment. Finally, it explains how the same pipeline used for evaluation has produced large-scale, high-quality training datasets like SWE-bench, used by frontier AI labs.