RLL m

Small Models, Big Results: Training a Finance Agent for Under $500 — Charles Dickens, Snorkel AI

Small Models, Big Results: Training a Finance Agent for Under $500 — Charles Dickens, Snorkel AI

Snorkel AI and UC Berkeley's Sky Computing Lab show that a 4B Qwen3 model, trained with reinforcement learning for under $500 using the rLLM framework, beats its 235B sibling on expert-validated financial question answering built from SEC 10-K filings. The talk covers the FinQA dataset construction and verification, common failure modes of frontier models, transfer to multi-table and general tool-use tasks, and ablations showing that simple data and binary rewards outperform more elaborate setups, since the real bottleneck is disciplined tool use rather than reasoning depth.
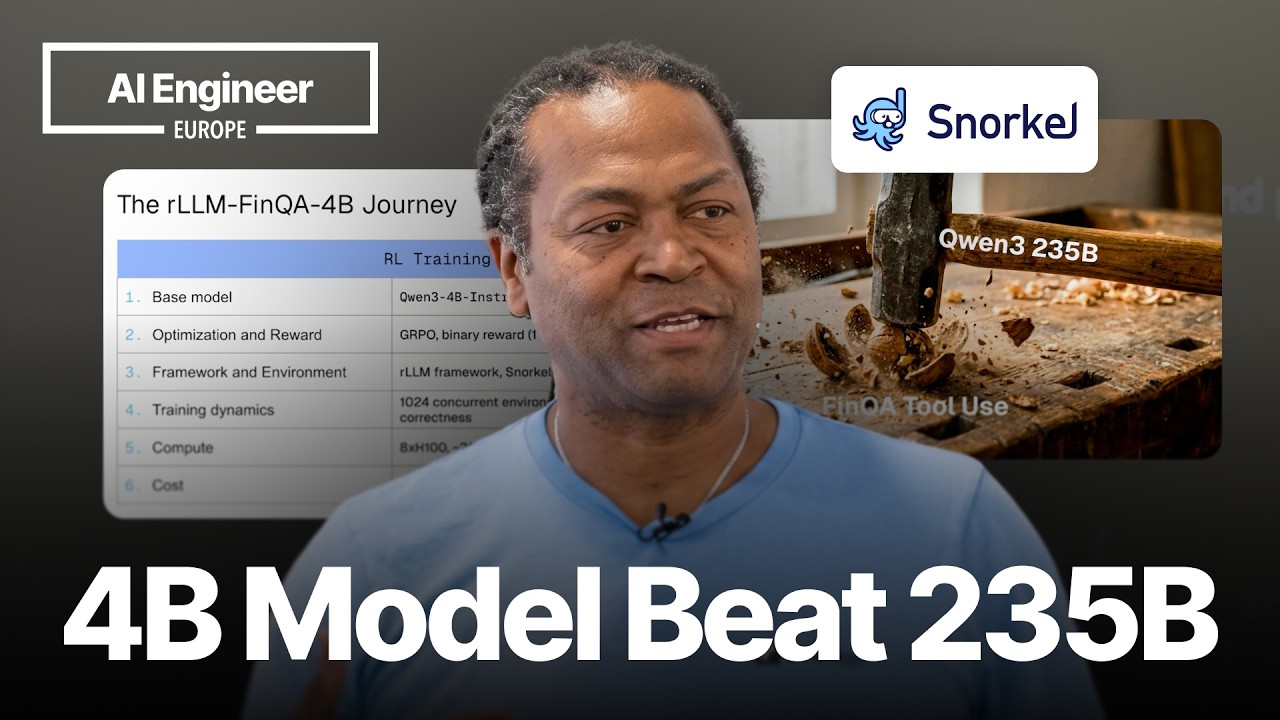
Stop Making Models Bigger, Make Them Behave — Kobie Crawdord, Snorkel

Stop Making Models Bigger, Make Them Behave — Kobie Crawdord, Snorkel

Snorkel.ai's research demonstrates how a 4-billion-parameter model, fine-tuned with Reinforcement Learning for under $500, significantly outperformed a 235-billion-parameter model on financial analysis tool-use tasks. The key was cultivating 'tool discipline' and error correction capabilities, rather than relying on sheer model size or deeper reasoning. Single-table training generalized effectively to harder multi-table problems, emphasizing the importance of targeted behavioral fixes identified through detailed evaluation rubrics.