Ray

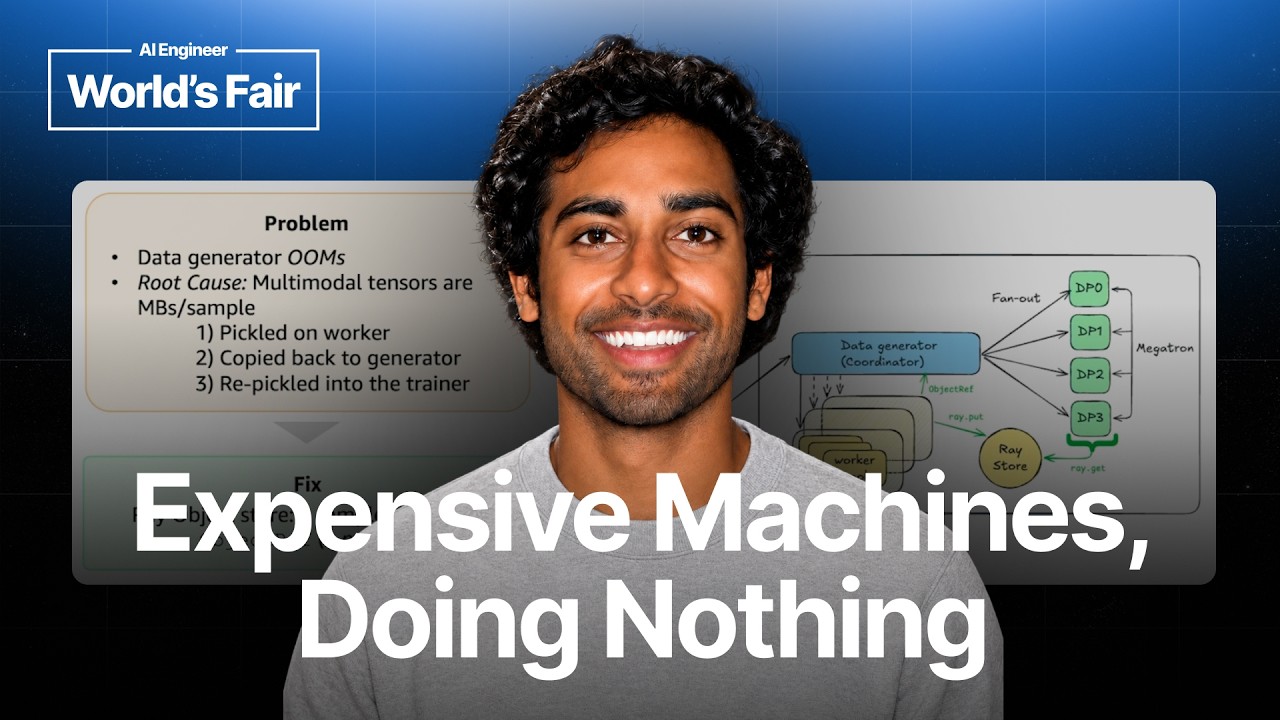
From 15% to 90% GPU Utilization: Fix the Data Pipeline, Not the Model

From 15% to 90% GPU Utilization: Fix the Data Pipeline, Not the Model

Tarun Sunkaraneni from Amazon AGI shows how a multimodal SFT pipeline that spent about 85% of its time waiting on data was brought to roughly 90% GPU utilization. He walks through concurrency with asyncio and Ray actors, prefetching, zero-copy transfer via Ray's object store, and a network-card bottleneck that appears only at scale, and argues that the hardest part of training throughput is often keeping GPUs fed rather than optimizing the model.
Underwriting Assist - A Multi Agent System // Somya Rai | Maria Zhang // Agents in Production 2025

Underwriting Assist - A Multi Agent System // Somya Rai | Maria Zhang // Agents in Production 2025

Maria Zhang, CEO of Palona AI, and Somya Rai, Principal AI Engineer at EXL, discuss the architecture, scaling, memory management, and cost optimization of multi-agent systems in their respective domains of restaurants and insurance. They explore practical challenges, such as real-world bottlenecks and regulatory compliance, and share their technical stacks, including LangGraph, Ray, and NVIDIA platforms, for building robust and efficient agentic solutions.