Rag

Stop Chunking Like It's 2022 — Yuval Belfer, AI21 Labs

Stop Chunking Like It's 2022 — Yuval Belfer, AI21 Labs

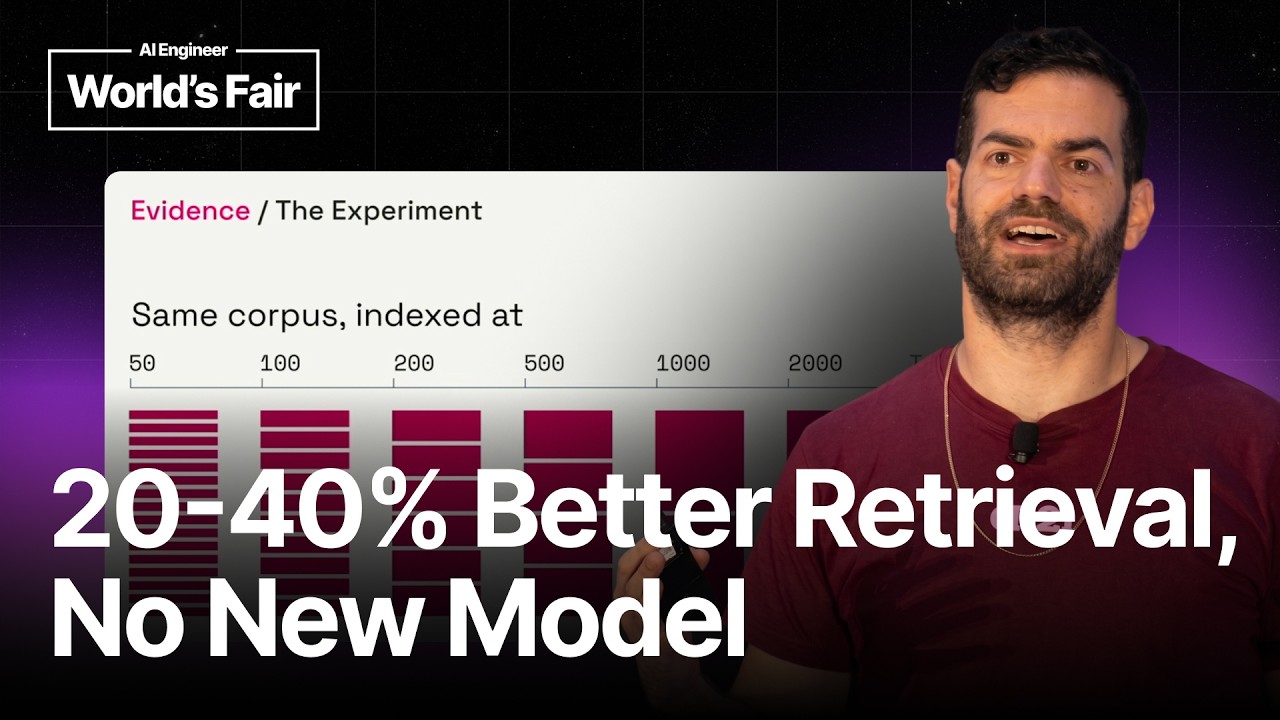
Yuval Belfer addresses the fundamental challenge in Retrieval Augmented Generation (RAG): the optimal chunk size is query-dependent, but chunking decisions are fixed during indexing. This "information problem" leads to significant recall loss, as shown by experiments demonstrating a 20-40% gap between fixed chunking and an oracle. His proposed solution, multiscale indexing, involves creating multiple document copies with different chunk sizes, querying all of them, retrieving whole documents, and merging results using Reciprocal Rank Fusion, yielding substantial recall improvements with minimal latency increase.
If we want them to do Knowledge Work, design them as Knowledge Agents — Benjamin Clavié, Mixedbread

If we want them to do Knowledge Work, design them as Knowledge Agents — Benjamin Clavié, Mixedbread

Benjamin Clavié argues that the industry has mistakenly generalized from the "easy case" of coding agents to the much harder domain of general knowledge work. He highlights that code offers durable, explicit cues and narrow tasks, while knowledge work involves implicit meaning, contextual understanding, and agents needing to reconstruct intent. Clavié traces human solutions through "tool loops" and "organization loops," demonstrating how optimized tools and hierarchical agentic structures (like searcher agents generating memos) are essential to overcome performance ceilings and significantly bridge the "oracle gap" between AI and human knowledge workers.

Essential Skills for Becoming an AI Engineer: RAG, AI Agents, & More

Essential Skills for Becoming an AI Engineer: RAG, AI Agents, & More

Cedric Clyburn outlines the essential skills for AI engineering, distinguishing it from ML research. He details a three-tier skill stack covering foundational programming (Python, Git, APIs), AI-specific techniques (embeddings, RAG, AI agents), and deployment strategies (containerization, observability). The discussion emphasizes judgment over code generation and highlights key use cases like RAG systems and agent-based solutions.

Your agents lack context: Here's how to fix "You're absolutely right!" — Brandon Waselnuk, Unblocked

Your agents lack context: Here's how to fix "You're absolutely right!" — Brandon Waselnuk, Unblocked

Brandon Waselnuk of Unblocked discusses the critical need for robust context engines in AI-driven software development. He explains how AI agents' lack of company-specific understanding leads to compounding costs like wasted tokens and rework. Waselnuk outlines common pitfalls in providing context and details six essential characteristics of an effective context engine, demonstrating its impact with a 50% token reduction and significant time savings. He also introduces three open-source tools from Unblocked, including a workshop to build a relational context engine, emphasizing that "access to information is not understanding" and that context, not intelligence, is the current bottleneck for AI effectiveness.

In Case You Missed It in August 2026 (Ep. 1024 with Jon Krohn)

In Case You Missed It in August 2026 (Ep. 1024 with Jon Krohn)

This episode explores the critical gap between AI investment and return, featuring insights from industry leaders. It covers why most organizations fail to see ROI from AI, the crucial role of mathematical optimization in agentic AI to ensure constraint adherence, practical strategies for structuring AI skills in tools like Claude for quality output, and a 10-20-70 budget framework emphasizing upskilling. Additionally, it delves into the growing importance of the semantic layer for analytics agents to ensure consistent data interpretation and efficiency in large enterprises.

Agentic Sites: Building Hyper Personalized Websites — Carlos Sanchez, Adobe

Agentic Sites: Building Hyper Personalized Websites — Carlos Sanchez, Adobe

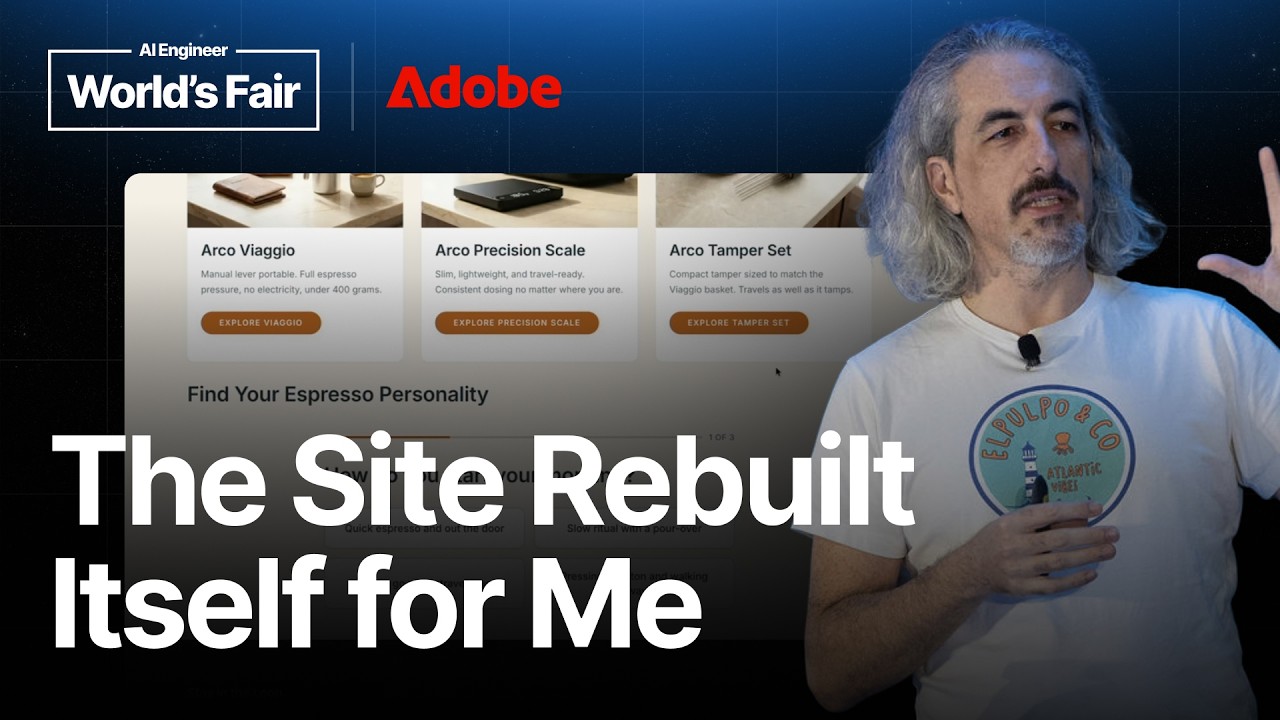
Carlos Sanchez from Adobe presents "Agility Sites," a novel approach to building hyper-personalized websites in real-time. By dynamically generating specific content blocks and grounding responses in the site's corpus, these sites achieve an "audience of one" experience. Key innovations include rapid LLM inference (1.1s average latency with Cerebras), continuous model evaluation for speed and accuracy, and leveraging user intent to deliver tailored content, as demonstrated by an on-the-fly camping coffee machine page and an AI conference comparison site.