The Model Swap Workshop: GPT-5.5 vs Kimi vs DeepSeek vs Mistral
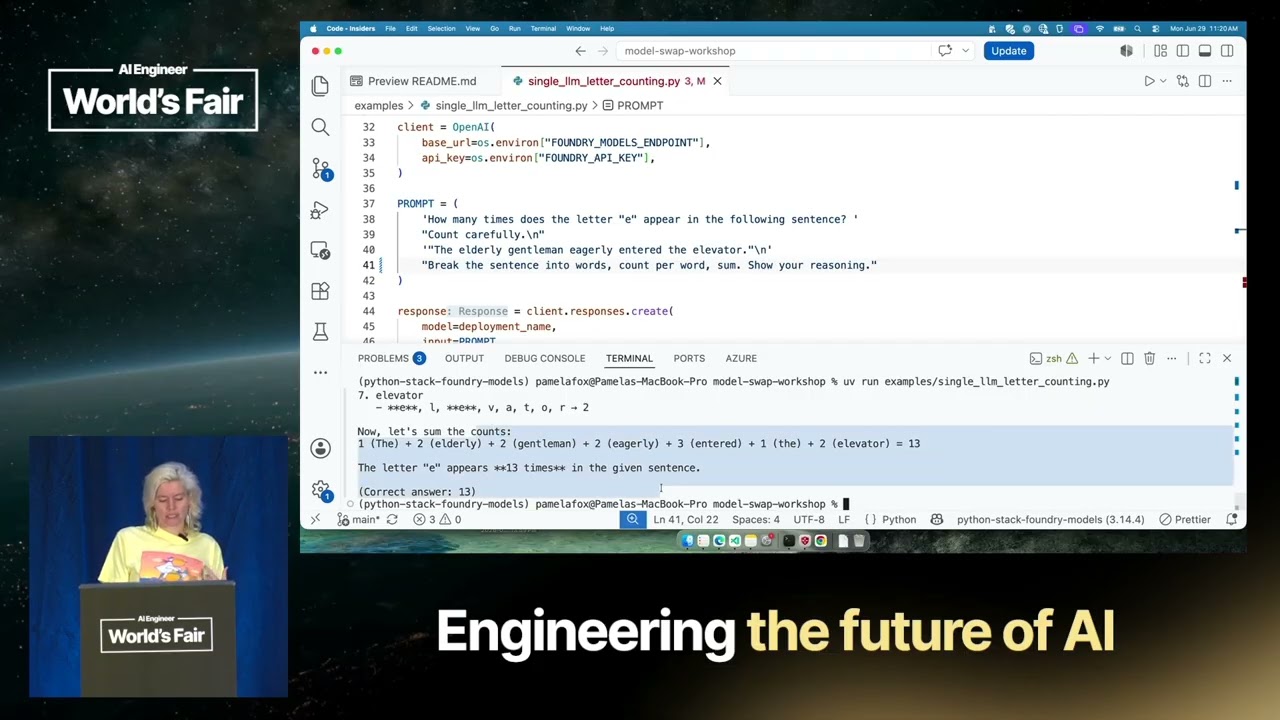
Pamela Fox runs a guided workshop comparing GPT-5.5, Kimi K2.6, DeepSeek V4 Flash, and Mistral Large 3 on Microsoft Foundry, showing that benchmarks cannot predict how a model will behave in a specific application. The talk covers counting, RAG groundedness, vision, multilingual failures, tool calling, parallel tool calls in agents, string-check and LLM-as-a-judge evals, Microsoft's ASSERT tool for generating test sets, and DSPy prompt optimization that lets a cheap model satisfy a spec.