Prompt optimization

The Model Swap Workshop: GPT-5.5 vs Kimi vs DeepSeek vs Mistral

The Model Swap Workshop: GPT-5.5 vs Kimi vs DeepSeek vs Mistral

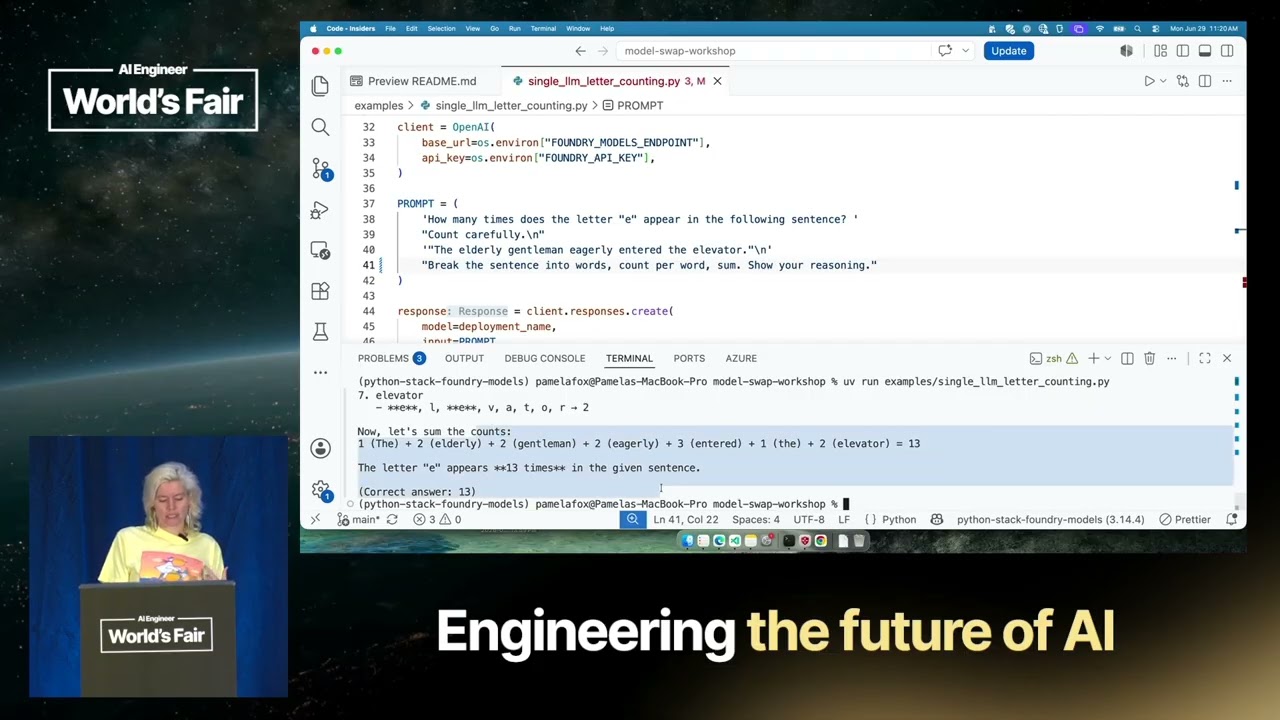
Pamela Fox runs a guided workshop comparing GPT-5.5, Kimi K2.6, DeepSeek V4 Flash, and Mistral Large 3 on Microsoft Foundry, showing that benchmarks cannot predict how a model will behave in a specific application. The talk covers counting, RAG groundedness, vision, multilingual failures, tool calling, parallel tool calls in agents, string-check and LLM-as-a-judge evals, Microsoft's ASSERT tool for generating test sets, and DSPy prompt optimization that lets a cheap model satisfy a spec.
Beating RL With Reflection: GEPA and Optimize Anything — Lakshya A. Agrawal, GEPA

Beating RL With Reflection: GEPA and Optimize Anything — Lakshya A. Agrawal, GEPA

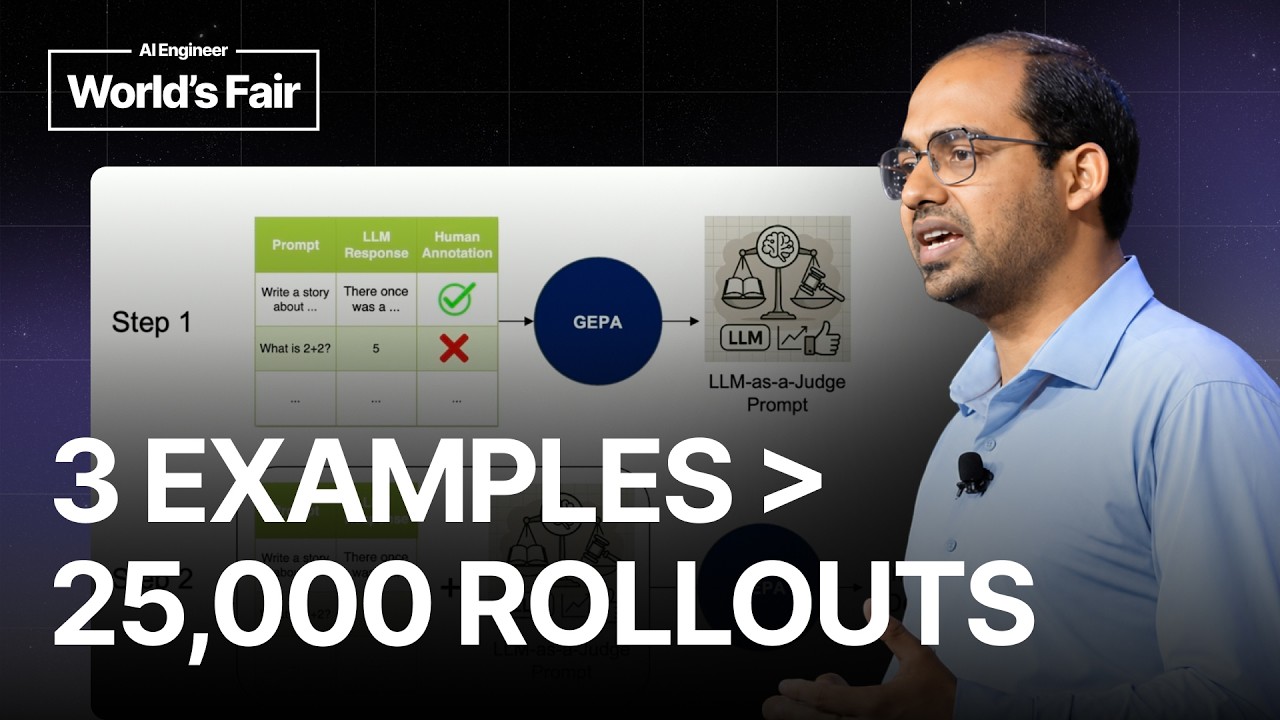
Lakshya Agrawal, creator of GEPA and a PhD student at UC Berkeley's Sky Computing Lab, presents reflective optimization as an alternative to scalar-reward reinforcement learning. GEPA lets a model read full rollout traces, including reasoning, tool calls, and error messages, and rewrite prompts from that feedback, with a Pareto candidate pool guarding against local optima. The talk covers the GEPA vs. GRPO sample-efficiency comparison, domain-knowledge discovery, the Optimize Anything API for text-based artifacts like code, harnesses, and skills, and production results from Databricks, Snorkel, and others.

Judge the Judge: Building LLM Evaluators That Actually Work with GEPA — Mahmoud Mabrouk, Agenta AI

Judge the Judge: Building LLM Evaluators That Actually Work with GEPA — Mahmoud Mabrouk, Agenta AI

This workshop by Mahmoud Mabrouk, CEO of Agenta AI, delves into building calibrated LLM-as-a-judge evaluations that reliably align with human judgment. It highlights how miscalibrated judges lead to false confidence and presents a practical workflow, including designing use-case specific metrics, detailed data annotation, and optimizing judge prompts using the GAPA algorithm. The talk emphasizes the importance of iterative debugging, model selection, and custom reflection templates for achieving trustworthy and effective LLM evaluations.

DSPy: The End of Prompt Engineering - Kevin Madura, AlixPartners

DSPy: The End of Prompt Engineering - Kevin Madura, AlixPartners

An in-depth guide to DSPy, a framework for programming with language models, not just prompting them. Learn its core concepts—Signatures, Modules, Adapters, and Optimizers—and see real-world examples of building robust, testable, and transferable AI applications for the enterprise.

Continual System Prompt Learning for Code Agents – Aparna Dhinakaran, Arize

Continual System Prompt Learning for Code Agents – Aparna Dhinakaran, Arize

The talk by Aparna Dhinakaran introduces "system prompt learning" as an efficient alternative to traditional Reinforcement Learning for improving large language model-based coding agents. By leveraging LLM-as-a-judge evaluations to generate English feedback and explanations for code failures, agents can automatically refine their system prompts and rules. This method, demonstrated on Claude and Klein, significantly boosts performance on benchmarks like SWEBench with minimal data, highlighting the critical role of high-quality evaluation prompts.