Production ai

An AI Agent Got Its User Banned From Resy — Keycard, JPMorgan Chase & AAuth

An AI Agent Got Its User Banned From Resy — Keycard, JPMorgan Chase & AAuth

A panel of experts discusses the challenges of granting autonomy to AI agents due to coarse-grained authorization systems. They advocate for intent-based runtime authorization, leveraging concepts like "missions" and "budgets" from AOTH, brain-hands architecture, and dynamic policy management. The discussion covers agentic commerce, accountability through tamper-resistant audit logs, and whether P(doom) is a real threat, emphasizing engineering ingenuity and societal learning from failures.
Why 80% Reliability Isn't Good Enough — Felipe Blanes, Amazon AGI Lab

Why 80% Reliability Isn't Good Enough — Felipe Blanes, Amazon AGI Lab

Felipe Blanes from the Amazon AGI Lab shares lessons from working directly with customers of Nova Act, Amazon's browser agent service, from research preview to general availability on AWS. He argues that static benchmarks leave teams hoping their evals match real usage, and proposes a customer-driven eval flywheel, the trust cliff around 90% reliability, the value of being open about limits, and principles for keeping evals fresh.

The 6 Pillars of an Agentic Harness for Production — Varun Krovvidi, Resolve AI

The 6 Pillars of an Agentic Harness for Production — Varun Krovvidi, Resolve AI

Varun Krovvidi of Resolve AI explains why AI excels at code generation but struggles with the complex, multi-domain problem of running and fixing software in production. He outlines five common failure modes for AI agents in production (anchoring bias, context issues, coherent vs. causal answers, guardrails, lack of learning) and introduces Resolve AI's six-pillar architecture: model orchestration, context engineering, causal reasoning, governed actions, learning systems, and multi-level evaluations. A demo illustrates how Resolve AI diagnoses a Grafana alert to its root cause, ruling out coincidental events and maintaining its causal reasoning.

Advanced Workshop: Mastering AI Observability — Doug Guthrie, Braintrust

Advanced Workshop: Mastering AI Observability — Doug Guthrie, Braintrust

Doug Guthrie showcases how Braintrust connects observability with AI agent improvement. Using a support agent, he demonstrates setting up tracing, establishing evaluation baselines, and publishing custom scorers. The workshop delves into Braintrust's Topics feature for discovering unknown failure modes, configuring online automations, and importing real-world traces. A key focus is on automating the improvement cycle: using the Loop assistant for SQL-based trace analysis, integrating coding agents with Braintrust CLI skills to propose code changes, add regressions, run evals, and generate pull requests, thereby closing the feedback loop from production to development.

The Frontier AI Inference Cloud for Agents — Byung-Gon (Gon) Chun, FriendliAI

The Frontier AI Inference Cloud for Agents — Byung-Gon (Gon) Chun, FriendliAI

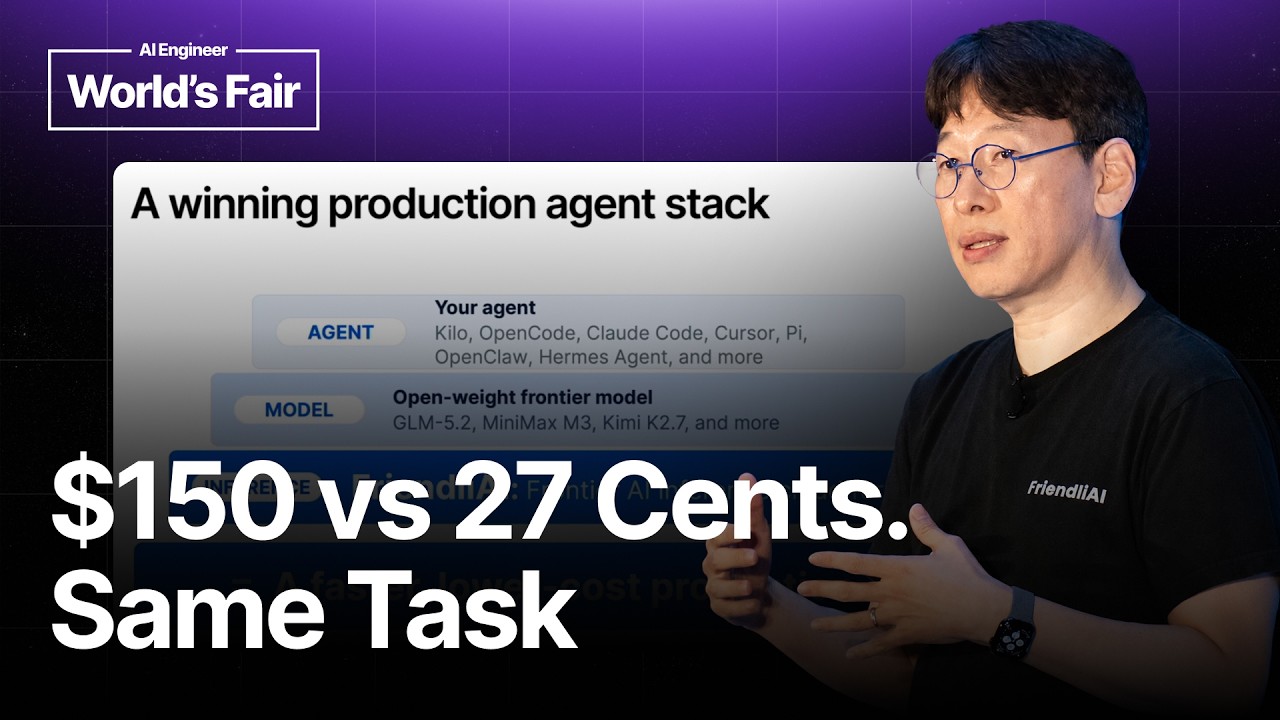
Byung-Gon Chun from FriendliAI details how agentic inference fundamentally differs from traditional chat-based LLM usage, requiring a specialized infrastructure to optimize for end-to-end task completion rather than single request latency. He highlights the economic advantage of open-weight models for agentic workflows and explains FriendliAI's innovative inference stack, featuring prefix caching, advanced KV cache management, cache-aware routing, and agent-aware optimization, which together deliver significant speedups and cost savings for production AI agents.

Your Agent Didn't Fail. Your Harness Did. — Vinoth Govindarajan, OpenAI

Your Agent Didn't Fail. Your Harness Did. — Vinoth Govindarajan, OpenAI

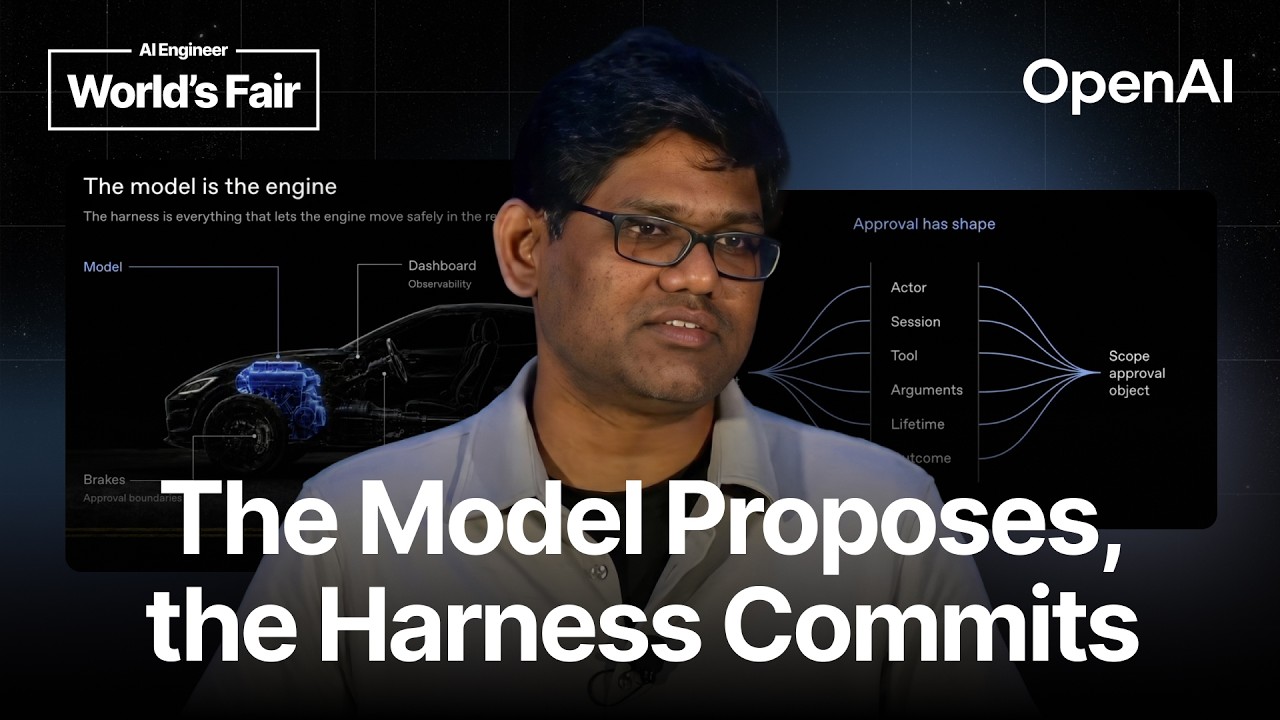
Vinoth Govindarajan's talk addresses critical 'harness failures' in AI agents, arguing these, rather than model errors, are the root cause of most production incidents. He introduces the core contract: 'A model proposes, the harness commits, and a receipt proves it,' and outlines five key boundaries (state ownership, ordering, deadlines, authority, user-visible proof) that lead to failures like silent success and incomplete reality. The talk culminates in a practical 'run receipt audit' with five questions to diagnose and ensure reliable agent behavior.